 youcef zr
86f53e649e
* fix(worker): classify Anthropic 400 invalid_request_error as unrecoverable when .status is dropped by SDK wrapping (#2656)

The Anthropic Agent SDK sometimes surfaces 400 invalid_request errors as
wrapped exceptions where the `.status` field is lost in the wrapping —
only the canonical message text (or a structured `error.type ===
'invalid_request_error'`) survives.

Before this fix the existing `errAny.status === 400` branch in
`classifyClaudeError` was the only guard; without `.status` the error
fell through to the default `transient` branch and the worker retried
the same permanent configuration error indefinitely while `/health`
kept reporting `ok` — exactly the symptom reported in #2656 for
"The provided model identifier is invalid".

Add a conservative message-anchored fallback that catches three
canonical shapes:

  - `error.type === 'invalid_request_error'` (Anthropic API body shape)
  - the canonical phrase "the provided model identifier is invalid"
  - any message that carries `invalid_request_error` as a token

Anchored on full phrases / `\b` word boundaries so unrelated messages
containing the word "invalid" still classify as `transient` (verified
by a regression test). The pre-existing `.status === 400` branch
continues to handle statused 400s first, so the effort-hint logging
path for #2357 is untouched.

Adds 5 regression tests; the existing 7 still pass.

* fix(worker): guard status-less invalid_request_error branch against statused 5xx (#2656)

Addresses the Greptile review on #2673. The status-less invalid_request_error
fallback ran before the 5xx branch with no status guard, so an error carrying
`status: 5xx` plus an `invalid_request_error` body/message was classified
`unrecoverable` and halted retries for what is a transient server error.

Add `typeof errAny.status !== 'number'` so the branch only handles genuinely
status-less errors (its stated intent); statused 4xx/5xx stay on their own
branches. Also trims the 7-line block comment down to match the one-line
comment style of the sibling branches in classifyClaudeError.

Adds a regression test: status 503 + invalid_request_error body -> transient.

Co-Authored-By: Claude Opus 4.7 (1M context) <noreply@anthropic.com>

---------

Co-authored-by: youcefzemmar <dzbuildoff@gmail.com>
Co-authored-by: Claude Opus 4.7 (1M context) <noreply@anthropic.com>
🇨🇳 中文 • 🇹🇼 繁體中文 • 🇯🇵 日本語 • 🇵🇹 Português • 🇧🇷 Português • 🇰🇷 한국어 • 🇪🇸 Español • 🇩🇪 Deutsch • 🇫🇷 Français • 🇮🇱 עברית • 🇸🇦 العربية • 🇷🇺 Русский • 🇵🇱 Polski • 🇨🇿 Čeština • 🇳🇱 Nederlands • 🇹🇷 Türkçe • 🇺🇦 Українська • 🇻🇳 Tiếng Việt • 🇵🇭 Tagalog • 🇮🇩 Indonesia • 🇹🇭 ไทย • 🇮🇳 हिन्दी • 🇧🇩 বাংলা • 🇵🇰 اردو • 🇷🇴 Română • 🇸🇪 Svenska • 🇮🇹 Italiano • 🇬🇷 Ελληνικά • 🇭🇺 Magyar • 🇫🇮 Suomi • 🇩🇰 Dansk • 🇳🇴 Norsk
Persistent memory compression system built for Claude Code.


|
|
Quick Start • How It Works • Search Tools • Documentation • Configuration • Troubleshooting • License
Claude-Mem seamlessly preserves context across sessions by automatically capturing tool usage observations, generating semantic summaries, and making them available to future sessions. This enables Claude to maintain continuity of knowledge about projects even after sessions end or reconnect.
Quick Start
Install with a single command:
npx claude-mem install
Or install for Gemini CLI (auto-detects ~/.gemini):
npx claude-mem install --ide gemini-cli
Or install for OpenCode:
npx claude-mem install --ide opencode
Or install from the plugin marketplace inside Claude Code:
/plugin marketplace add thedotmack/claude-mem

/plugin install claude-mem
Restart Claude Code or Gemini CLI. Context from previous sessions will automatically appear in new sessions.
Note: Claude-Mem is also published on npm, but
npm install -g claude-meminstalls the SDK/library only — it does not register the plugin hooks or set up the worker service. Always install vianpx claude-mem installor the/plugincommands above.
🦞 OpenClaw Gateway
Install claude-mem as a persistent memory plugin on OpenClaw gateways with a single command:
curl -fsSL https://install.cmem.ai/openclaw.sh | bash
The installer handles dependencies, plugin setup, AI provider configuration, worker startup, and optional real-time observation feeds to Telegram, Discord, Slack, and more. See the OpenClaw Integration Guide for details.
Key Features:
- 🧠 Persistent Memory - Context survives across sessions
- 📊 Progressive Disclosure - Layered memory retrieval with token cost visibility
- 🔍 Skill-Based Search - Query your project history with mem-search skill
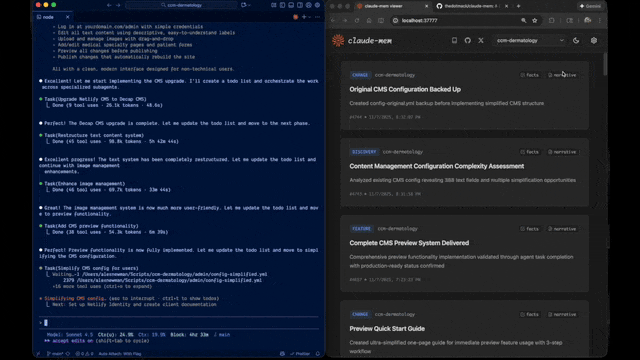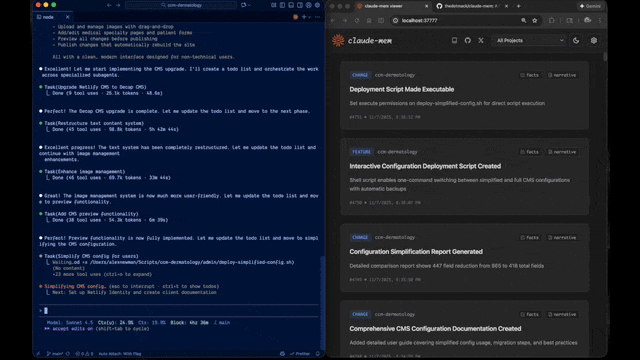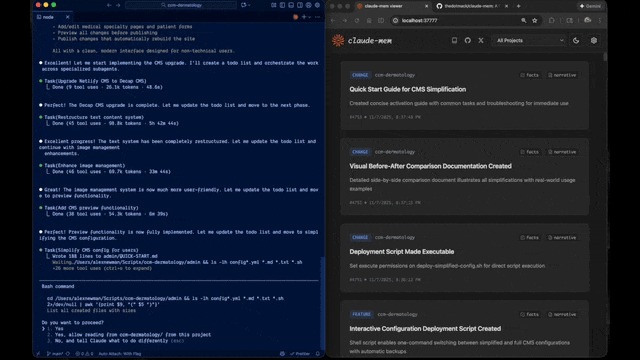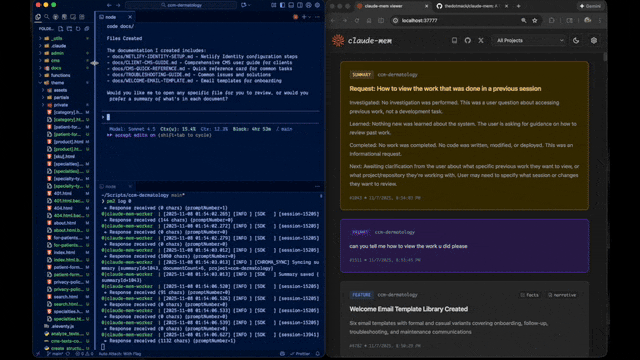
- 🖥️ Web Viewer UI - Real-time memory stream at http://localhost:37777
- 💻 Claude Desktop Skill - Search memory from Claude Desktop conversations
- 🔒 Privacy Control - Use
<private>tags to exclude sensitive content from storage - ⚙️ Context Configuration - Fine-grained control over what context gets injected
- 🤖 Automatic Operation - No manual intervention required
- 🔗 Citations - Reference past observations with IDs (access via http://localhost:37777/api/observation/{id} or view all in the web viewer at http://localhost:37777)
- 🧪 Beta Channel - Try experimental features like Endless Mode via version switching
Documentation
📚 View Full Documentation - Browse on official website
Getting Started
- Installation Guide - Quick start & advanced installation
- Gemini CLI Setup - Dedicated guide for Google's Gemini CLI integration
- Usage Guide - How Claude-Mem works automatically
- Search Tools - Query your project history with natural language
- Beta Features - Try experimental features like Endless Mode
Best Practices
- Context Engineering - AI agent context optimization principles
- Progressive Disclosure - Philosophy behind Claude-Mem's context priming strategy
Architecture
- Overview - System components & data flow
- Architecture Evolution - The journey from v3 to v5
- Hooks Architecture - How Claude-Mem uses lifecycle hooks
- Hooks Reference - 7 hook scripts explained
- Worker Service - HTTP API & Bun management
- Database - SQLite schema & FTS5 search
- Search Architecture - Hybrid search with Chroma vector database
Configuration & Development
- Configuration - Environment variables & settings
- Development - Building, testing, contributing
- Troubleshooting - Common issues & solutions
How It Works
Core Components:
- 5 Lifecycle Hooks - SessionStart, UserPromptSubmit, PostToolUse, Stop, SessionEnd (6 hook scripts)
- Smart Install - Cached dependency checker (pre-hook script, not a lifecycle hook)
- Worker Service - HTTP API on port 37777 with web viewer UI and 10 search endpoints, managed by Bun
- SQLite Database - Stores sessions, observations, summaries
- mem-search Skill - Natural language queries with progressive disclosure
- Chroma Vector Database - Hybrid semantic + keyword search for intelligent context retrieval
See Architecture Overview for details.
MCP Search Tools
Claude-Mem provides intelligent memory search through 4 MCP tools following a token-efficient 3-layer workflow pattern:
The 3-Layer Workflow:
search- Get compact index with IDs (~50-100 tokens/result)timeline- Get chronological context around interesting resultsget_observations- Fetch full details ONLY for filtered IDs (~500-1,000 tokens/result)
How It Works:
- Claude uses MCP tools to search your memory
- Start with
searchto get an index of results - Use
timelineto see what was happening around specific observations - Use
get_observationsto fetch full details for relevant IDs - ~10x token savings by filtering before fetching details
Available MCP Tools:
search- Search memory index with full-text queries, filters by type/date/projecttimeline- Get chronological context around a specific observation or queryget_observations- Fetch full observation details by IDs (always batch multiple IDs)
Example Usage:
// Step 1: Search for index
search(query="authentication bug", type="bugfix", limit=10)

// Step 2: Review index, identify relevant IDs (e.g., #123, #456)

// Step 3: Fetch full details
get_observations(ids=[123, 456])
See Search Tools Guide for detailed examples.
Beta Features
Claude-Mem offers a beta channel with experimental features like Endless Mode (biomimetic memory architecture for extended sessions). Switch between stable and beta versions from the web viewer UI at http://localhost:37777 → Settings.
See Beta Features Documentation for details on Endless Mode and how to try it.
System Requirements
- Node.js: 18.0.0 or higher
- Claude Code: Latest version with plugin support
- Bun: JavaScript runtime and process manager (auto-installed if missing)
- uv: Python package manager for vector search (auto-installed if missing)
- SQLite 3: For persistent storage (bundled)
Windows Setup Notes
If you see an error like:
npm : The term 'npm' is not recognized as the name of a cmdlet
Make sure Node.js and npm are installed and added to your PATH. Download the latest Node.js installer from https://nodejs.org and restart your terminal after installation.
Configuration
Settings are managed in ~/.claude-mem/settings.json (auto-created with defaults on first run). Configure AI model, worker port, data directory, log level, and context injection settings.
See the Configuration Guide for all available settings and examples.
Mode & Language Configuration
Claude-Mem supports multiple workflow modes and languages via the CLAUDE_MEM_MODE setting.
This option controls both:
- The workflow behavior (e.g. code, chill, investigation)
- The language used in generated observations
How to Configure
Edit your settings file at ~/.claude-mem/settings.json:
{
  "CLAUDE_MEM_MODE": "code--zh"
}
Modes are defined in plugin/modes/. To see all available modes locally:
ls ~/.claude/plugins/marketplaces/thedotmack/plugin/modes/
Available Modes
| Mode | Description |
|---|---|
code |
Default English mode |
code--zh |
Simplified Chinese mode |
code--ja |
Japanese mode |
Language-specific modes follow the pattern code--[lang] where [lang] is the ISO 639-1 language code (e.g., zh for Chinese, ja for Japanese, es for Spanish).
Note:
code--zh(Simplified Chinese) is already built-in — no additional installation or plugin update is required.
After Changing Mode
Restart Claude Code to apply the new mode configuration.
Development
See the Development Guide for build instructions, testing, and contribution workflow.
Troubleshooting
If experiencing issues, describe the problem to Claude and the troubleshoot skill will automatically diagnose and provide fixes.
See the Troubleshooting Guide for common issues and solutions.
Bug Reports
Create comprehensive bug reports with the automated generator:
cd ~/.claude/plugins/marketplaces/thedotmack
npm run bug-report
Contributing
Contributions are welcome! Please:
- Fork the repository
- Create a feature branch
- Make your changes with tests
- Update documentation
- Submit a Pull Request
See Development Guide for contribution workflow.
License
Claude-Mem is licensed under the Apache License 2.0.
We chose Apache-2.0 because durable agentic memory should be easy to embed in developer tools, local agents, MCP servers, enterprise systems, robotics stacks, and production agent harnesses.
See the LICENSE file for full details. See docs/license.md and docs/ip-boundary.md for licensing scope and the open/commercial boundary.
Note on Ragtime: The ragtime/ directory is licensed under the Apache License 2.0. See ragtime/LICENSE for details.
Support
- Documentation: docs/
- Issues: GitHub Issues
- Repository: github.com/thedotmack/claude-mem
- Official X Account: @Claude_Memory
- Official Discord: Join Discord
- Author: Alex Newman (@thedotmack)
Built with Claude Agent SDK | Works with Claude Code | Made with TypeScript
What About $CMEM?
$CMEM is a solana token created by a 3rd party without Claude-Mem's prior consent, but officially embraced by the creator of Claude-Mem (Alex Newman, @thedotmack). The token acts as a community catalyst for growth and a vehicle for bringing real-time agent data to the developers and knowledge workers that need it most. $CMEM: 2TsmuYUrsctE57VLckZBYEEzdokUF8j8e1GavekWBAGS