 Alex Newman
1e284feb05
* fix(context): fit the session block to the hook output limit by selection

Claude Code delivers a hook's stdout verbatim up to 10,000 characters, then
writes the whole block to disk and hands the model a ~2KB preview stub
instead -- while the hook still reports success. The context block was sized
by item counts, so on an active project it crossed that line and the model
silently received no context at all.

Counts cannot fix it: an observation title runs ~150-320 characters, a
session-summary line ~250-600, and the last-session summary block 1-5K on its
own, so any count safe on a quiet project wastes the budget and any count
that fills the budget there overflows on a busy one. The shipped default of
50 observations overflows on titles alone.

Measure instead. Render, and while the result is over budget drop the most
expensive thing still in it and render again: full narratives first (their
titles stay), then the last-session summary block, then sessions, then
observations. Whole items go, never half of one, so the block stays
well-formed and the header, footer and at least one observation survive.

--full is an explicit human request and is left unbounded.

Fixes #3802

* fix(context): count the health warning and report what was delivered

Addresses the three P1 findings on this PR. All three were real; the first two
are fixed here with tests, the third by rebuilding the two bundles that
actually carry the change.

**The observer-health warning is now inside the measured block.** It was
appended to the already-fitted text, so its characters were never counted: a
block fitted to 9,998 came back at 10,585 whenever the observer was unhealthy,
and over the limit Claude Code replaces the whole thing with the ~2KB preview
stub — losing the context *and* the outage warning, which is exactly when that
warning matters most.

`readObserverHealth` is now read once rather than per render. `fitContextToBudget`
calls its render repeatedly and that function touches state; re-reading it per
reduction would let the measured length move under the loop.

**Injection stats now describe the delivered block.** A run trimmed from seven
observations to three still reported `observation_count: 7` and 9,646 tokens
injected while the model received three observations and 4,134 tokens. That is
the one direction this telemetry must not be wrong in — it read as healthy
precisely when context was being dropped. `ContextInjectStats` already promised
this ("computed from the same observation set that was rendered"); the code now
matches its own contract. Summaries use `budget.config.sessionCount`, the same
slice `buildContextOutput` takes for `displaySummaries`.

Both live in a new exported `fitContextForDelivery`, split out of
`generateContextWithStats` so the fitting and the reporting can be tested
without a database — the module previously had no in-process test path at all,
which is why neither defect was caught.

**Bundles.** `plugin/scripts/worker-service.cjs` and
`plugin/scripts/context-generator.cjs` are rebuilt: marketplace hooks execute
the checked-in bundle, so the fix does not reach installs without them.

`mcp-server.cjs` and `server-service.cjs` are deliberately NOT included, and
that is measured rather than assumed. Rebuilding them from a clean tree
produces byte-identical output to rebuilding them with this patch applied, and
both differ from what is committed on `main` — so their diff is pre-existing
drift, not this change, and carrying it here would bury the review in noise.

Five cases in `tests/context/context-budget-3802.test.ts`, driven through
`fitContextForDelivery` rather than through `fitContextToBudget`, because both
defects were in what happens *around* the fitter.

The fixture is chosen so it can tell the two apart: 47 observations render to
9,900 characters, which fits, and 9,900 plus a 600-character warning does not.
An earlier version of this test used 50 observations and **passed under the
mutation** — the fitter's reductions are coarse, so the fitted block landed far
enough below the limit that a warning appended afterwards still fit. Measured,
then fixed.

- Moving the warning back outside the fitter fails
  `counts the observer-health warning against the budget`.
- Passing the original arrays to `buildInjectStats` fails two of the stats cases.

`bun test tests/context/` gives 83 pass / 4 fail; the four are
`context database ownership`, which fail identically on `main` (a child-process
stdout JSON parse, unrelated to this change). `bun run typecheck:root`,
`lint:hook-io` and `lint:spawn-env` are clean.

Co-authored-by: Alex Newman <thedotmack@users.noreply.github.com>

---------

Co-authored-by: Nguyen Thanh Dat <ntdat812@gmail.com>
Co-authored-by: Alex Newman <thedotmack@users.noreply.github.com>


Claude-Mem is now Grok Mem. The package is still claude-mem.
🇨🇳 中文 • 🇹🇼 繁體中文 • 🇯🇵 日本語 • 🇵🇹 Português • 🇧🇷 Português • 🇰🇷 한국어 • 🇪🇸 Español • 🇩🇪 Deutsch • 🇫🇷 Français • 🇮🇱 עברית • 🇸🇦 العربية • 🇷🇺 Русский • 🇵🇱 Polski • 🇨🇿 Čeština • 🇳🇱 Nederlands • 🇹🇷 Türkçe • 🇺🇦 Українська • 🇻🇳 Tiếng Việt • 🇵🇭 Tagalog • 🇮🇩 Indonesia • 🇹🇭 ไทย • 🇮🇳 हिन्दी • 🇧🇩 বাংলা • 🇵🇰 اردو • 🇷🇴 Română • 🇸🇪 Svenska • 🇮🇹 Italiano • 🇬🇷 Ελληνικά • 🇭🇺 Magyar • 🇫🇮 Suomi • 🇩🇰 Dansk • 🇳🇴 Norsk
Grok Mem is how Grok Bots remember. Sits next to Grok's own memory. Does not replace it.




|
|
Quick Start • How It Works • Search Tools • Documentation • Configuration • Troubleshooting • License
Grok Mem is how Grok Bots remember the work. Grok already remembers you. Grok Mem remembers what the bot did, what we decided, what to do next. Those notes come back in the next chat.
Quick Start
Install Grok Mem for Grok Bot. The package name is still claude-mem.
npx claude-mem install --ide grok-bot
Grok Bot has no host hooks, so we watch the chat log files. Default is CMEM Pro, the hosted memory. Local observer is opt-in: --provider host. Installing this plugin does not install Cursor.
Awareness push pilot (LFG + Orifice): needle observations (decision, bugfix, security_alert, sensitive) are appended as dated - YYYY-MM-DD [awareness] … lines into that bot's memory/log/YYYY-MM.md. Grok Bot already re-reads the log from disk. This does not write profile.md, user-memory, or project memory. Disable with CLAUDE_MEM_GROK_BOT_AWARENESS_ENABLED=false.
Install with a single command:
npx claude-mem install
The installer sets everything up first, then asks you to sign in to claude-mem in your browser (email magic link — no card required). Signing in provisions a memory key for your account and unlocks the claude-mem observer: memory that runs off-plan, free for your first 30 days, so you get up to 100% more usage from your plan. When the free trial ends, memory automatically falls back to your Anthropic plan unless you subscribe. After sign-in you pick your memory provider — the claude-mem observer, your own OpenRouter or Gemini key, or your Anthropic plan.
Prefer to skip the sign-in? Pass an explicit --provider flag, set CLAUDE_MEM_ONLINE_OPTIN=false, or run in CI/non-interactive shells — the installer completes without any account interaction.
Or install for OpenCode:
npx claude-mem install --ide opencode
Or install for Antigravity CLI (setup guide):
npx claude-mem install --ide antigravity
Or install from the plugin marketplace inside Claude Code:
/plugin marketplace add thedotmack/claude-mem

/plugin install claude-mem
Restart Claude Code. Context from previous sessions will automatically appear in new sessions.
Note: Claude-Mem is also published on npm, but
npm install -g claude-meminstalls the SDK/library only — it does not register the plugin hooks or set up the worker service. Always install vianpx claude-mem installor the/plugincommands above.
🦞 OpenClaw Gateway
Install claude-mem as a persistent memory plugin on OpenClaw gateways with a single command:
curl -fsSL https://install.cmem.ai/openclaw.sh | bash
The installer handles dependencies, plugin setup, AI provider configuration, worker startup, and optional real-time observation feeds to Telegram, Discord, Slack, and more. See the OpenClaw Integration Guide for details.
Key Features:
- 🧠 Persistent Memory - Context survives across sessions
- 📊 Progressive Disclosure - Layered memory retrieval with token cost visibility
- 🔍 Skill-Based Search - Query your project history with mem-search skill
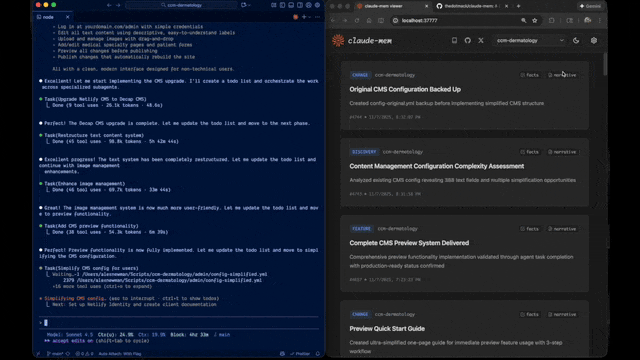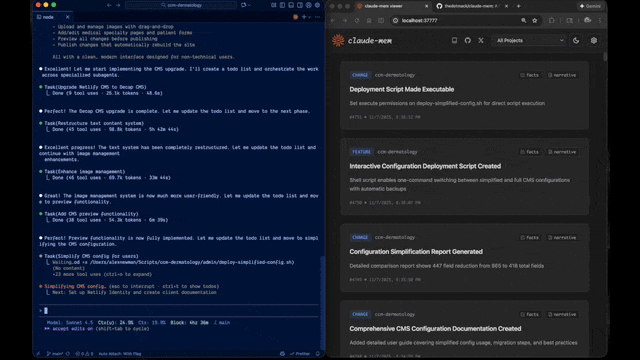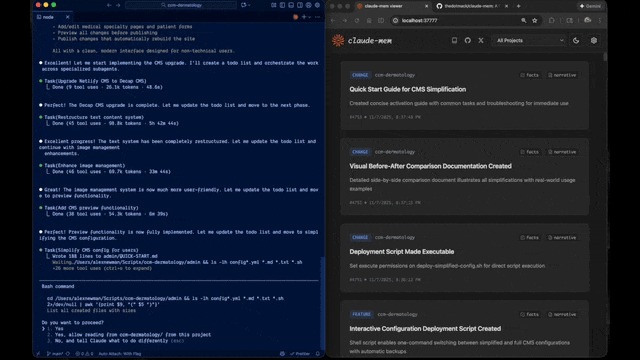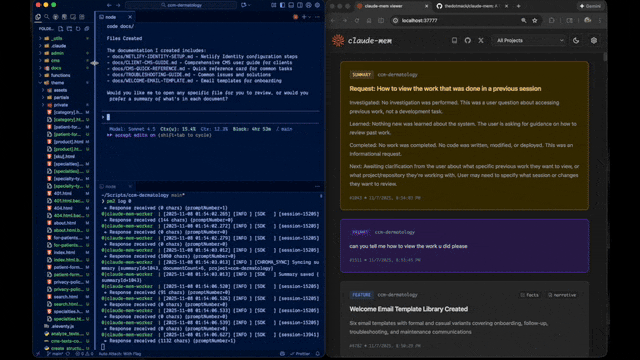
- 🖥️ Web Viewer UI - Real-time memory stream at the worker URL printed on startup
- 💻 Claude Desktop Skill - Search memory from Claude Desktop conversations
- 🔒 Privacy Control - Use
<private>tags to exclude sensitive content from storage - ⚙️ Context Configuration - Fine-grained control over what context gets injected
- 🤖 Automatic Operation - No manual intervention required
- 🔗 Citations - Reference past observations with IDs through the worker API or view all in the web viewer
Documentation
📚 View Full Documentation - Browse on official website
Getting Started
- Installation Guide - Quick start & advanced installation
- Usage Guide - How Claude-Mem works automatically
- Search Tools - Query your project history with natural language
- Cloud Sync - Back up your memories to cmem.ai — no daemon, the worker syncs on write
Best Practices
- Context Engineering - AI agent context optimization principles
- Progressive Disclosure - Philosophy behind Claude-Mem's context priming strategy
Architecture
- Overview - System components & data flow
- Architecture Evolution - The journey from v3 to v5
- Hooks Architecture - How Claude-Mem uses lifecycle hooks
- Hooks Reference - 7 hook scripts explained
- Worker Service - HTTP API & Bun management
- Database - SQLite schema & FTS5 search
- Search Architecture - Hybrid search with Chroma vector database
Configuration & Development
- Configuration - Environment variables & settings
- Development - Building, testing, contributing
- Release Branches - Stable, core-dev, and community-edge branch flow
- Troubleshooting - Common issues & solutions
How It Works
Core Components:
- 5 Lifecycle Hooks - SessionStart, UserPromptSubmit, PostToolUse, Stop, SessionEnd (6 hook scripts)
- Smart Install - Cached dependency checker (pre-hook script, not a lifecycle hook)
- Worker Service - Local HTTP API with web viewer UI and search endpoints, managed by Bun
- SQLite Database - Stores sessions, observations, summaries
- mem-search Skill - Natural language queries with progressive disclosure
- Chroma Vector Database - Hybrid semantic + keyword search for intelligent context retrieval
See Architecture Overview for details.
MCP Search Tools
Claude-Mem provides intelligent memory search through 4 MCP tools following a token-efficient 3-layer workflow pattern:
The 3-Layer Workflow:
search- Get compact index with IDs (~50-100 tokens/result)timeline- Get chronological context around interesting resultsget_observations- Fetch full details ONLY for filtered IDs (~500-1,000 tokens/result)
How It Works:
- Claude uses MCP tools to search your memory
- Start with
searchto get an index of results - Use
timelineto see what was happening around specific observations - Use
get_observationsto fetch full details for relevant IDs - ~10x token savings by filtering before fetching details
Available MCP Tools:
search- Search memory index with full-text queries, filters by type/date/projecttimeline- Get chronological context around a specific observation or queryget_observations- Fetch full observation details by IDs (always batch multiple IDs)
Example Usage:
// Step 1: Search for index
search(query="authentication bug", type="bugfix", limit=10)

// Step 2: Review index, identify relevant IDs (e.g., #123, #456)

// Step 3: Fetch full details
get_observations(ids=[123, 456])
See Search Tools Guide for detailed examples.
Release Branches
Stable releases ship from main and are published to npm. core-dev and
community-edge are source-run branches for early reliability fixes and
community integrations. See Release Branches
for the branch flow and non-stable run instructions.
System Requirements
- Node.js: 20.0.0 or higher
- Claude Code: Latest version with plugin support
- Bun: JavaScript runtime and process manager (auto-installed if missing)
- uv: Python package manager for vector search (auto-installed if missing)
- SQLite 3: For persistent storage (bundled)
Windows Setup Notes
If you see an error like:
npm : The term 'npm' is not recognized as the name of a cmdlet
Make sure Node.js and npm are installed and added to your PATH. Download the latest Node.js installer from https://nodejs.org and restart your terminal after installation.
Configuration
Settings are managed in ~/.claude-mem/settings.json (auto-created with defaults on first run). Configure AI model, worker port, data directory, log level, and context injection settings.
See the Configuration Guide for all available settings and examples.
Mode & Language Configuration
Claude-Mem supports multiple workflow modes and languages via the CLAUDE_MEM_MODE setting.
This option controls both:
- The workflow behavior (e.g. code, chill, investigation)
- The language used in generated observations
How to Configure
Edit your settings file at ~/.claude-mem/settings.json:
{
  "CLAUDE_MEM_MODE": "code--zh"
}
Modes are defined in plugin/modes/. To see all available modes locally:
ls ~/.claude/plugins/marketplaces/thedotmack/plugin/modes/
Available Modes
| Mode | Description |
|---|---|
code |
Default English mode |
code--zh |
Simplified Chinese mode |
code--ja |
Japanese mode |
Language-specific modes follow the pattern code--[lang] where [lang] is the ISO 639-1 language code (e.g., zh for Chinese, ja for Japanese, es for Spanish).
Note:
code--zh(Simplified Chinese) is already built-in — no additional installation or plugin update is required.
After Changing Mode
Restart Claude Code to apply the new mode configuration.
Development
See the Development Guide for build instructions, testing, and contribution workflow.
Troubleshooting
If experiencing issues, describe the problem to Claude and the troubleshoot skill will automatically diagnose and provide fixes.
See the Troubleshooting Guide for common issues and solutions.
Bug Reports
Create comprehensive bug reports with the automated generator:
cd ~/.claude/plugins/marketplaces/thedotmack
npm run bug-report
Contributing
Contributions are welcome! Please:
- Fork the repository
- Create a feature branch
- Make your changes with tests
- Update documentation
- Submit a Pull Request
Claude-Mem ships from three branches: main (stable), core-dev, and
community-edge. Only main is published to npm; the others are run from
source. See Release Branches for the
strategy and local run instructions.
See Development Guide for contribution workflow.
License
Claude-Mem is licensed under the Apache License 2.0.
We chose Apache-2.0 because durable agentic memory should be easy to embed in developer tools, local agents, MCP servers, enterprise systems, robotics stacks, and production agent harnesses.
See the LICENSE file for full details. See docs/license.md and docs/ip-boundary.md for licensing scope and the open/commercial boundary.
Note on Ragtime: The ragtime/ directory is licensed under the Apache License 2.0. See ragtime/LICENSE for details.
Support
- Documentation: docs/
- Issues: GitHub Issues
- Repository: github.com/thedotmack/claude-mem
- Official X Account: @Claude_Memory
- Official Discord: Join Discord
- Author: Alex Newman (@thedotmack)
Built with Claude Agent SDK | Works with Claude Code | Made with TypeScript
What About CMEM?
CMEM is a token created by a 3rd party but officially embraced by the creator of Claude-Mem (Alex Newman, @thedotmack). The token acts as a community catalyst for growth and a vehicle for bringing CMEM to the developers and knowledge workers that need it most.
Official BASE CA: 0x76b1967eec0ccaeb001bbbb2b40dc4badba31ba3