mirror of
https://github.com/giuseppe-trisciuoglio/developer-kit.git
synced 2026-09-14 18:22:07 +08:00
Merge pull request #194 from giuseppe-trisciuoglio/develop
Release v2.8.2
This commit is contained in:
 Giuseppe Trisciuoglio
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "developer-kit",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"description": "Modular marketplace for developer kit plugins",
|
||||
"owner": {
|
||||
"name": "Giuseppe Trisciuoglio",
|
||||
|
||||
@@ -29,233 +29,373 @@ Requires-Dist: mypy>=1.0; extra == "dev"
|
||||
Requires-Dist: types-PyYAML>=6.0; extra == "dev"
|
||||
Dynamic: license-file
|
||||
|
||||
# Developer Kit for Claude Code
|
||||
<div align="center">
|
||||
|
||||
> A modular plugin system of reusable skills, agents, and commands for automating development tasks in Claude Code
|
||||
[](./LICENSE)
|
||||
[](https://github.com/giuseppe-trisciuoglio/developer-kit/actions/workflows/security-scan.yml)
|
||||
[](https://github.com/giuseppe-trisciuoglio/developer-kit/actions/workflows/plugin-validation.yml)
|
||||
[](./plugins)
|
||||
[](./plugins)
|
||||
|
||||
**Developer Kit for Claude Code** teaches Claude how to **perform development tasks in a repeatable way** across
|
||||
multiple languages and frameworks. Built as a modular marketplace, you can install only the plugins you need.
|
||||
**🌐 Languages:** [English](README.md) | [Italiano](./README_IT.md) | [中文](./README_CN.md) | [Español](./README_ES.md)
|
||||
|
||||
## Quick Start
|
||||
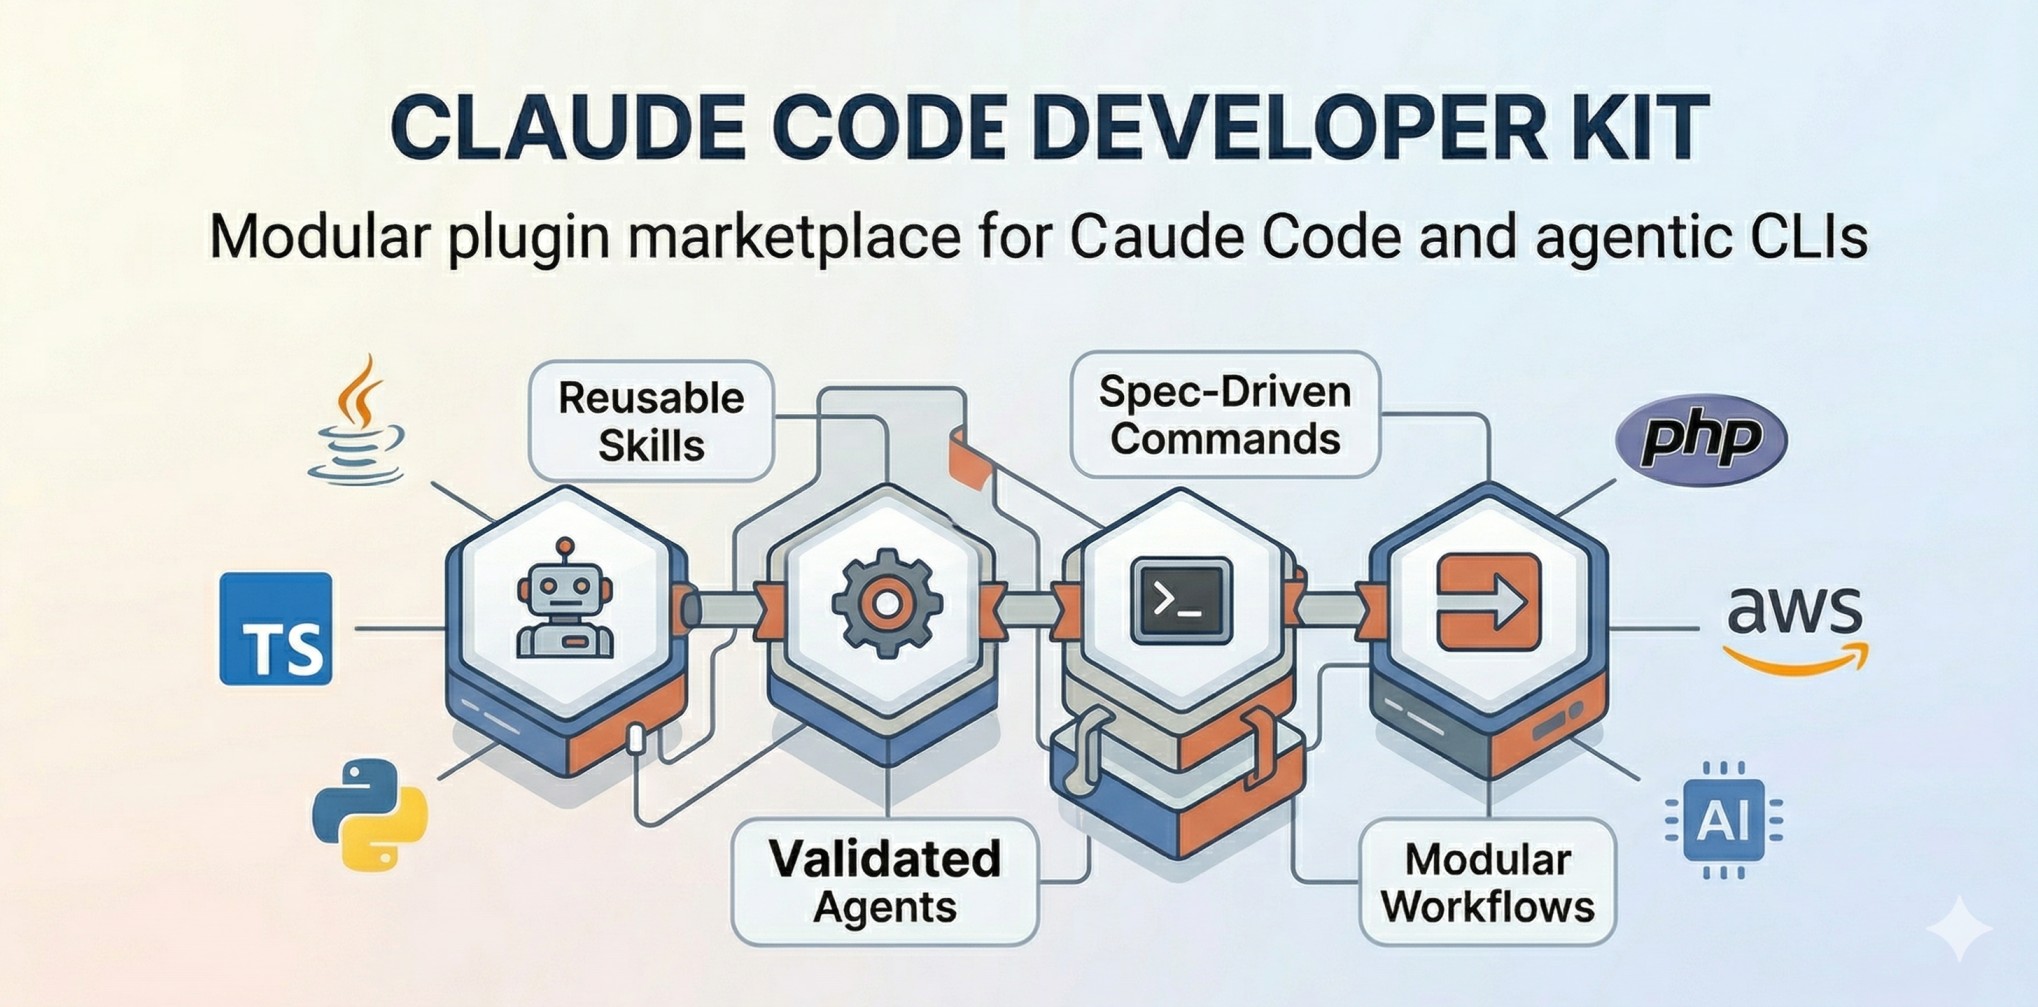
|
||||
|
||||
**A modular AI plugin system that supercharges your development workflow across languages and frameworks.**
|
||||
|
||||
[Installation](#installation) • [Quick Start](#quick-start) • [Plugins](#available-plugins) • [Documentation](https://github.com/giuseppe-trisciuoglio/developer-kit/blob/main/README.md) • [Changelog](./CHANGELOG.md)
|
||||
|
||||
</div>
|
||||
|
||||
---
|
||||
|
||||
## Why Developer Kit?
|
||||
|
||||
Developer Kit is a **modular plugin marketplace** for Claude Code that teaches Claude how to perform development tasks in a repeatable, high-quality way. Instead of generic AI responses, you get domain-specific expertise for your exact tech stack.
|
||||
|
||||
- **🧩 Modular by Design** — Install only what you need. Java developer? Grab `developer-kit-java`. Full-stack TypeScript? Add `developer-kit-typescript`.
|
||||
- **🎯 Domain Experts** — 45+ specialized agents for code review, refactoring, security audits, architecture design, and testing across 7+ languages.
|
||||
- **📚 150+ Skills** — Reusable capabilities from Spring Boot CRUD generation to CloudFormation templates, all with best practices built-in.
|
||||
- **🔄 Multi-CLI Support** — Works with Claude Code, GitHub Copilot CLI, OpenCode CLI, and Codex CLI.
|
||||
- **⚡ Auto-Activation** — Path-scoped rules automatically activate when you open relevant files. No configuration needed.
|
||||
|
||||
---
|
||||
|
||||
## Installation
|
||||
|
||||
### Quick Install (Recommended)
|
||||
|
||||
#### Claude Code
|
||||
|
||||
```bash
|
||||
# Install from marketplace (recommended)
|
||||
# Install from marketplace
|
||||
/plugin marketplace add giuseppe-trisciuoglio/developer-kit
|
||||
|
||||
# Or install from local directory
|
||||
/plugin install /path/to/developer-kit
|
||||
```
|
||||
|
||||
**Claude Desktop**: [Enable Skills in Settings](https://claude.ai/settings/capabilities)
|
||||
#### Claude Desktop
|
||||
|
||||
[Enable Skills in Settings](https://claude.ai/settings/capabilities) → Add `giuseppe-trisciuoglio/developer-kit`
|
||||
|
||||
#### Manual Installation
|
||||
|
||||
```bash
|
||||
# Clone the repository
|
||||
git clone https://github.com/giuseppe-trisciuoglio/developer-kit.git
|
||||
|
||||
# Install via Makefile (auto-detects your CLI)
|
||||
cd developer-kit
|
||||
make install
|
||||
|
||||
# Or install for specific CLI
|
||||
make install-claude # Claude Code
|
||||
make install-opencode # OpenCode CLI
|
||||
make install-copilot # GitHub Copilot CLI
|
||||
make install-codex # Codex CLI
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Architecture
|
||||
## Quick Start
|
||||
|
||||
Developer Kit is organized as a **modular marketplace** with 10 independent plugins:
|
||||
```bash
|
||||
# After installation, start your CLI
|
||||
claude
|
||||
|
||||
# Check available commands
|
||||
/help
|
||||
|
||||
# Use a Developer Kit command
|
||||
/devkit.refactor
|
||||
|
||||
# Or invoke a specs workflow
|
||||
/specs:brainstorm
|
||||
```
|
||||
|
||||
### Example Prompts
|
||||
|
||||
```
|
||||
plugins/
|
||||
├── developer-kit-core/ # Core agents/commands (required)
|
||||
├── developer-kit-java/ # Java/Spring Boot/LangChain4J/AWS SDK
|
||||
├── developer-kit-typescript/ # NestJS/React/React Native
|
||||
├── developer-kit-python/ # Python development
|
||||
├── developer-kit-php/ # PHP/WordPress
|
||||
├── developer-kit-aws/ # AWS CloudFormation
|
||||
├── developer-kit-ai/ # Prompt Engineering/RAG/Chunking
|
||||
├── developer-kit-devops/ # Docker/GitHub Actions
|
||||
├── developer-kit-project-management/ # LRA workflow/Meetings
|
||||
└── github-spec-kit/ # GitHub specification integration
|
||||
Generate a complete CRUD module for User entity with NestJS and Drizzle ORM
|
||||
Review this Java Spring Boot service for security issues
|
||||
Create a CloudFormation template for ECS with auto-scaling
|
||||
Help me refactor this monolithic class into clean architecture
|
||||
Generate unit tests for this TypeScript service with 100% coverage
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Usage
|
||||
|
||||
Developer Kit provides **four layers** of capabilities:
|
||||
|
||||
### 1. Skills
|
||||
Reusable capabilities loaded on-demand. Example:
|
||||
|
||||
```
|
||||
[Skill: spring-boot-crud-patterns activated]
|
||||
```
|
||||
|
||||
Skills automatically provide patterns, templates, and best practices for specific tasks.
|
||||
|
||||
### 2. Agents
|
||||
Specialized sub-agents for complex workflows:
|
||||
|
||||
```bash
|
||||
# Invoke via natural language
|
||||
"Review this code as a Spring Boot expert"
|
||||
|
||||
# Or use commands
|
||||
/devkit.java.code-review
|
||||
/devkit.typescript.code-review
|
||||
```
|
||||
|
||||
### 3. Specifications-Driven Development (SDD)
|
||||
Transform ideas into production-ready code through a structured workflow:
|
||||
|
||||

|
||||
|
||||
#### Phase 1: Specification Creation
|
||||
|
||||
| Command | When to Use | Output |
|
||||
|---------|-------------|--------|
|
||||
| `/specs:brainstorm` | New features, complex requirements | Full specification with 9 phases |
|
||||
| `/specs:quick-spec` | Bug fixes, small enhancements | Lightweight 4-phase spec |
|
||||
|
||||
The specification lives in `docs/specs/[id]/YYYY-MM-DD--feature-name.md`
|
||||
|
||||
#### Phase 2: Task Generation
|
||||
|
||||
| Command | Description |
|
||||
|---------|-------------|
|
||||
| `/specs:spec-to-tasks` | Convert specification into executable task files |
|
||||
| `/specs:task-manage` | Add, split, update, or reorganize tasks |
|
||||
|
||||
Tasks are generated in `docs/specs/[id]/tasks/` with individual task files.
|
||||
|
||||
#### Phase 3: Implementation
|
||||
|
||||
| Command | Description |
|
||||
|---------|-------------|
|
||||
| `/specs:task-implementation` | Guided implementation of a specific task |
|
||||
| `/specs:task-tdd` | Test-Driven Development approach for the task |
|
||||
|
||||
Each task implementation updates the Knowledge Graph for context preservation.
|
||||
|
||||
#### Phase 4: Quality Assurance
|
||||
|
||||
| Command | Description |
|
||||
|---------|-------------|
|
||||
| `/specs:task-review` | Verify task meets specifications and code quality standards |
|
||||
| `/specs:code-cleanup` | Professional cleanup: remove debug logs, optimize imports |
|
||||
| `/specs:spec-sync-with-code` | Synchronize spec with actual implementation |
|
||||
|
||||
#### Additional Workflow Commands
|
||||
|
||||
| Command | Description |
|
||||
|---------|-------------|
|
||||
| `/specs:spec-quality-check` | Interactive quality assessment of specifications |
|
||||
| `/specs:spec-sync-context` | Sync Knowledge Graph, Tasks, and Codebase state |
|
||||
| `/specs:ralph-loop` | Automated loop for spec-driven development |
|
||||
| `/devkit.refactor` | Refactor existing code with architectural analysis |
|
||||
| `/devkit.github.create-pr` | Create PR with comprehensive description |
|
||||
|
||||
### 4. Rules
|
||||
Path-scoped rules auto-activate based on file patterns:
|
||||
|
||||
```yaml
|
||||
# Auto-activates for *.java files
|
||||
globs: ["**/*.java"]
|
||||
---
|
||||
Always use constructor injection. Never use field injection with @Autowired.
|
||||
```
|
||||
|
||||
> **📋 Note on Rules Installation**
|
||||
>
|
||||
> Plugins do not automatically install rules into your project. To use the rules, you can copy them manually
|
||||
> or use the Makefile command:
|
||||
>
|
||||
> ```bash
|
||||
> # Copy rules from a specific plugin
|
||||
> make copy-rules PLUGIN=developer-kit-java
|
||||
>
|
||||
> # Or manually copy .md files from the plugin's rules/ folder
|
||||
> mkdir -p .claude/rules
|
||||
> cp plugins/developer-kit-[language]/rules/*.md .claude/rules/
|
||||
> ```
|
||||
>
|
||||
> The rules will be automatically activated based on the `globs:` patterns defined in the header of each file.
|
||||
|
||||
---
|
||||
|
||||
## Available Plugins
|
||||
|
||||
### developer-kit-core (Required)
|
||||
| Plugin | Language/Domain | Components | Description |
|
||||
|--------|-----------------|------------|-------------|
|
||||
| `developer-kit-core` | Core | 6 Agents, 8 Commands, 4 Skills | Required base plugin with general-purpose capabilities |
|
||||
| `developer-kit-specs` | Workflow | 9 Commands, 2 Skills | Specifications-driven development (SDD) workflow |
|
||||
| `developer-kit-java` | Java | 9 Agents, 11 Commands, 51 Skills, 4 Rules | Spring Boot, LangChain4J, AWS SDK, GraalVM |
|
||||
| `developer-kit-typescript` | TypeScript | 13 Agents, 3 Commands, 25 Skills, 17 Rules | NestJS, React, Next.js, Drizzle ORM, Monorepo |
|
||||
| `developer-kit-python` | Python | 4 Agents, 4 Rules | Django, Flask, FastAPI, AWS Lambda |
|
||||
| `developer-kit-php` | PHP | 5 Agents, 3 Skills, 4 Rules | WordPress, Sage, AWS Lambda |
|
||||
| `developer-kit-aws` | AWS | 3 Agents, 19 Skills | CloudFormation, SAM, CLI, Architecture |
|
||||
| `developer-kit-ai` | AI/ML | 1 Agent, 3 Skills, 1 Command | Prompt Engineering, RAG, Chunking |
|
||||
| `developer-kit-devops` | DevOps | 2 Agents | Docker, GitHub Actions |
|
||||
| `developer-kit-tools` | Tools | 4 Skills | NotebookLM, Copilot CLI, Gemini, Codex |
|
||||
| `github-spec-kit` | GitHub | 3 Commands | GitHub spec integration |
|
||||
|
||||
Core agents and commands used by all other plugins.
|
||||
|
||||
| Component | Description |
|
||||
|------------------------------|----------------------------------------|
|
||||
| `general-code-explorer` | Deep codebase exploration and analysis |
|
||||
| `general-code-reviewer` | Code quality and security review |
|
||||
| `general-refactor-expert` | Code refactoring specialist |
|
||||
| `general-software-architect` | Feature architecture design |
|
||||
| `general-debugger` | Root cause analysis and debugging |
|
||||
| `document-generator-expert` | Professional document generation |
|
||||
|
||||
**Commands**: `/devkit.brainstorm`, `/devkit.refactor`, `/devkit.feature-development`, `/devkit.fix-debugging`,
|
||||
`/devkit.generate-document`, `/devkit.generate-changelog`, `/devkit.github.create-pr`, `/devkit.github.review-pr`,
|
||||
`/devkit.lra.*`, `/devkit.verify-skill`, `/devkit.generate-security-assessment`
|
||||
**Total: 150+ Skills | 45+ Agents | 20+ Commands | 45+ Rules**
|
||||
|
||||
---
|
||||
|
||||
### developer-kit-java
|
||||
## Plugin Architecture
|
||||
|
||||
Comprehensive Java development toolkit with Spring Boot, testing, LangChain4J, and AWS SDK integration.
|
||||
```
|
||||
developer-kit/
|
||||
├── plugins/
|
||||
│ ├── developer-kit-core/ # Required base
|
||||
│ │ ├── agents/ # Agent definitions (.md)
|
||||
│ │ ├── commands/ # Slash commands (.md)
|
||||
│ │ ├── skills/ # Reusable skills (SKILL.md)
|
||||
│ │ ├── rules/ # Auto-activated rules
|
||||
│ │ └── .claude-plugin/
|
||||
│ │ └── plugin.json # Plugin manifest
|
||||
│ ├── developer-kit-java/ # Java ecosystem
|
||||
│ ├── developer-kit-typescript/ # TypeScript ecosystem
|
||||
│ └── ...
|
||||
├── .skills-validator-check/ # Validation system
|
||||
└── Makefile # Installation commands
|
||||
```
|
||||
|
||||
**Agents**: `spring-boot-backend-development-expert`, `spring-boot-code-review-expert`,
|
||||
`spring-boot-unit-testing-expert`, `java-refactor-expert`, `java-security-expert`, `java-software-architect-review`,
|
||||
`java-documentation-specialist`, `java-tutorial-engineer`, `langchain4j-ai-development-expert`
|
||||
|
||||
**Commands**: `/devkit.java.code-review`, `/devkit.java.generate-crud`, `/devkit.java.refactor-class`,
|
||||
`/devkit.java.architect-review`, `/devkit.java.dependency-audit`, `/devkit.java.generate-docs`,
|
||||
`/devkit.java.security-review`, `/devkit.java.upgrade-dependencies`, `/devkit.java.write-unit-tests`,
|
||||
`/devkit.java.write-integration-tests`
|
||||
|
||||
**Skills**:
|
||||
|
||||
- **Spring Boot**: actuator, cache, crud-patterns, dependency-injection, event-driven-patterns, openapi-documentation,
|
||||
rest-api-standards, saga-pattern, security-jwt, test-patterns, resilience4j
|
||||
- **Spring Data**: jpa, neo4j
|
||||
- **Spring AI**: mcp-server-patterns
|
||||
- **JUnit Testing**: application-events, bean-validation, boundary-conditions, caching, config-properties,
|
||||
controller-layer, exception-handler, json-serialization, mapper-converter, parameterized, scheduled-async,
|
||||
security-authorization, service-layer, utility-methods, wiremock-rest-api
|
||||
- **LangChain4J**: ai-services-patterns, mcp-server-patterns, rag-implementation-patterns, spring-boot-integration,
|
||||
testing-strategies, tool-function-calling-patterns, vector-stores-configuration, qdrant
|
||||
- **AWS SDK**: rds-spring-boot-integration, bedrock, core, dynamodb, kms, lambda, messaging, rds, s3, secrets-manager
|
||||
Each plugin is self-contained with its own manifest, components, and dependencies.
|
||||
|
||||
---
|
||||
|
||||
### developer-kit-typescript
|
||||
## Configuration
|
||||
|
||||
TypeScript/JavaScript full-stack development with NestJS, React, and React Native.
|
||||
### Plugin Selection
|
||||
|
||||
**Agents**: `nestjs-backend-development-expert`, `nestjs-code-review-expert`, `nestjs-database-expert`,
|
||||
`nestjs-security-expert`, `nestjs-testing-expert`, `nestjs-unit-testing-expert`, `react-frontend-development-expert`,
|
||||
`react-software-architect-review`, `typescript-refactor-expert`, `typescript-security-expert`,
|
||||
`typescript-software-architect-review`, `typescript-documentation-expert`, `expo-react-native-development-expert`
|
||||
Install only the plugins you need:
|
||||
|
||||
**Commands**: `/devkit.typescript.code-review`, `/devkit.react.code-review`, `/devkit.ts.security-review`
|
||||
```bash
|
||||
# Core + Java + AWS
|
||||
make install-claude
|
||||
# Then enable: developer-kit-core, developer-kit-java, developer-kit-aws
|
||||
|
||||
**Skills**: `nestjs`, `react-patterns`, `shadcn-ui`, `tailwind-css-patterns`, `typescript-docs`
|
||||
# Full-stack TypeScript
|
||||
# Enable: developer-kit-core, developer-kit-typescript, developer-kit-aws
|
||||
```
|
||||
|
||||
### Rules Auto-Activation
|
||||
|
||||
Rules automatically activate based on file patterns:
|
||||
|
||||
```yaml
|
||||
---
|
||||
globs: ["**/*.java"]
|
||||
---
|
||||
# This rule activates for all Java files
|
||||
- Use constructor injection
|
||||
- Follow naming conventions
|
||||
```
|
||||
|
||||
### LSP Integration
|
||||
|
||||
Language plugins include LSP server configurations (`.lsp.json`):
|
||||
|
||||
| Language | Server |
|
||||
|----------|--------|
|
||||
| Java | jdtls |
|
||||
| TypeScript | typescript-language-server |
|
||||
| Python | pyright-langserver |
|
||||
| PHP | intelephense |
|
||||
|
||||
---
|
||||
|
||||
### developer-kit-python
|
||||
## Language Support Matrix
|
||||
|
||||
Python development capabilities for Django, Flask, and FastAPI projects.
|
||||
|
||||
**Agents**: `python-code-review-expert`, `python-refactor-expert`, `python-security-expert`,
|
||||
`python-software-architect-expert`
|
||||
| Language | Skills | Agents | Commands | Rules | LSP |
|
||||
|----------|--------|--------|----------|-------|-----|
|
||||
| Java/Spring Boot | 51 | 9 | 11 | 4 | ✅ |
|
||||
| TypeScript/Node.js | 25 | 13 | 3 | 17 | ✅ |
|
||||
| Python | 2 | 4 | 0 | 4 | ✅ |
|
||||
| PHP/WordPress | 3 | 5 | 0 | 4 | ✅ |
|
||||
| AWS/CloudFormation | 19 | 3 | 0 | 0 | ❌ |
|
||||
| AI/ML | 3 | 1 | 1 | 0 | ❌ |
|
||||
|
||||
---
|
||||
|
||||
### developer-kit-php
|
||||
## Validation & Quality
|
||||
|
||||
PHP and WordPress development capabilities.
|
||||
Developer Kit includes a comprehensive validation system:
|
||||
|
||||
**Agents**: `php-code-review-expert`, `php-refactor-expert`, `php-security-expert`, `php-software-architect-expert`,
|
||||
`wordpress-development-expert`
|
||||
```bash
|
||||
# Validate all components
|
||||
python .skills-validator-check/validators/cli.py --all
|
||||
|
||||
**Skills**: `wordpress-sage-theme` (Sage theme development)
|
||||
# Security scan (MCP compliance)
|
||||
make security-scan
|
||||
|
||||
# Pre-commit hooks
|
||||
.skills-validator-check/install-hooks.sh
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
### developer-kit-aws
|
||||
## Ecosystem
|
||||
|
||||
AWS infrastructure and CloudFormation expertise for Infrastructure as Code.
|
||||
**Listed on:**
|
||||
- [context7](https://context7.com/giuseppe-trisciuoglio/developer-kit?tab=skills) — Skills marketplace
|
||||
- [skills.sh](https://skills.sh/giuseppe-trisciuoglio/developer-kit) — AI skills directory
|
||||
|
||||
**Agents**: `aws-solution-architect-expert`, `aws-cloudformation-devops-expert`, `aws-architecture-review-expert`
|
||||
|
||||
**Skills** (15 total): `vpc`, `ec2`, `lambda`, `iam`, `s3`, `rds`, `dynamodb`, `ecs`, `auto-scaling`, `cloudwatch`,
|
||||
`cloudfront`, `security`, `elasticache`, `bedrock`, `task-ecs-deploy-gh`
|
||||
|
||||
---
|
||||
|
||||
### developer-kit-ai
|
||||
|
||||
AI/ML capabilities including prompt engineering, RAG, and chunking strategies.
|
||||
|
||||
**Agents**: `prompt-engineering-expert`
|
||||
|
||||
**Commands**: `/devkit.prompt-optimize`
|
||||
|
||||
**Skills**: `prompt-engineering`, `chunking-strategy`, `rag`
|
||||
|
||||
---
|
||||
|
||||
### developer-kit-devops
|
||||
|
||||
DevOps and containerization expertise.
|
||||
|
||||
**Agents**: `github-actions-pipeline-expert`, `general-docker-expert`
|
||||
|
||||
---
|
||||
|
||||
### developer-kit-project-management
|
||||
|
||||
Project management and workflow commands.
|
||||
|
||||
**Commands**: `/devkit.write-a-minute-of-a-meeting`
|
||||
|
||||
---
|
||||
|
||||
### github-spec-kit
|
||||
|
||||
GitHub specification integration and verification.
|
||||
|
||||
**Commands**: `/speckit.check-integration`, `/speckit.optimize`, `/speckit.verify`
|
||||
|
||||
---
|
||||
|
||||
## Key Features
|
||||
|
||||
- **Modular** — Install only the plugins you need for your tech stack
|
||||
- **Specialized** — Domain-specific agents for code review, testing, AI development, and full-stack development
|
||||
- **Composable** — Skills stack together automatically based on task context
|
||||
- **Portable** — Use across Claude.ai, Claude Code CLI, Claude Desktop, and Claude API
|
||||
- **Efficient** — Skills load on-demand, consuming minimal tokens until actively used
|
||||
|
||||
---
|
||||
|
||||
## Language Support
|
||||
|
||||
| Language | Plugin | Components |
|
||||
|--------------------|----------------------------|--------------------------|
|
||||
| Java/Spring Boot | `developer-kit-java` | Skills, Agents, Commands |
|
||||
| TypeScript/Node.js | `developer-kit-typescript` | Skills, Agents, Commands |
|
||||
| Python | `developer-kit-python` | Agents |
|
||||
| PHP/WordPress | `developer-kit-php` | Skills, Agents |
|
||||
| AWS CloudFormation | `developer-kit-aws` | Skills, Agents |
|
||||
| AI/ML | `developer-kit-ai` | Skills, Agents, Commands |
|
||||
**Related Projects:**
|
||||
- [Claude Code](https://claude.ai/code) — AI-powered terminal from Anthropic
|
||||
- [OpenCode](https://github.com/opencode-ai/opencode) — Open-source AI coding assistant
|
||||
- [GitHub Copilot CLI](https://github.com/github/copilot.vim) — AI pair programming
|
||||
- [Codex CLI](https://github.com/openai/codex) — OpenAI's coding agent
|
||||
|
||||
---
|
||||
|
||||
## Contributing
|
||||
|
||||
See [CONTRIBUTING.md](CONTRIBUTING.md) for detailed instructions on adding skills, agents, and commands.
|
||||
|
||||
---
|
||||
We welcome contributions! See [CONTRIBUTING.md](./CONTRIBUTING.md) for:
|
||||
- Adding new skills, agents, and commands
|
||||
- Plugin development guidelines
|
||||
- Validation requirements
|
||||
- Branch strategy and versioning
|
||||
|
||||
## Security
|
||||
|
||||
Skills can execute code. Review all custom skills before deploying.
|
||||
Skills can execute code. Review all custom skills before deploying:
|
||||
|
||||
- Only install from trusted sources
|
||||
- Review SKILL.md before enabling
|
||||
- Test in non-production environments first
|
||||
- ✅ Only install from trusted sources
|
||||
- ✅ Review SKILL.md before enabling
|
||||
- ✅ Test in non-production environments first
|
||||
- ✅ Run `make security-scan` before releases
|
||||
|
||||
Security scans run automatically via GitHub Actions on every PR.
|
||||
|
||||
---
|
||||
|
||||
## License
|
||||
|
||||
See [LICENSE](LICENSE) file.
|
||||
[MIT License](./LICENSE) — Open source and free to use.
|
||||
|
||||
---
|
||||
|
||||
## Support
|
||||
## Acknowledgments
|
||||
|
||||
- **Questions?** [Open an issue](https://github.com/giuseppe-trisciuoglio/developer-kit/issues)
|
||||
- **Contributions?** [Submit a PR](https://github.com/giuseppe-trisciuoglio/developer-kit/pulls)
|
||||
|
||||
## Changelog
|
||||
|
||||
See [CHANGELOG.md](CHANGELOG.md) for complete history.
|
||||
- **Claude Code** by Anthropic — The foundation this plugin system extends
|
||||
- **Qwen Code** — README design inspiration
|
||||
- **Contributors** — Thank you to everyone who has contributed skills and plugins
|
||||
|
||||
---
|
||||
|
||||
**Made with care for Developers using Claude Code**
|
||||
**Also works with OpenCode, Github Copilot CLI and Codex**
|
||||
<div align="center">
|
||||
|
||||
**Made with ❤️ for Developers using Claude Code**
|
||||
|
||||
Also compatible with OpenCode, GitHub Copilot CLI, and Codex
|
||||
|
||||
</div>
|
||||
|
||||
@@ -10,6 +10,8 @@ pyproject.toml
|
||||
.skills-validator-check/validators/__init__.py
|
||||
.skills-validator-check/validators/cli.py
|
||||
.skills-validator-check/validators/config.py
|
||||
.skills-validator-check/validators/mcp_scan_checker.py
|
||||
.skills-validator-check/validators/models.py
|
||||
.skills-validator-check/validators/reporter.py
|
||||
.skills-validator-check/validators/security_checker.py
|
||||
.skills-validator-check/validators/validators.py
|
||||
+46
-2
@@ -21,6 +21,49 @@ and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0
|
||||
|
||||
### Security
|
||||
|
||||
## [2.8.2] - 2026-05-04
|
||||
|
||||
### Added
|
||||
|
||||
- **New `bug-fix-brief` skill** (`developer-kit-core`):
|
||||
- Structured bug documentation for systematic bug analysis
|
||||
- Follows spec-driven development workflow
|
||||
- Provides comprehensive bug reporting template
|
||||
|
||||
- **New `create-pr-from-spec` skill** (`developer-kit-specs`):
|
||||
- Creates GitHub Pull Request from specification documents
|
||||
- Integrates spec-to-code workflow with PR automation
|
||||
- Updates configuration for seamless integration
|
||||
|
||||
- **New Phase on Task Generation** (`developer-kit-specs`):
|
||||
- Added new phase for enhanced task generation workflow
|
||||
- Improved task complexity handling
|
||||
|
||||
- **New Hooks** (`developer-kit-specs`):
|
||||
- Added new hooks for spec workflow automation
|
||||
- Enhanced hook configuration
|
||||
|
||||
- **New `/specs:constitution` skill** (`developer-kit-specs`):
|
||||
- Setup project constitution for team guidelines
|
||||
- Project-level behavior enforcement
|
||||
|
||||
### Changed
|
||||
|
||||
- **Ralph Loop Skill Refactored** (`developer-kit-specs`):
|
||||
- Refactored to use same approach as Codex plugin
|
||||
- Improved multi-CLI agent integration
|
||||
|
||||
- **Documentation Updates** (global):
|
||||
- Added AGENTS.md for AI coding agent workflow
|
||||
- Updated AGENTS.md with behavioral guidelines
|
||||
- Moved agents.md into examples directory
|
||||
|
||||
### Fixed
|
||||
|
||||
- **Hook Configuration** (`developer-kit-core`):
|
||||
- Fixed edit config with hooks
|
||||
- Disabled Stop hooks to prevent workflow interruptions
|
||||
|
||||
## [2.8.1] - 2026-04-20
|
||||
|
||||
### Fixed
|
||||
@@ -1272,8 +1315,9 @@ and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0
|
||||
- Core functionality
|
||||
- Foundation documentation
|
||||
|
||||
[Unreleased]: https://github.com/giuseppe-trisciuoglio/developer-kit/compare/v2.8.0...HEAD
|
||||
[2.8.0]: https://github.com/giuseppe-trisciuoglio/developer-kit/compare/v2.7.2...v2.8.0
|
||||
[Unreleased]: https://github.com/giuseppe-trisciuoglio/developer-kit/compare/v2.8.2...HEAD
|
||||
[2.8.2]: https://github.com/giuseppe-trisciuoglio/developer-kit/compare/v2.8.1...v2.8.2
|
||||
[2.8.1]: https://github.com/giuseppe-trisciuoglio/developer-kit/compare/v2.8.0...v2.8.1
|
||||
[2.7.2]: https://github.com/giuseppe-trisciuoglio/developer-kit/compare/v2.7.1...v2.7.2
|
||||
[2.7.1]: https://github.com/giuseppe-trisciuoglio/developer-kit/compare/v2.6.3...v2.7.1
|
||||
[2.6.3]: https://github.com/giuseppe-trisciuoglio/developer-kit/compare/v2.6.2...v2.6.3
|
||||
|
||||
@@ -7,6 +7,7 @@
|
||||
# - OpenCode CLI (agents + commands + skills)
|
||||
# - Codex CLI (skills only, NO agents)
|
||||
# - Kimi CLI (skills only, NO agents)
|
||||
# - Kiro CLI (skills + agents as JSON + prompts)
|
||||
#
|
||||
# Usage:
|
||||
# make help Show all available targets
|
||||
@@ -22,7 +23,7 @@
|
||||
|
||||
SHELL := /bin/bash
|
||||
.PHONY: all help check-deps list-plugins list-components list-agents list-commands list-skills list-rules \
|
||||
install install-claude install-opencode install-copilot install-codex install-kimi \
|
||||
install install-claude install-opencode install-copilot install-codex install-kimi install-kiro \
|
||||
install-rules uninstall status backup clean security-scan security-scan-changed \
|
||||
skill-lint skill-security skill-review skill-review-all plugin-validate plugin-bump-version \
|
||||
install-agents-loop
|
||||
@@ -69,6 +70,11 @@ CODEX_AGENTS_MD := $(CODEX_CONFIG)/AGENTS.md
|
||||
KIMI_CONFIG := $(HOME)/.agents
|
||||
KIMI_SKILLS := $(KIMI_CONFIG)/skills
|
||||
|
||||
KIRO_CONFIG := $(HOME)/.kiro
|
||||
KIRO_SKILLS := $(KIRO_CONFIG)/skills
|
||||
KIRO_AGENTS := $(KIRO_CONFIG)/agents
|
||||
KIRO_PROMPTS := $(KIRO_CONFIG)/prompts
|
||||
|
||||
# ═══════════════════════════════════════════════════════════════
|
||||
# PLUGIN DISCOVERY
|
||||
# ═══════════════════════════════════════════════════════════════
|
||||
@@ -166,6 +172,7 @@ help:
|
||||
@echo " make install-copilot Install for GitHub Copilot CLI (global)"
|
||||
@echo " make install-codex Install for Codex CLI (global)"
|
||||
@echo " make install-kimi Install for Kimi CLI (global)"
|
||||
@echo " make install-kiro Install for Kiro CLI (global)"
|
||||
@echo " make install Install for all detected CLIs"
|
||||
@echo ""
|
||||
@echo -e "$(GREEN)Management:$(NC)"
|
||||
@@ -470,6 +477,31 @@ status:
|
||||
echo -e " ✗ $(RED)Not configured$(NC)"; \
|
||||
fi
|
||||
@echo ""
|
||||
@echo -e "$(GREEN)Kiro CLI:$(NC)"
|
||||
@if [ -d "$(KIRO_CONFIG)" ]; then \
|
||||
echo " ✓ Config directory exists: $(KIRO_CONFIG)"; \
|
||||
if [ -d "$(KIRO_SKILLS)" ] && ls "$(KIRO_SKILLS)" >/dev/null 2>&1; then \
|
||||
echo -e " ✓ $(GREEN)Developer Kit skills installed$(NC)"; \
|
||||
echo " Skills: $$(ls -1d "$(KIRO_SKILLS)"/* 2>/dev/null | wc -l | tr -d ' ')"; \
|
||||
else \
|
||||
echo " ○ Developer Kit skills not installed"; \
|
||||
fi; \
|
||||
if [ -d "$(KIRO_AGENTS)" ] && ls "$(KIRO_AGENTS)"/*.json >/dev/null 2>&1; then \
|
||||
echo -e " ✓ $(GREEN)Developer Kit agents installed$(NC)"; \
|
||||
echo " Agents: $$(ls -1 "$(KIRO_AGENTS)"/*.json 2>/dev/null | wc -l | tr -d ' ')"; \
|
||||
else \
|
||||
echo " ○ Developer Kit agents not installed"; \
|
||||
fi; \
|
||||
if [ -d "$(KIRO_PROMPTS)" ] && ls "$(KIRO_PROMPTS)"/*.md >/dev/null 2>&1; then \
|
||||
echo -e " ✓ $(GREEN)Developer Kit prompts installed$(NC)"; \
|
||||
echo " Prompts: $$(ls -1 "$(KIRO_PROMPTS)"/*.md 2>/dev/null | wc -l | tr -d ' ')"; \
|
||||
else \
|
||||
echo " ○ Developer Kit prompts not installed"; \
|
||||
fi; \
|
||||
else \
|
||||
echo -e " ✗ $(RED)Not configured$(NC)"; \
|
||||
fi
|
||||
@echo ""
|
||||
|
||||
# ═══════════════════════════════════════════════════════════════
|
||||
# BACKUP
|
||||
@@ -586,12 +618,19 @@ uninstall:
|
||||
if [ -d "$(KIMI_SKILLS)/$$cmd_skill" ]; then \
|
||||
rm -rf "$(KIMI_SKILLS)/$$cmd_skill"; \
|
||||
echo -e "$(GREEN)✓ Removed Kimi skill (converted from command): $$cmd_skill$(NC)"; \
|
||||
fi; \
|
||||
done; \
|
||||
fi
|
||||
fi; \
|
||||
done; \
|
||||
fi; \
|
||||
if [ -d "$(COPILOT_SKILLS)" ]; then \
|
||||
for cmd_skill in $$installed_commands_skills; do \
|
||||
if [ -d "$(COPILOT_SKILLS)/$$cmd_skill" ]; then \
|
||||
rm -rf "$(COPILOT_SKILLS)/$$cmd_skill"; \
|
||||
echo -e "$(GREEN)✓ Removed Copilot skill (converted from command): $$cmd_skill$(NC)"; \
|
||||
fi; \
|
||||
done; \
|
||||
fi
|
||||
@echo ""
|
||||
@echo -e "$(GREEN)✓ Uninstallation complete$(NC)"
|
||||
@echo -e "$(GREEN)✓ Uninstallation complete$(NC)"
|
||||
@echo ""
|
||||
|
||||
# ═══════════════════════════════════════════════════════════════
|
||||
@@ -606,6 +645,7 @@ install: backup
|
||||
@$(MAKE) -s install-copilot-if-exists
|
||||
@$(MAKE) -s install-codex-if-exists
|
||||
@$(MAKE) -s install-kimi-if-exists
|
||||
@$(MAKE) -s install-kiro-if-exists
|
||||
@echo ""
|
||||
@$(call success "Installation complete!")
|
||||
@$(MAKE) -s status
|
||||
@@ -638,6 +678,13 @@ install-kimi-if-exists:
|
||||
$(call warning "Skipping Kimi CLI (not configured)"); \
|
||||
fi
|
||||
|
||||
install-kiro-if-exists:
|
||||
@if [ -d "$(KIRO_CONFIG)" ]; then \
|
||||
$(MAKE) -s install-kiro; \
|
||||
else \
|
||||
$(call warning "Skipping Kiro CLI (not configured)"); \
|
||||
fi
|
||||
|
||||
# ═══════════════════════════════════════════════════════════════
|
||||
# SPECS UTILITIES INSTALLATION
|
||||
# ═══════════════════════════════════════════════════════════════
|
||||
@@ -794,10 +841,32 @@ install-copilot: check-deps
|
||||
done; \
|
||||
echo " Total skills installed: $$skills_count"
|
||||
@echo ""
|
||||
@echo -e "$(CYAN)Converting commands to skills...$(NC)"
|
||||
@commands_count=0; \
|
||||
for plugin_json in $(PLUGIN_JSON_FILES); do \
|
||||
plugin_dir=$$(dirname "$$plugin_json"); \
|
||||
base_dir=$$(dirname "$$plugin_dir"); \
|
||||
plugin_name=$$(jq -r '.name' "$$plugin_json" 2>/dev/null); \
|
||||
commands=$$(jq -r '.commands[]? // empty' "$$plugin_json" 2>/dev/null); \
|
||||
if [ -n "$$commands" ]; then \
|
||||
for cmd in $$commands; do \
|
||||
cmd_path="$$base_dir/$$cmd"; \
|
||||
if [ -f "$$cmd_path" ]; then \
|
||||
cmd_name=$$(basename "$$cmd" .md); \
|
||||
cmd_skill_dir="$(COPILOT_SKILLS)/$$cmd_name"; \
|
||||
mkdir -p "$$cmd_skill_dir"; \
|
||||
cp "$$cmd_path" "$$cmd_skill_dir/SKILL.md"; \
|
||||
echo " ✓ $$plugin_name: $$cmd_name (converted from command)"; \
|
||||
commands_count=$$((commands_count + 1)); \
|
||||
fi; \
|
||||
done; \
|
||||
fi; \
|
||||
done; \
|
||||
echo " Total commands converted to skills: $$commands_count"
|
||||
@echo ""
|
||||
@$(call success "Copilot CLI installation complete")
|
||||
@echo " Agents directory: $(COPILOT_AGENTS)/"
|
||||
@echo " Skills directory: $(COPILOT_SKILLS)/"
|
||||
@echo " NOTE: Commands are NOT installed for Copilot CLI (not supported)"
|
||||
@echo ""
|
||||
|
||||
# ═══════════════════════════════════════════════════════════════
|
||||
@@ -958,6 +1027,101 @@ install-kimi: check-deps
|
||||
@echo ""
|
||||
@echo ""
|
||||
|
||||
# ═══════════════════════════════════════════════════════════════
|
||||
# KIRO CLI INSTALLATION
|
||||
# ═══════════════════════════════════════════════════════════════
|
||||
|
||||
install-kiro: check-deps
|
||||
@echo ""
|
||||
@echo -e "$(BLUE)━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━$(NC)"
|
||||
@echo -e "$(BLUE)Installing Developer Kit for Kiro CLI$(NC)"
|
||||
@echo -e "$(BLUE)━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━$(NC)"
|
||||
@echo ""
|
||||
@mkdir -p $(KIRO_SKILLS) $(KIRO_AGENTS) $(KIRO_PROMPTS)
|
||||
@echo -e "$(CYAN)Installing skills...$(NC)"
|
||||
@skills_count=0; \
|
||||
for plugin_json in $(PLUGIN_JSON_FILES); do \
|
||||
plugin_dir=$$(dirname "$$plugin_json"); \
|
||||
base_dir=$$(dirname "$$plugin_dir"); \
|
||||
plugin_name=$$(jq -r '.name' "$$plugin_json" 2>/dev/null); \
|
||||
skills=$$(jq -r '.skills[]? // empty' "$$plugin_json" 2>/dev/null); \
|
||||
if [ -n "$$skills" ]; then \
|
||||
for skill_pattern in $$skills; do \
|
||||
for skill_dir in $$base_dir/$$skill_pattern; do \
|
||||
if [ -d "$$skill_dir" ]; then \
|
||||
skill_name=$$(basename "$$skill_dir"); \
|
||||
rm -rf "$(KIRO_SKILLS)/$$skill_name"; \
|
||||
cp -r "$$skill_dir" "$(KIRO_SKILLS)/$$skill_name"; \
|
||||
echo " ✓ $$plugin_name: $$skill_name"; \
|
||||
skills_count=$$((skills_count + 1)); \
|
||||
fi; \
|
||||
done; \
|
||||
done; \
|
||||
fi; \
|
||||
done; \
|
||||
echo " Total skills installed: $$skills_count"
|
||||
@echo ""
|
||||
@echo -e "$(CYAN)Installing agents as JSON...$(NC)"
|
||||
@agents_count=0; \
|
||||
for plugin_json in $(PLUGIN_JSON_FILES); do \
|
||||
plugin_dir=$$(dirname "$$plugin_json"); \
|
||||
base_dir=$$(dirname "$$plugin_dir"); \
|
||||
plugin_name=$$(jq -r '.name' "$$plugin_json" 2>/dev/null); \
|
||||
agents=$$(jq -r '.agents[]? // empty' "$$plugin_json" 2>/dev/null); \
|
||||
if [ -n "$$agents" ]; then \
|
||||
for agent in $$agents; do \
|
||||
agent_path="$$base_dir/$$agent"; \
|
||||
if [ -f "$$agent_path" ]; then \
|
||||
agent_name=$$(basename "$$agent" .md); \
|
||||
description=$$(grep -m1 '^description:' "$$agent_path" 2>/dev/null | sed 's/^description: *//'); \
|
||||
if [ -z "$$description" ]; then \
|
||||
description="$$agent_name agent from Developer Kit"; \
|
||||
fi; \
|
||||
prompt=$$(awk '/^---/{p++; next} p==1' "$$agent_path" 2>/dev/null | head -5 | tr '\n' ' ' | sed 's/ */ /g'); \
|
||||
if [ -z "$$prompt" ]; then \
|
||||
prompt="You are a helpful coding assistant specialized in $$agent_name tasks."; \
|
||||
fi; \
|
||||
jq -n \
|
||||
--arg name "$$agent_name" \
|
||||
--arg desc "$$description" \
|
||||
--arg prompt "$$prompt" \
|
||||
'{"name": $$name, "description": $$desc, "tools": ["read","write","edit","terminal"], "allowedTools": ["read","write","edit"], "resources": ["file://README.md","file://.kiro/steering/**/*.md","skill://.kiro/skills/**/SKILL.md"], "prompt": $$prompt, "model": "claude-sonnet-4"}' \
|
||||
> "$(KIRO_AGENTS)/$$agent_name.json"; \
|
||||
echo " ✓ $$plugin_name: $$agent_name.json"; \
|
||||
agents_count=$$((agents_count + 1)); \
|
||||
fi; \
|
||||
done; \
|
||||
fi; \
|
||||
done; \
|
||||
echo " Total agents installed: $$agents_count"
|
||||
@echo ""
|
||||
@echo -e "$(CYAN)Installing prompts (commands)...$(NC)"
|
||||
@prompts_count=0; \
|
||||
for plugin_json in $(PLUGIN_JSON_FILES); do \
|
||||
plugin_dir=$$(dirname "$$plugin_json"); \
|
||||
base_dir=$$(dirname "$$plugin_dir"); \
|
||||
plugin_name=$$(jq -r '.name' "$$plugin_json" 2>/dev/null); \
|
||||
commands=$$(jq -r '.commands[]? // empty' "$$plugin_json" 2>/dev/null); \
|
||||
if [ -n "$$commands" ]; then \
|
||||
for cmd in $$commands; do \
|
||||
cmd_path="$$base_dir/$$cmd"; \
|
||||
if [ -f "$$cmd_path" ]; then \
|
||||
cmd_name=$$(basename "$$cmd"); \
|
||||
cp "$$cmd_path" "$(KIRO_PROMPTS)/$$cmd_name"; \
|
||||
echo " ✓ $$plugin_name: $$cmd_name"; \
|
||||
prompts_count=$$((prompts_count + 1)); \
|
||||
fi; \
|
||||
done; \
|
||||
fi; \
|
||||
done; \
|
||||
echo " Total prompts installed: $$prompts_count"
|
||||
@echo ""
|
||||
@$(call success "Kiro CLI installation complete")
|
||||
@echo " Skills directory: $(KIRO_SKILLS)/"
|
||||
@echo " Agents directory: $(KIRO_AGENTS)/"
|
||||
@echo " Prompts directory: $(KIRO_PROMPTS)/"
|
||||
@echo ""
|
||||
|
||||
# ═══════════════════════════════════════════════════════════════
|
||||
# UTILITY INSTALLATION
|
||||
# ═══════════════════════════════════════════════════════════════
|
||||
|
||||
@@ -125,6 +125,15 @@ Transform ideas into production-ready code through a structured workflow:
|
||||
|
||||

|
||||
|
||||
#### Phase 0: Constitution (First-Time Setup)
|
||||
|
||||
| Command | When to Use | Output |
|
||||
|---------|-------------|--------|
|
||||
| `/developer-kit-specs:constitution create` | New project, before first spec | `docs/specs/constitution.md` |
|
||||
| `/developer-kit-specs:constitution check` | Validate spec/task against principles | Constitution Check Report |
|
||||
|
||||
The constitution defines the architectural DNA: approved stack, AI guardrails, security constraints (CWE mappings), and non-negotiable rules that govern all subsequent code generation.
|
||||
|
||||
#### Phase 1: Specification Creation
|
||||
|
||||
| Command | When to Use | Output |
|
||||
@@ -203,7 +212,7 @@ Always use constructor injection. Never use field injection with @Autowired.
|
||||
| Plugin | Language/Domain | Components | Description |
|
||||
|--------|-----------------|------------|-------------|
|
||||
| `developer-kit-core` | Core | 6 Agents, 8 Commands, 4 Skills | Required base plugin with general-purpose capabilities |
|
||||
| `developer-kit-specs` | Workflow | 9 Commands, 2 Skills | Specifications-driven development (SDD) workflow |
|
||||
| `developer-kit-specs` | Workflow | 9 Commands, 5 Skills | Specifications-driven development (SDD) workflow |
|
||||
| `developer-kit-java` | Java | 9 Agents, 11 Commands, 51 Skills, 4 Rules | Spring Boot, LangChain4J, AWS SDK, GraalVM |
|
||||
| `developer-kit-typescript` | TypeScript | 13 Agents, 3 Commands, 25 Skills, 17 Rules | NestJS, React, Next.js, Drizzle ORM, Monorepo |
|
||||
| `developer-kit-python` | Python | 4 Agents, 4 Rules | Django, Flask, FastAPI, AWS Lambda |
|
||||
|
||||
+10
-1
@@ -125,6 +125,15 @@ Developer Kit 提供**四层**能力:
|
||||
|
||||

|
||||
|
||||
#### 阶段 0:项目章程(首次设置)
|
||||
|
||||
| 命令 | 使用时机 | 输出 |
|
||||
|------|---------|------|
|
||||
| `/developer-kit-specs:constitution create` | 新项目,在第一个规范之前 | `docs/specs/constitution.md` |
|
||||
| `/developer-kit-specs:constitution check` | 根据原则验证规范/任务 | 章程检查报告 |
|
||||
|
||||
章程定义了架构 DNA:已批准的技术栈、AI 护栏、安全约束(CWE 映射)以及管理所有后续代码生成的不可协商规则。
|
||||
|
||||
#### 阶段 1:需求创建
|
||||
|
||||
| 命令 | 使用时机 | 输出 |
|
||||
@@ -203,7 +212,7 @@ globs: ["**/*.java"]
|
||||
| 插件 | 语言/领域 | 组件 | 描述 |
|
||||
|------|----------|------|------|
|
||||
| `developer-kit-core` | 核心 | 6 代理、8 命令、4 技能 | 包含通用能力的基础插件(必需) |
|
||||
| `developer-kit-specs` | 工作流 | 9 命令、2 技能 | 需求驱动开发(SDD)工作流 |
|
||||
| `developer-kit-specs` | 工作流 | 9 命令、5 技能 | 需求驱动开发(SDD)工作流 |
|
||||
| `developer-kit-java` | Java | 9 代理、11 命令、51 技能、4 规则 | Spring Boot、LangChain4J、AWS SDK、GraalVM |
|
||||
| `developer-kit-typescript` | TypeScript | 13 代理、3 命令、25 技能、17 规则 | NestJS、React、Next.js、Drizzle ORM、Monorepo |
|
||||
| `developer-kit-python` | Python | 4 代理、4 规则 | Django、Flask、FastAPI、AWS Lambda |
|
||||
|
||||
+10
-1
@@ -125,6 +125,15 @@ Transforma ideas en código listo para producción a través de un flujo de trab
|
||||
|
||||

|
||||
|
||||
#### Fase 0: Constitución (Configuración Inicial)
|
||||
|
||||
| Comando | Cuándo Usarlo | Salida |
|
||||
|---------|---------------|--------|
|
||||
| `/developer-kit-specs:constitution create` | Nuevo proyecto, antes de la primera spec | `docs/specs/constitution.md` |
|
||||
| `/developer-kit-specs:constitution check` | Validar spec/tarea contra los principios | Informe de Verificación Constitucional |
|
||||
|
||||
La constitución define el ADN arquitectónico: stack aprobado, guardrails de IA, restricciones de seguridad (mapeos CWE) y reglas no negociables que rigen toda la generación de código posterior.
|
||||
|
||||
#### Fase 1: Creación de Especificaciones
|
||||
|
||||
| Comando | Cuándo Usar | Salida |
|
||||
@@ -203,7 +212,7 @@ Usa siempre inyección por constructor. Nunca uses inyección de campo con @Auto
|
||||
| Plugin | Lenguaje/Dominio | Componentes | Descripción |
|
||||
|--------|------------------|-------------|-------------|
|
||||
| `developer-kit-core` | Core | 6 Agentes, 8 Comandos, 4 Habilidades | Plugin base requerido con capacidades de propósito general |
|
||||
| `developer-kit-specs` | Flujo de trabajo | 9 Comandos, 2 Habilidades | Flujo de trabajo de desarrollo guiado por especificaciones (SDD) |
|
||||
| `developer-kit-specs` | Flujo de trabajo | 9 Comandos, 5 Habilidades | Flujo de trabajo de desarrollo guiado por especificaciones (SDD) |
|
||||
| `developer-kit-java` | Java | 9 Agentes, 11 Comandos, 51 Habilidades, 4 Reglas | Spring Boot, LangChain4J, AWS SDK, GraalVM |
|
||||
| `developer-kit-typescript` | TypeScript | 13 Agentes, 3 Comandos, 25 Habilidades, 17 Reglas | NestJS, React, Next.js, Drizzle ORM, Monorepo |
|
||||
| `developer-kit-python` | Python | 4 Agentes, 4 Reglas | Django, Flask, FastAPI, AWS Lambda |
|
||||
|
||||
+10
-1
@@ -125,6 +125,15 @@ Trasforma le idee in codice production-ready attraverso un workflow strutturato:
|
||||
|
||||

|
||||
|
||||
#### Fase 0: Costituzione (Configurazione Iniziale)
|
||||
|
||||
| Comando | Quando Usarlo | Output |
|
||||
|---------|---------------|--------|
|
||||
| `/developer-kit-specs:constitution create` | Nuovo progetto, prima della prima spec | `docs/specs/constitution.md` |
|
||||
| `/developer-kit-specs:constitution check` | Valida spec/task rispetto ai principi | Report di Verifica Costituzionale |
|
||||
|
||||
La costituzione definisce il DNA architetturale: stack approvato, guardrail AI, vincoli di sicurezza (mappature CWE) e regole non negoziabili che governano tutta la generazione di codice successiva.
|
||||
|
||||
#### Fase 1: Creazione della Specifica
|
||||
|
||||
| Comando | Quando Usare | Output |
|
||||
@@ -203,7 +212,7 @@ Usa sempre l'iniezione tramite costruttore. Non usare mai l'iniezione su campo c
|
||||
| Plugin | Linguaggio/Dominio | Componenti | Descrizione |
|
||||
|--------|-------------------|------------|-------------|
|
||||
| `developer-kit-core` | Core | 6 Agent, 8 Comandi, 4 Skill | Plugin base richiesto con capacità generali |
|
||||
| `developer-kit-specs` | Workflow | 9 Comandi, 2 Skill | Workflow di sviluppo guidato dalle specifiche (SDD) |
|
||||
| `developer-kit-specs` | Workflow | 9 Comandi, 5 Skill | Workflow di sviluppo guidato dalle specifiche (SDD) |
|
||||
| `developer-kit-java` | Java | 9 Agent, 11 Comandi, 51 Skill, 4 Regole | Spring Boot, LangChain4J, AWS SDK, GraalVM |
|
||||
| `developer-kit-typescript` | TypeScript | 13 Agent, 3 Comandi, 25 Skill, 17 Regole | NestJS, React, Next.js, Drizzle ORM, Monorepo |
|
||||
| `developer-kit-python` | Python | 4 Agent, 4 Regole | Django, Flask, FastAPI, AWS Lambda |
|
||||
|
||||
@@ -0,0 +1,120 @@
|
||||
# AI Agent Workflow: Specification-Driven Development (SDD)
|
||||
|
||||
This document defines the mandatory workflow for AI coding agents interacting with this repository. To ensure high-quality, maintainable, and synchronized code, all agents **MUST** follow the Specification-Driven Development (SDD) process provided by the `developer-kit-specs` plugin.
|
||||
|
||||
## 1. Core Principles
|
||||
|
||||
- **Spec is Truth**: The functional specification in `docs/specs/` is the single source of truth for *WHAT* should be built.
|
||||
- **SDD Triangle**: Always keep **Specification**, **Tests**, and **Code** aligned. Every change must update all three.
|
||||
- **Atomic Tasks**: Implementation happens only through atomic tasks generated from a specification.
|
||||
- **Living Deliverables**: Specifications are not static; they must be updated when implementation reveals new constraints or refinements.
|
||||
|
||||
## 2. The SDD Lifecycle
|
||||
|
||||
AI Agents must follow these three phases in order:
|
||||
|
||||
### Phase 1: Specification & Planning
|
||||
Before writing any implementation code:
|
||||
1. **Brainstorm**: Use `/specs:brainstorm "idea"` (complex) or `/specs:quick-spec "idea"` (simple) to create a functional specification in `docs/specs/[ID]/`.
|
||||
2. **Quality Check**: Run `/specs:spec-quality-check docs/specs/[ID]/` to validate the requirements.
|
||||
3. **Generate Tasks**: Convert the spec into executable tasks using `/specs:spec-to-tasks --lang=[lang] docs/specs/[ID]/`.
|
||||
4. **Manage Scope**: If a task has complexity > 50, use `/specs:task-manage --action=split` to break it down.
|
||||
|
||||
### Phase 2: Implementation (Per-Task Loop)
|
||||
For **each** task in `pending` status, follow this strict sequence:
|
||||
1. **RED Phase (TDD)**: Run `/specs:task-tdd --task="..."` to generate failing tests first.
|
||||
2. **GREEN Phase**: Run `/specs:task-implementation --task="..."` to implement the logic and make tests pass.
|
||||
3. **Review**: Run `/specs:task-review --task="..."`. You **MUST** fix all findings until the review passes.
|
||||
4. **Cleanup**: Run `/specs:code-cleanup --task="..."` to perform final code hygiene (no logic changes allowed here).
|
||||
|
||||
### Phase 3: Finalization & Sync
|
||||
After completing one or more tasks:
|
||||
1. **Spec Sync**: Run `/specs:spec-sync-with-code docs/specs/[ID]/`. This detects drift and updates the functional spec with decisions made during coding.
|
||||
2. **Context Sync**: Run `/specs:spec-sync-context docs/specs/[ID]/` to update the Knowledge Graph and task metadata.
|
||||
|
||||
## 3. Automation with Ralph Loop
|
||||
|
||||
For long-running implementations or multiple tasks, use the **Ralph Loop** to manage context and state:
|
||||
1. **Initialize**: `python3 plugins/developer-kit-specs/skills/ralph-loop/scripts/ralph_loop.py --action=start --spec=docs/specs/[ID]/`
|
||||
2. **Iterate**: Run `python3 .../ralph_loop.py --action=loop --spec=...` to get the next command, execute it, and repeat.
|
||||
|
||||
## 4. Mandatory Commands Reference
|
||||
|
||||
| Command | When to use |
|
||||
|---------|-------------|
|
||||
| `/specs:brainstorm` | Starting a new complex feature. |
|
||||
| `/specs:quick-spec` | Bug fixes or small changes (<3 files). |
|
||||
| `/specs:spec-to-tasks` | Bridge from WHAT (spec) to HOW (code). |
|
||||
| `/specs:task-tdd` | Mandatory first step of implementation (RED). |
|
||||
| `/specs:task-implementation` | Implementing the solution (GREEN). |
|
||||
| `/specs:task-review` | Mandatory gate before cleanup. |
|
||||
| `/specs:spec-sync-with-code` | Closing the loop by updating the spec. |
|
||||
|
||||
## 5. Prohibited Actions
|
||||
|
||||
- **DO NOT** implement features without a corresponding task in `docs/specs/`.
|
||||
- **DO NOT** skip the `task-review` step.
|
||||
- **DO NOT** modify functional logic during the `code-cleanup` phase.
|
||||
- **DO NOT** leave the specification in a "drifted" state; always sync after implementation.
|
||||
|
||||
---
|
||||
*Follow this workflow to maintain the integrity of the Developer Kit ecosystem.*
|
||||
|
||||
## 6. Behavioral Guidelines for AI Agents
|
||||
|
||||
These guidelines are designed to reduce common LLM coding mistakes and bias towards caution over speed. For trivial tasks, use judgment.
|
||||
|
||||
### 6.1. Think Before Coding
|
||||
|
||||
**Don't assume. Don't hide confusion. Surface tradeoffs.**
|
||||
|
||||
Before implementing:
|
||||
- State your assumptions explicitly. If uncertain, ask.
|
||||
- If multiple interpretations exist, present them - don't pick silently.
|
||||
- If a simpler approach exists, say so. Push back when warranted.
|
||||
- If something is unclear, stop. Name what's confusing. Ask.
|
||||
|
||||
### 6.2. Simplicity First
|
||||
|
||||
**Minimum code that solves the problem. Nothing speculative.**
|
||||
|
||||
- No features beyond what was asked.
|
||||
- No abstractions for single-use code.
|
||||
- No "flexibility" or "configurability" that wasn't requested.
|
||||
- No error handling for impossible scenarios.
|
||||
- If you write 200 lines and it could be 50, rewrite it.
|
||||
- Ask yourself: "Would a senior engineer say this is overcomplicated?" If yes, simplify.
|
||||
|
||||
### 6.3. Surgical Changes
|
||||
|
||||
**Touch only what you must. Clean up only your own mess.**
|
||||
|
||||
When editing existing code:
|
||||
- Don't "improve" adjacent code, comments, or formatting.
|
||||
- Don't refactor things that aren't broken.
|
||||
- Match existing style, even if you'd do it differently.
|
||||
- If you notice unrelated dead code, mention it - don't delete it.
|
||||
|
||||
When your changes create orphans:
|
||||
- Remove imports/variables/functions that YOUR changes made unused.
|
||||
- Don't remove pre-existing dead code unless asked.
|
||||
|
||||
The test: Every changed line should trace directly to the user's request.
|
||||
|
||||
### 6.4. Goal-Driven Execution
|
||||
|
||||
**Define success criteria. Loop until verified.**
|
||||
|
||||
Transform tasks into verifiable goals:
|
||||
- "Add validation" → "Write tests for invalid inputs, then make them pass"
|
||||
- "Fix the bug" → "Write a test that reproduces it, then make it pass"
|
||||
- "Refactor X" → "Ensure tests pass before and after"
|
||||
|
||||
For multi-step tasks, state a brief plan:
|
||||
1. [Step] → verify: [check]
|
||||
2. [Step] → verify: [check]
|
||||
3. [Step] → verify: [check]
|
||||
|
||||
Strong success criteria let you loop independently. Weak criteria ("make it work") require constant clarification.
|
||||
|
||||
These guidelines are working if: fewer unnecessary changes in diffs, fewer rewrites due to overcomplication, and clarifying questions come before implementation rather than after mistakes.
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "developer-kit-ai",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"description": "AI/ML capabilities including prompt engineering, RAG, and chunking strategies",
|
||||
"author": {
|
||||
"name": "Giuseppe Trisciuoglio",
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "developer-kit-aws",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"description": "AWS infrastructure and CloudFormation expertise",
|
||||
"author": {
|
||||
"name": "Giuseppe Trisciuoglio",
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "developer-kit",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"description": "Core agents and commands required by all Developer Kit plugins",
|
||||
"author": {
|
||||
"name": "Giuseppe Trisciuoglio",
|
||||
@@ -51,6 +51,7 @@
|
||||
"./skills/docs-updater",
|
||||
"./skills/drawio-logical-diagrams",
|
||||
"./skills/github-issue-workflow",
|
||||
"./skills/learn"
|
||||
"./skills/learn",
|
||||
"./skills/bug-fix-brief"
|
||||
]
|
||||
}
|
||||
|
||||
+95
@@ -0,0 +1,95 @@
|
||||
#!/usr/bin/env python3
|
||||
"""Auto-Learn Stop Hook for Claude Code.
|
||||
|
||||
Triggers the learn skill to analyze the codebase and extract project rules
|
||||
when a session is terminated, enabling autonomous learning from development
|
||||
sessions.
|
||||
|
||||
Hook event: Stop
|
||||
Input: JSON via stdin (ignored — no tool-specific input for Stop events)
|
||||
Output: JSON to stdout with decision (approve/block)
|
||||
|
||||
Flow:
|
||||
1. First stop attempt → block and instruct Claude to run the learn skill
|
||||
2. Second stop attempt → marker exists, approve stop and clean up
|
||||
|
||||
Zero external dependencies — pure Python 3 standard library only.
|
||||
"""
|
||||
|
||||
import hashlib
|
||||
import json
|
||||
import os
|
||||
import sys
|
||||
import tempfile
|
||||
|
||||
# ─── Configuration ─────────────────────────────────────────────────────────────
|
||||
|
||||
MARKER_DIR = os.path.join(tempfile.gettempdir(), "claude-auto-learn")
|
||||
|
||||
LEARN_SYSTEM_MESSAGE = """\
|
||||
Before ending this session, run the **learn** skill to extract project patterns \
|
||||
discovered during this session.
|
||||
|
||||
Execute the full learn workflow:
|
||||
1. Assess project context and existing rules
|
||||
2. Delegate deep analysis to the learn-analyst sub-agent
|
||||
3. Filter and rank findings (discard duplicates and low-impact patterns)
|
||||
4. Present top findings to the user for approval
|
||||
5. Save approved rules to .claude/rules/
|
||||
|
||||
If no new patterns are found or the user declines, you may proceed to stop.\
|
||||
"""
|
||||
|
||||
|
||||
# ─── Helpers ───────────────────────────────────────────────────────────────────
|
||||
|
||||
|
||||
def _get_marker_path() -> str:
|
||||
"""Generate a marker file path unique to the current working directory.
|
||||
|
||||
Uses an MD5 hash of the CWD so that concurrent sessions in different
|
||||
projects do not interfere with each other.
|
||||
"""
|
||||
cwd = os.getcwd()
|
||||
cwd_hash = hashlib.md5(cwd.encode()).hexdigest()[:12]
|
||||
return os.path.join(MARKER_DIR, f"learn-triggered-{cwd_hash}")
|
||||
|
||||
|
||||
# ─── Main ──────────────────────────────────────────────────────────────────────
|
||||
|
||||
|
||||
def main() -> None:
|
||||
# Consume stdin to prevent broken-pipe errors (Stop hooks may send data).
|
||||
try:
|
||||
sys.stdin.read()
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
marker = _get_marker_path()
|
||||
|
||||
if os.path.exists(marker):
|
||||
# Learn was already triggered in this stop cycle — allow stop.
|
||||
try:
|
||||
os.remove(marker)
|
||||
except OSError:
|
||||
pass
|
||||
json.dump({"decision": "approve"}, sys.stdout)
|
||||
return
|
||||
|
||||
# First stop attempt — create marker and block to trigger learn.
|
||||
os.makedirs(MARKER_DIR, exist_ok=True)
|
||||
with open(marker, "w") as f:
|
||||
f.write("1")
|
||||
|
||||
json.dump(
|
||||
{
|
||||
"decision": "block",
|
||||
"reason": "Auto-learn: extracting project patterns before session end",
|
||||
"systemMessage": LEARN_SYSTEM_MESSAGE,
|
||||
},
|
||||
sys.stdout,
|
||||
)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -1,5 +1,5 @@
|
||||
{
|
||||
"description": "Prevent execution of destructive Bash commands that target paths outside the working directory or match security blacklists",
|
||||
"description": "Core hooks: prevent destructive commands",
|
||||
"hooks": {
|
||||
"PreToolUse": [
|
||||
{
|
||||
@@ -12,6 +12,7 @@
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
],
|
||||
"Stop": []
|
||||
}
|
||||
}
|
||||
|
||||
@@ -0,0 +1,157 @@
|
||||
---
|
||||
name: bug-fix-brief
|
||||
description: Generates a structured Bug Fix Brief (BFB) to document issue corrections. Includes root cause analysis, repro steps, fix options, and fix checklist. Use when user asks to create a BFB, document a bug fix, or generate a bug correction document.
|
||||
allowed-tools: Read, Write, AskUserQuestion, Glob
|
||||
---
|
||||
|
||||
# Bug Fix Brief (BFB)
|
||||
|
||||
## Overview
|
||||
|
||||
This skill generates a Bug Fix Brief (BFB): a structured document in `docs/bfb/` that uniformly captures every bug fix with root cause, repro steps, fix options, and checklist.
|
||||
|
||||
## When to Use
|
||||
|
||||
- User asks to create a BFB
|
||||
- User wants to document a bug fix in a structured way
|
||||
- After identifying the root cause of a bug and before implementing the fix
|
||||
|
||||
**Trigger:** "create BFB", "document bug", "bug fix brief", "document fix"
|
||||
|
||||
## Instructions
|
||||
|
||||
### Phase 1: Gather Information
|
||||
|
||||
Check existing numbering:
|
||||
```bash
|
||||
ls docs/bfb/ 2>/dev/null || echo "Directory does not exist"
|
||||
```
|
||||
|
||||
Ask the user for:
|
||||
- BFB number (or propose next sequential)
|
||||
- Concise title (3-5 words, kebab-case)
|
||||
- Issue link (e.g. #1287)
|
||||
- Environment (Prod/Stg/Dev) + version
|
||||
- Observed vs expected behavior
|
||||
- File/function/line of the cause
|
||||
|
||||
### Phase 2: Generate Template
|
||||
|
||||
Complete the full BFB template:
|
||||
|
||||
```markdown
|
||||
## BFB-XXX: [Title]
|
||||
|
||||
**Reference:** [Issue link]
|
||||
**Environment:** [Env] `vX.Y.Z`
|
||||
**Date:** YYYY-MM-DD
|
||||
|
||||
---
|
||||
|
||||
### 1. Bug
|
||||
- **Observed:** [wrong behavior]
|
||||
- **Expected:** [correct behavior]
|
||||
|
||||
### 2. Repro
|
||||
```
|
||||
1. ...
|
||||
2. ...
|
||||
→ [error/output]
|
||||
```
|
||||
|
||||
### 3. Cause
|
||||
`path/file.ext` — `function()` @ line N
|
||||
[Why it happens, max 3 lines]
|
||||
|
||||
### 4. Decision
|
||||
| Option | Fix | Choice |
|
||||
|--------|-----|--------|
|
||||
| A | [desc] | ✅/❌ |
|
||||
| B | [desc] | ✅/❌ |
|
||||
|
||||
**Rationale:** [why]
|
||||
|
||||
### 5. Fix
|
||||
- [ ] [change 1]
|
||||
- [ ] [test]
|
||||
- [ ] [verify repro]
|
||||
|
||||
### 6. Notes
|
||||
[recurring patterns, links, warnings]
|
||||
```
|
||||
|
||||
### Phase 3: Ask Confirmation
|
||||
|
||||
Show the generated BFB and ask with AskUserQuestion:
|
||||
- "Create the BFB"
|
||||
- "Edit before creating"
|
||||
- "Cancel"
|
||||
|
||||
### Phase 4: Write to Disk
|
||||
|
||||
Only after approval:
|
||||
```bash
|
||||
mkdir -p docs/bfb
|
||||
```
|
||||
|
||||
Write to `docs/bfb/BFB-XXX-title.md`
|
||||
|
||||
## Examples
|
||||
|
||||
**Input:** "create BFB for login email null crash"
|
||||
|
||||
**Final output:**
|
||||
```markdown
|
||||
## BFB-042: Login crash with null email
|
||||
|
||||
**Reference:** #1287
|
||||
**Environment:** Prod `v2.4.1`
|
||||
**Date:** 2026-05-02
|
||||
|
||||
---
|
||||
|
||||
### 1. Bug
|
||||
- **Observed:** App crashes if email field is empty
|
||||
- **Expected:** Error message "Email required"
|
||||
|
||||
### 2. Repro
|
||||
```
|
||||
1. Open login screen
|
||||
2. Tap "Login" without entering email
|
||||
→ NullPointerException @ AuthManager.kt:34
|
||||
```
|
||||
|
||||
### 3. Cause
|
||||
`AuthManager.kt` — `validateEmail()` @ line 34
|
||||
Missing null check on email.trim()
|
||||
|
||||
### 4. Decision
|
||||
| Option | Fix | Choice |
|
||||
|--------|-----|--------|
|
||||
| A | Add safe call `?.` | ✅ |
|
||||
| B | Refactor with Result type | ❌ |
|
||||
|
||||
**Rationale:** Option A is minimal, zero impact.
|
||||
|
||||
### 5. Fix
|
||||
- [ ] Add `email?.trim()?.isNotEmpty() == true`
|
||||
- [ ] Test `validateEmail_null_returnsFalse()`
|
||||
- [ ] Verify repro
|
||||
|
||||
### 6. Notes
|
||||
- Check other forms for missing null checks
|
||||
```
|
||||
|
||||
## Best Practices
|
||||
|
||||
1. **Sequential numbering**: BFB-001, BFB-002, no gaps
|
||||
2. **Concise title**: 3-5 words, kebab-case in filename
|
||||
3. **Root cause**: exact file, function, line
|
||||
4. **2+ fix options**: with pros/cons and rationale
|
||||
5. **Verifiable checklist**: each item must be testable
|
||||
|
||||
## Constraints and Warnings
|
||||
|
||||
- **Confirmation required**: Always ask before writing
|
||||
- **Max 3 lines for cause**: Stay concise
|
||||
- **Directory `docs/bfb/`**: Create if it does not exist
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "developer-kit-devops",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"description": "DevOps and containerization expertise",
|
||||
"author": {
|
||||
"name": "Giuseppe Trisciuoglio",
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "developer-kit-java",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"description": "Comprehensive Java development toolkit with Spring Boot, testing, LangChain4J, and AWS integration",
|
||||
"author": {
|
||||
"name": "Giuseppe Trisciuoglio",
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "developer-kit-php",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"description": "PHP and WordPress development capabilities",
|
||||
"author": {
|
||||
"name": "Giuseppe Trisciuoglio",
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "developer-kit-project-management",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"description": "Project management and workflow commands",
|
||||
"author": {
|
||||
"name": "Giuseppe Trisciuoglio",
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "developer-kit-python",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"description": "Python development capabilities",
|
||||
"author": {
|
||||
"name": "Giuseppe Trisciuoglio",
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "developer-kit-specs",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"description": "Specifications-driven development workflow for transforming ideas into functional specifications and executable tasks",
|
||||
"author": {
|
||||
"name": "Giuseppe Trisciuoglio",
|
||||
@@ -34,6 +34,8 @@
|
||||
"./agents/session-tracking-agent.md"
|
||||
],
|
||||
"skills": [
|
||||
"./skills/constitution",
|
||||
"./skills/create-pr-from-spec",
|
||||
"./skills/knowledge-graph",
|
||||
"./skills/ralph-loop",
|
||||
"./skills/specs-code-cleanup",
|
||||
|
||||
@@ -6,6 +6,7 @@ Specifications-driven development workflow for transforming ideas into functiona
|
||||
|
||||
This plugin provides a complete workflow for transforming ideas into implemented code:
|
||||
|
||||
- **Constitution**: Define the architectural DNA of the project — non-negotiable principles, approved stack, AI guardrails, and security constraints
|
||||
- **Brainstorming**: Transform ideas into pure functional specifications (WHAT, not HOW)
|
||||
- **Task Generation**: Convert functional specifications into executable tasks
|
||||
- **Task Management**: Add, split, update, and manage tasks
|
||||
@@ -20,6 +21,9 @@ This plugin provides a complete workflow for transforming ideas into implemented
|
||||
## Quick Start
|
||||
|
||||
```bash
|
||||
# 0. Define project constitution (once per project)
|
||||
/developer-kit-specs:constitution create
|
||||
|
||||
# 1. Create a functional specification
|
||||
/developer-kit-specs:specs.brainstorm "Add user authentication with JWT tokens"
|
||||
|
||||
@@ -42,8 +46,8 @@ This plugin provides a complete workflow for transforming ideas into implemented
|
||||
## Workflow
|
||||
|
||||
```
|
||||
Idea → Functional Specification → Tasks → TDD / Implementation → Review → Cleanup → Done
|
||||
(brainstorm) (spec-to-tasks) (task-tdd) (task-review) (code-cleanup)
|
||||
Constitution → Idea → Functional Specification → Tasks → TDD / Implementation → Review → Cleanup → Done
|
||||
(constitution) (brainstorm) (spec-to-tasks) (task-tdd) (task-review) (code-cleanup)
|
||||
```
|
||||
|
||||
## Specification Structure
|
||||
@@ -56,8 +60,12 @@ docs/specs/001-user-auth/
|
||||
├── user-request.md # Original user input
|
||||
├── brainstorming-notes.md # Brainstorming session context
|
||||
├── decision-log.md # Decision audit trail
|
||||
├── data-model.md # Generated from spec-to-tasks
|
||||
├── contracts/ # Generated interface artifacts
|
||||
│ ├── auth-api.openapi.yaml
|
||||
│ └── README.md
|
||||
├── traceability-matrix.md # Requirements-to-task mapping
|
||||
├── knowledge-graph.json # Cached codebase analysis
|
||||
├── knowledge-graph.json # Optional cached codebase analysis
|
||||
└── tasks/
|
||||
├── TASK-001.md # Individual task
|
||||
├── TASK-001--kpi.json # KPI analysis (auto-generated)
|
||||
@@ -67,6 +75,15 @@ docs/specs/001-user-auth/
|
||||
|
||||
## Commands
|
||||
|
||||
### Constitution
|
||||
|
||||
| Command | Description |
|
||||
|---------|-------------|
|
||||
| `/developer-kit-specs:constitution create` | Create `docs/specs/architecture.md` and/or `docs/specs/ontology.md` as project setup |
|
||||
| `/developer-kit-specs:constitution update --section=...` | Update a specific section of the constitution |
|
||||
| `/developer-kit-specs:constitution check --target=...` | Validate a spec/task/file against the constitution |
|
||||
| `/developer-kit-specs:constitution show` | Display the current constitution |
|
||||
|
||||
### Specification Creation
|
||||
|
||||
| Command | Description |
|
||||
@@ -348,6 +365,15 @@ Hooks automate task management:
|
||||
|
||||
## Skills
|
||||
|
||||
### constitution
|
||||
|
||||
Establishes and maintains the architectural DNA of a project through two shared documents:
|
||||
- `docs/specs/architecture.md` — approved stack, architectural rules, AI guardrails, security constraints (CWE mappings)
|
||||
- `docs/specs/ontology.md` — domain glossary (Ubiquitous Language), bounded contexts
|
||||
- Can be used **before brainstorm** as a project setup step
|
||||
- Provides `create`, `update`, `check`, and `show` operations
|
||||
- Constitution Check validates specs and tasks with CRITICAL / WARNING / OK severity levels
|
||||
|
||||
### knowledge-graph
|
||||
|
||||
Persistent JSON file that stores discoveries from codebase analysis:
|
||||
|
||||
@@ -0,0 +1,33 @@
|
||||
---
|
||||
description: "Cancel an active Ralph Loop background job (WHAT: stops a running ralph-loop-v2 job by ID). Use WHEN: a background Ralph Loop job needs to be terminated early."
|
||||
argument-hint: '[job-id]'
|
||||
disable-model-invocation: true
|
||||
allowed-tools: Bash(python3:*)
|
||||
---
|
||||
|
||||
## Overview
|
||||
|
||||
Cancels an active Ralph Loop background job in the current repository. The job is stopped and its state is preserved for potential resumption.
|
||||
|
||||
## Usage
|
||||
|
||||
```bash
|
||||
/developer-kit-specs:specs.ralph-loop-cancel <job-id>
|
||||
```
|
||||
|
||||
## Arguments
|
||||
|
||||
| Argument | Required | Description |
|
||||
|----------|----------|-------------|
|
||||
| `job-id` | Yes | The ID of the background job to cancel |
|
||||
|
||||
## Examples
|
||||
|
||||
```bash
|
||||
# Cancel a specific background job
|
||||
/developer-kit-specs:specs.ralph-loop-cancel abc123
|
||||
```
|
||||
|
||||
## Execution
|
||||
|
||||
!`python3 "${CLAUDE_PLUGIN_ROOT}/scripts/main.py" cancel $ARGUMENTS`
|
||||
@@ -0,0 +1,54 @@
|
||||
---
|
||||
description: "Show active and recent Ralph Loop jobs (WHAT: displays status table or full details for a specific job). Use WHEN: checking progress of background Ralph Loop jobs."
|
||||
argument-hint: '[job-id] [--all]'
|
||||
disable-model-invocation: true
|
||||
allowed-tools: Bash(python3:*)
|
||||
---
|
||||
|
||||
## Overview
|
||||
|
||||
Displays active and recent Ralph Loop background jobs for the current repository. Without arguments, shows a summary table of all jobs. With a job ID, shows full details for a specific job.
|
||||
|
||||
## Usage
|
||||
|
||||
```bash
|
||||
# Show all active/recent jobs
|
||||
/developer-kit-specs:specs.ralph-loop-status
|
||||
|
||||
# Show full details for a specific job
|
||||
/developer-kit-specs:specs.ralph-loop-status <job-id>
|
||||
|
||||
# Show all jobs including completed ones
|
||||
/developer-kit-specs:specs.ralph-loop-status --all
|
||||
```
|
||||
|
||||
## Arguments
|
||||
|
||||
| Argument | Required | Description |
|
||||
|----------|----------|-------------|
|
||||
| `job-id` | No | Show full details for a specific job |
|
||||
| `--all` | No | Include completed jobs in the listing |
|
||||
|
||||
## Examples
|
||||
|
||||
```bash
|
||||
# Check all active jobs
|
||||
/developer-kit-specs:specs.ralph-loop-status
|
||||
|
||||
# Check a specific job's full output
|
||||
/developer-kit-specs:specs.ralph-loop-status abc123
|
||||
|
||||
# Show all jobs including completed
|
||||
/developer-kit-specs:specs.ralph-loop-status --all
|
||||
```
|
||||
|
||||
## Execution
|
||||
|
||||
!`python3 "${CLAUDE_PLUGIN_ROOT}/scripts/main.py" status $ARGUMENTS`
|
||||
|
||||
If the user **did not** pass a job ID:
|
||||
- Render the output as a single Markdown table with columns: ID, Status, Phase, Progress, Created.
|
||||
- Compact: no extra prose outside the table.
|
||||
|
||||
If the user **has** passed a job ID:
|
||||
- Present the full command output without summarizing.
|
||||
@@ -0,0 +1,97 @@
|
||||
---
|
||||
description: "Ralph Loop orchestrator for spec-driven development (WHAT: runs the SDD state machine one step at a time). Use WHEN: automating the implement-review-fix-sync cycle for specification tasks."
|
||||
argument-hint: '[--wait|--background] [--spec <path>] [--action start|loop|next|status] [--from-task <id>] [--to-task <id>]'
|
||||
allowed-tools: Read, Glob, Grep, Bash(python3:*), Bash(git:*), AskUserQuestion
|
||||
---
|
||||
|
||||
## Overview
|
||||
|
||||
The Ralph Loop applies the "Ralph Wiggum as a Software Engineer" technique to specification-driven development. It solves context window explosion by executing **one step per invocation**, persisting state in `fix_plan.json`.
|
||||
|
||||
State machine: `init → choose_task → implementation → review → fix → cleanup → sync → update_done → (loop)`
|
||||
|
||||
## Usage
|
||||
|
||||
```bash
|
||||
# Initialize a new loop
|
||||
/developer-kit-specs:specs.ralph-loop --action=start --spec=docs/specs/001-feature/ --from-task=TASK-001 --to-task=TASK-010
|
||||
|
||||
# Run one step (execute shown command, then run loop again)
|
||||
/developer-kit-specs:specs.ralph-loop --action=loop --spec=docs/specs/001-feature/
|
||||
|
||||
# Advance state after executing the shown command
|
||||
/developer-kit-specs:specs.ralph-loop --action=next --spec=docs/specs/001-feature/
|
||||
|
||||
# Check status
|
||||
/developer-kit-specs:specs.ralph-loop --action=status --spec=docs/specs/001-feature/
|
||||
```
|
||||
|
||||
## Arguments
|
||||
|
||||
| Argument | Required | Description |
|
||||
|----------|----------|-------------|
|
||||
| `--action` | Yes | Action to perform: `start`, `loop`, `next`, `status` |
|
||||
| `--spec` | No | Path to spec folder (auto-detected from git branch if omitted) |
|
||||
| `--from-task` | No | Starting task ID (for `start` action) |
|
||||
| `--to-task` | No | Ending task ID (for `start` action) |
|
||||
| `--wait` | No | Run in foreground, wait for results |
|
||||
| `--background` | No | Run in background without prompting |
|
||||
|
||||
## Current Context
|
||||
|
||||
If `--spec` is omitted, the spec folder is auto-detected from the current git branch:
|
||||
|
||||
```bash
|
||||
branch=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/current_branch.py")
|
||||
spec_folder=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/find_spec_from_branch.py")
|
||||
```
|
||||
|
||||
If no matching spec folder is found for the current branch, stop and inform the user.
|
||||
|
||||
## Execution mode rules
|
||||
|
||||
- If the raw arguments include `--wait`, run in the foreground without asking.
|
||||
- If the raw arguments include `--background`, run in the background without asking.
|
||||
- Otherwise, use `AskUserQuestion` exactly once with two options, putting the recommended option first and suffixing its label with `(Recommended)`:
|
||||
- `Run in background (Recommended)`
|
||||
- `Wait for results`
|
||||
|
||||
## Foreground flow
|
||||
|
||||
Run:
|
||||
|
||||
```bash
|
||||
python3 ${CLAUDE_PLUGIN_ROOT}/scripts/main.py $ARGUMENTS
|
||||
```
|
||||
|
||||
Return the command stdout verbatim.
|
||||
|
||||
## Background flow
|
||||
|
||||
Launch with `Bash` in the background:
|
||||
|
||||
```typescript
|
||||
Bash({
|
||||
command: `python3 ${CLAUDE_PLUGIN_ROOT}/scripts/main.py $ARGUMENTS`,
|
||||
description: "Ralph Loop",
|
||||
run_in_background: true
|
||||
})
|
||||
```
|
||||
|
||||
After launching, tell the user: "Ralph Loop started in the background."
|
||||
|
||||
## Examples
|
||||
|
||||
```bash
|
||||
# Initialize
|
||||
/developer-kit-specs:specs.ralph-loop --action=start --spec=docs/specs/001-feature/ --from-task=TASK-001 --to-task=TASK-010
|
||||
|
||||
# Run one step
|
||||
/developer-kit-specs:specs.ralph-loop --action=loop --spec=docs/specs/001-feature/
|
||||
|
||||
# Advance state after executing the shown command
|
||||
/developer-kit-specs:specs.ralph-loop --action=next --spec=docs/specs/001-feature/
|
||||
|
||||
# Check status
|
||||
/developer-kit-specs:specs.ralph-loop --action=status --spec=docs/specs/001-feature/
|
||||
```
|
||||
@@ -83,6 +83,17 @@ The command evaluates four main dimensions:
|
||||
|----------|----------|-------------|
|
||||
| `spec-path` | No | Path to spec folder or file (default: auto-detect from CWD) |
|
||||
|
||||
## Current Context
|
||||
|
||||
If `--spec` is omitted, the spec folder is auto-detected from the current git branch:
|
||||
|
||||
```bash
|
||||
branch=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/current_branch.py")
|
||||
spec_folder=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/find_spec_from_branch.py")
|
||||
```
|
||||
|
||||
If no matching spec folder is found for the current branch, stop and inform the user.
|
||||
|
||||
## Core Principles
|
||||
|
||||
- **Maximum 5 questions**: Focus on the most impactful ambiguities
|
||||
|
||||
@@ -51,6 +51,17 @@ Idea → Specs → Tasks → Implementation → Spec Sync Context (this)
|
||||
| `--task` | No | Update context after specific task completion |
|
||||
| `--dry-run` | No | Show planned changes without executing them |
|
||||
|
||||
## Current Context
|
||||
|
||||
If `--spec` is omitted, the spec folder is auto-detected from the current git branch:
|
||||
|
||||
```bash
|
||||
branch=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/current_branch.py")
|
||||
spec_folder=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/find_spec_from_branch.py")
|
||||
```
|
||||
|
||||
If no matching spec folder is found for the current branch, stop and inform the user.
|
||||
|
||||
## Core Principles
|
||||
|
||||
- **Incremental updates**: Only update what has changed, don't rewrite everything
|
||||
|
||||
@@ -52,6 +52,17 @@ Idea → Spec → Tasks → Implementation → Spec Sync With Code (this)
|
||||
| `spec-folder` | No | Path to spec folder (default: detect from CWD) |
|
||||
| `--after-task` | No | Specific task ID that just completed |
|
||||
|
||||
## Current Context
|
||||
|
||||
If `--spec` is omitted, the spec folder is auto-detected from the current git branch:
|
||||
|
||||
```bash
|
||||
branch=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/current_branch.py")
|
||||
spec_folder=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/find_spec_from_branch.py")
|
||||
```
|
||||
|
||||
If no matching spec folder is found for the current branch, stop and inform the user.
|
||||
|
||||
---
|
||||
|
||||
## Phase 1: Discovery
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
---
|
||||
description: "Provides capability to convert functional specifications into executable and trackable tasks. Use when needing to transform a spec from devkit.brainstorm into a task list. Output: docs/specs/[id]/YYYY-MM-DD-feature-name--tasks.md plus individual task files"
|
||||
description: "Provides capability to convert functional specifications into executable and trackable tasks. Use when needing to transform a spec from devkit.brainstorm into a task list. Output: docs/specs/[id]/YYYY-MM-DD-feature-name--tasks.md, data-model.md, contracts/, and individual task files"
|
||||
argument-hint: "[ --lang=java|spring|typescript|nestjs|react|python|general ] [ --spec=\"spec-folder\" ]"
|
||||
allowed-tools: Task, Read, Write, Edit, Bash, Grep, Glob, TodoWrite, AskUserQuestion
|
||||
model: inherit
|
||||
@@ -16,6 +16,8 @@ This command reads a functional specification generated by `/developer-kit-specs
|
||||
**Input**: `docs/specs/[id]/YYYY-MM-DD--feature-name.md`
|
||||
**Output**:
|
||||
- Task list: `docs/specs/[id]/YYYY-MM-DD--feature-name--tasks.md`
|
||||
- Data model: `docs/specs/[id]/data-model.md`
|
||||
- Contracts: `docs/specs/[id]/contracts/*`
|
||||
- Individual tasks: `docs/specs/[id]/tasks/TASK-XXX.md`
|
||||
|
||||
### Task Structure
|
||||
@@ -101,6 +103,15 @@ The command will automatically gather context information when needed:
|
||||
- Recent commits and changes
|
||||
- Available when the repository has history
|
||||
|
||||
If `spec-file` is omitted, the spec folder is auto-detected from the current git branch:
|
||||
|
||||
```bash
|
||||
branch=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/current_branch.py")
|
||||
spec_folder=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/find_spec_from_branch.py")
|
||||
```
|
||||
|
||||
If no matching spec folder is found for the current branch, stop and inform the user.
|
||||
|
||||
---
|
||||
|
||||
You are converting a functional specification into executable tasks. Follow a systematic approach: analyze requirements, identify dependencies, generate atomic tasks, and create a trackable task list.
|
||||
@@ -653,88 +664,63 @@ Provide a comprehensive summary that will inform task generation.
|
||||
|
||||
---
|
||||
|
||||
## Phase 3.5: Update Knowledge Graph
|
||||
## Phase 3.5: Specification Artifact Generation
|
||||
|
||||
**Goal**: Persist agent discoveries into the Knowledge Graph for future reuse
|
||||
**Goal**: Always derive stable specification artifacts before task generation
|
||||
|
||||
**Prerequisite**: Phase 3 (Codebase Analysis) must have completed
|
||||
**Prerequisite**: Phase 2 (Requirement Extraction) must have completed. Phase 3 findings may be used only to align naming with the existing codebase.
|
||||
|
||||
**Actions**:
|
||||
|
||||
1. **Extract structured findings from agent analysis**:
|
||||
- Parse the agent's comprehensive analysis output
|
||||
- Map findings to KG schema sections:
|
||||
- `patterns.architectural`: Design patterns discovered (Repository, Service Layer, etc.)
|
||||
- `patterns.conventions`: Coding conventions (naming, testing, etc.)
|
||||
- `components`: Code components identified (controllers, services, repositories, entities)
|
||||
- `apis.internal`: REST endpoints and API structure
|
||||
- `apis.external`: External service integrations
|
||||
- `integration_points`: Database, cache, message queues, etc.
|
||||
1. **Generate `data-model.md` from the specification**:
|
||||
- Create/update `docs/specs/[id]/data-model.md`
|
||||
- Use the resolved specification, `user-request.md`, and `brainstorming-notes.md` as the source of truth
|
||||
- Incorporate canonical terminology from `docs/specs/ontology.md` when available
|
||||
- Capture:
|
||||
- Core entities, value objects, and aggregates
|
||||
- Relationships and cardinality
|
||||
- Lifecycle/state transitions if relevant
|
||||
- Business invariants and validation rules
|
||||
- Persistence or integration notes explicitly stated in the specification
|
||||
|
||||
2. **Construct KG update object**:
|
||||
```json
|
||||
{
|
||||
"metadata": {
|
||||
"spec_id": "[extracted from folder]",
|
||||
"feature_name": "[extracted from folder]",
|
||||
"updated_at": "[current ISO timestamp]",
|
||||
"analysis_sources": [
|
||||
{
|
||||
"agent": "[agent-type-used]",
|
||||
"timestamp": "[current ISO timestamp]",
|
||||
"focus": "codebase analysis for task generation"
|
||||
}
|
||||
]
|
||||
},
|
||||
"codebase_context": {
|
||||
"project_structure": { /* from agent analysis */ },
|
||||
"technology_stack": { /* from agent analysis */ }
|
||||
},
|
||||
"patterns": {
|
||||
"architectural": [ /* patterns discovered */ ],
|
||||
"conventions": [ /* conventions identified */ ]
|
||||
},
|
||||
"components": {
|
||||
"controllers": [ /* controllers found */ ],
|
||||
"services": [ /* services found */ ],
|
||||
"repositories": [ /* repositories found */ ],
|
||||
"entities": [ /* entities found */ ],
|
||||
"dtos": [ /* DTOs found */ ]
|
||||
},
|
||||
"apis": {
|
||||
"internal": [ /* endpoints discovered */ ],
|
||||
"external": [ /* external integrations */ ]
|
||||
},
|
||||
"integration_points": [ /* databases, caches, etc. */ ]
|
||||
}
|
||||
2. **Create/update the `contracts/` directory**:
|
||||
- Ensure `docs/specs/[id]/contracts/` exists
|
||||
- Extract every explicit interface or integration boundary described by the specification
|
||||
- Create one contract artifact per boundary using the most appropriate format:
|
||||
- HTTP/API boundary: `[name].openapi.yaml`
|
||||
- Async event/message boundary: `[name].event.md`
|
||||
- Internal service/UI boundary without a formal schema: `[name].md`
|
||||
|
||||
3. **Populate each contract artifact with implementation-neutral details**:
|
||||
- Required inputs and outputs
|
||||
- Validation rules and required fields
|
||||
- Success responses or emitted events
|
||||
- Error cases and failure modes
|
||||
- Versioning or backward-compatibility notes if stated in the spec
|
||||
|
||||
4. **Handle specs without explicit external contracts**:
|
||||
- Still create `docs/specs/[id]/contracts/`
|
||||
- Add `contracts/README.md` summarizing why no standalone interface contract files were extracted yet
|
||||
- Document any implicit boundaries that tasks must preserve
|
||||
|
||||
5. **Treat artifacts as mandatory inputs for task generation**:
|
||||
- Phase 4 and Phase 5 must read `data-model.md` and `contracts/*`
|
||||
- Tasks must reference these artifacts in technical context, implementation details, and test instructions when relevant
|
||||
|
||||
6. **Do NOT update agent context files in this phase**:
|
||||
- Do not call `/developer-kit-specs:specs.spec-sync-context`
|
||||
- Do not create or modify `knowledge-graph.json`
|
||||
- Do not rewrite task files or any other context cache as part of artifact generation
|
||||
|
||||
7. **Log and report**:
|
||||
```
|
||||
Specification artifacts generated:
|
||||
- Data model: docs/specs/[ID]/data-model.md
|
||||
- Contracts directory: docs/specs/[ID]/contracts/
|
||||
- Contract files: [list generated files]
|
||||
```
|
||||
|
||||
3. **Update Knowledge Graph** using spec-sync-context command:
|
||||
- Call: `/developer-kit-specs:specs.spec-sync-context [spec-folder] --update-kg-only`
|
||||
- The spec-sync-context command will:
|
||||
- Create/update `knowledge-graph.json` with discovered patterns
|
||||
- Document components, APIs, and integration points
|
||||
- Update `metadata.updated_at` and `metadata.analysis_sources`
|
||||
- Generate summary report of changes
|
||||
|
||||
4. **Log and report**:
|
||||
```
|
||||
Knowledge Graph updated via spec-sync-context:
|
||||
- X architectural patterns documented
|
||||
- Y coding conventions identified
|
||||
- Z components catalogued (N controllers, M services, K repositories)
|
||||
- Q API endpoints documented
|
||||
- R integration points mapped
|
||||
|
||||
Saved to: docs/specs/[ID]/knowledge-graph.json
|
||||
```
|
||||
|
||||
5. **Verify update**:
|
||||
- Read back the updated KG to confirm write succeeded
|
||||
- Check that metadata was updated correctly
|
||||
- If write failed, log warning but continue (non-blocking)
|
||||
|
||||
**Note**: If user chose to use cached KG in Phase 2.5, **skip this phase** and proceed directly to Phase 4.
|
||||
**Note**: This phase always runs, even when a cached Knowledge Graph is reused in Phase 2.5.
|
||||
|
||||
---
|
||||
|
||||
@@ -744,7 +730,12 @@ Provide a comprehensive summary that will inform task generation.
|
||||
|
||||
**Actions**:
|
||||
|
||||
1. **If Knowledge Graph context is available** (from Phase 2.5 cached or Phase 3.5 updated):
|
||||
1. **Always review generated specification artifacts**:
|
||||
- Read `docs/specs/[id]/data-model.md` for entities, relationships, invariants, and states
|
||||
- Read `docs/specs/[id]/contracts/*` for request/response, event, or boundary definitions
|
||||
- Use these artifacts to define task boundaries, data responsibilities, integration points, and test expectations
|
||||
|
||||
1.1. **If Knowledge Graph context is available** (from Phase 2.5 cached only):
|
||||
- Review KG patterns: Architectural patterns to follow in each task
|
||||
- Review KG components: Existing components to reuse or integrate with
|
||||
- Review KG APIs: Internal/external APIs relevant to tasks
|
||||
@@ -753,14 +744,14 @@ Provide a comprehensive summary that will inform task generation.
|
||||
- Example: "Follow existing Repository Pattern - extend JpaRepository"
|
||||
- Example: "Integrate with existing HotelService.searchHotels() method"
|
||||
|
||||
1.1. **If Architecture context is available** (from Phase 1.5):
|
||||
1.2. **If Architecture context is available** (from Phase 1.5):
|
||||
- Use the technology stack to inform implementation details in each task
|
||||
- Ensure tasks reference the correct frameworks, libraries, and patterns from `docs/specs/architecture.md`
|
||||
- If tasks require new infrastructure components not in the architecture document, flag them for ADR tracking using the `adr-drafting` skill
|
||||
- Example: "Use NestJS module pattern as defined in architecture.md"
|
||||
- Example: "Follow PostgreSQL with Drizzle ORM as specified in architecture"
|
||||
|
||||
1.2. **If Ontology context is available** (from Phase 1.5):
|
||||
1.3. **If Ontology context is available** (from Phase 1.5):
|
||||
- Use domain terms from `docs/specs/ontology.md` consistently in task titles, descriptions, and acceptance criteria
|
||||
- Ensure task descriptions use the canonical term from the glossary (avoid synonyms not defined in the ontology)
|
||||
- If a task introduces NEW domain concepts not in the ontology, add them to `docs/specs/ontology.md` and update the `Last Updated` date
|
||||
@@ -1024,7 +1015,7 @@ Each task has its own detailed file with technical context:
|
||||
- **Cleanup Task** (TASK-N): Final code quality and hygiene cleanup
|
||||
```
|
||||
|
||||
6. Save all files (including traceability-matrix.md from Phase 5.5)
|
||||
6. Save all files (including `data-model.md`, `contracts/*`, and `traceability-matrix.md`)
|
||||
|
||||
---
|
||||
|
||||
@@ -1108,11 +1099,16 @@ Each task has its own detailed file with technical context:
|
||||
- **Ontology**: Loaded, created, or skipped `docs/specs/ontology.md` — [N terms]
|
||||
- **Codebase Analyzed**: Yes (language: [language])
|
||||
- **Key Findings**: [patterns, integration points, conventions]
|
||||
- **Specification Artifacts**:
|
||||
- Data model: `docs/specs/[id]/data-model.md`
|
||||
- Contracts: `docs/specs/[id]/contracts/*`
|
||||
- **Tasks Generated**: Number of tasks created (breakdown: X implementation, 1 e2e test, 1 cleanup)
|
||||
- **Dependency Structure**: Brief overview of task dependencies
|
||||
- **Spec Size Status**: [If >15 tasks were detected: "WARNING: Spec exceeds 15-task limit. User chose to continue anyway" OR "Aborted: User returned to brainstorm to split specification"]
|
||||
- **Output Files**:
|
||||
- Task list: `docs/specs/[id]/YYYY-MM-DD--feature-name--tasks.md`
|
||||
- Data model: `docs/specs/[id]/data-model.md`
|
||||
- Contracts: `docs/specs/[id]/contracts/*`
|
||||
- Individual tasks: `docs/specs/[id]/tasks/TASK-XXX.md` (with technical context)
|
||||
- E2E test task: `docs/specs/[id]/tasks/TASK-N-1.md` (depends on all implementation tasks)
|
||||
- Cleanup task: `docs/specs/[id]/tasks/TASK-N.md` (depends on e2e test task, uses specs-code-cleanup skill)
|
||||
@@ -1194,6 +1190,10 @@ Output structure:
|
||||
docs/specs/001-user-auth/
|
||||
├── 2026-03-07--user-auth-specs.md
|
||||
├── 2026-03-07--user-auth--tasks.md
|
||||
├── data-model.md
|
||||
├── contracts/
|
||||
│ ├── auth-api.openapi.yaml
|
||||
│ └── auth-session.md
|
||||
└── tasks/
|
||||
├── TASK-001.md (User registration endpoint)
|
||||
├── TASK-002.md (Login endpoint)
|
||||
|
||||
@@ -24,6 +24,18 @@ This command follows a focused workflow optimized for single-task implementation
|
||||
|--------------|------------------------------------------|
|
||||
| `$ARGUMENTS` | Combined arguments passed to the command |
|
||||
|
||||
## Current Context
|
||||
|
||||
If `--task` is omitted, the task is auto-detected from the current git branch:
|
||||
|
||||
```bash
|
||||
branch=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/current_branch.py")
|
||||
spec_folder=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/find_spec_from_branch.py")
|
||||
# Find the first pending/in_progress task in the spec folder
|
||||
```
|
||||
|
||||
If no task can be auto-detected, ask the user which task to implement.
|
||||
|
||||
## Task Mode Detection
|
||||
|
||||
This command ONLY operates in Task Mode. If no `--task=` parameter is provided, inform the user that they should use the spec-driven flow (`devkit.brainstorm` → `devkit.spec-to-tasks`) or `/developer-kit:devkit.feature-development` for non-spec work.
|
||||
|
||||
@@ -54,6 +54,17 @@ This command provides task management capabilities after initial task generation
|
||||
| `--spec` | Conditional | Path to spec folder (required for `add`, `regenerate-index`, `list`) |
|
||||
| `--lang` | No | Language/framework hint for new tasks |
|
||||
|
||||
## Current Context
|
||||
|
||||
If `--spec` is omitted, the spec folder is auto-detected from the current git branch:
|
||||
|
||||
```bash
|
||||
branch=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/current_branch.py")
|
||||
spec_folder=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/find_spec_from_branch.py")
|
||||
```
|
||||
|
||||
If no matching spec folder is found for the current branch, stop and inform the user.
|
||||
|
||||
---
|
||||
|
||||
You are managing existing task files. Follow the appropriate process based on the requested action.
|
||||
|
||||
@@ -53,14 +53,15 @@ Idea → Functional Specification → Tasks → Implementation → Review → Co
|
||||
|
||||
## Current Context
|
||||
|
||||
The command will automatically gather context information when needed:
|
||||
- Current git branch and status
|
||||
- Recent commits and changes
|
||||
- Available when the repository has history
|
||||
If `--task` is omitted, the task is auto-detected from the current git branch:
|
||||
|
||||
---
|
||||
```bash
|
||||
branch=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/current_branch.py")
|
||||
spec_folder=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/find_spec_from_branch.py")
|
||||
# Find the first pending/in_progress task in the spec folder
|
||||
```
|
||||
|
||||
You are reviewing an implemented task to verify it meets specifications and passes code review. Follow a systematic approach: analyze the task, verify implementation, check spec compliance, and perform code review.
|
||||
If no task can be auto-detected, ask the user which task to review.
|
||||
|
||||
## Core Principles
|
||||
|
||||
|
||||
@@ -60,6 +60,18 @@ Task file updates are handled by `plugins/developer-kit-specs/hooks/specs-task-t
|
||||
| `--task` | Path to task file (from spec-to-tasks) | Yes |
|
||||
| `--lang` | Programming language/framework | Yes |
|
||||
|
||||
## Current Context
|
||||
|
||||
If `--task` is omitted, the task is auto-detected from the current git branch:
|
||||
|
||||
```bash
|
||||
branch=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/current_branch.py")
|
||||
spec_folder=$(python3 "${CLAUDE_PLUGIN_ROOT}/scripts/find_spec_from_branch.py")
|
||||
# Find the first pending task in the spec folder
|
||||
```
|
||||
|
||||
If no task can be auto-detected, ask the user which task to generate TDD tests for.
|
||||
|
||||
## Supported Languages
|
||||
|
||||
| Language | `--lang` Value | Test Framework | File Location |
|
||||
|
||||
@@ -4,7 +4,71 @@ Complete reference for all SDD commands with arguments, options, and real-world
|
||||
|
||||
---
|
||||
|
||||
## `/developer-kit-specs:specs.brainstorm`
|
||||
## `/developer-kit-specs:constitution`
|
||||
|
||||
Establish and maintain the architectural DNA of a project through two shared documents: `docs/specs/architecture.md` (technology stack, rules, guardrails) and `docs/specs/ontology.md` (domain glossary / Ubiquitous Language). Can be used before `brainstorm` as a project setup step.
|
||||
|
||||
### Syntax
|
||||
|
||||
```
|
||||
/developer-kit-specs:constitution [operation] [options]
|
||||
```
|
||||
|
||||
### Operations
|
||||
|
||||
| Operation | Description |
|
||||
|-----------|-------------|
|
||||
| `create` | Interactively create `docs/specs/architecture.md` and/or `docs/specs/ontology.md` |
|
||||
| `update` | Update a specific section of the existing constitution |
|
||||
| `check` | Validate a spec, task, or file against the constitution |
|
||||
| `show` | Display the current constitution |
|
||||
|
||||
### Options
|
||||
|
||||
| Option | Required | Description |
|
||||
|--------|----------|-------------|
|
||||
| `--section` | For `update` | Section to update: `stack`, `architecture`, `api`, `testing`, `security`, `guardrails` |
|
||||
| `--target` | For `check` | Path to the spec/task/file to validate |
|
||||
|
||||
### When to Use
|
||||
|
||||
- **`create`**: First step of any new SDD project — run before `brainstorm`
|
||||
- **`update`**: When technology choices or security requirements change
|
||||
- **`check`**: Before approving a spec or task plan; integrated into `task-review`
|
||||
- **`show`**: Quick reference during development
|
||||
|
||||
### Constitution Check Report
|
||||
|
||||
The `check` operation produces a report with three severity levels:
|
||||
|
||||
| Level | Meaning |
|
||||
|-------|---------|
|
||||
| `CRITICAL` | Violates a non-negotiable rule — must fix before proceeding |
|
||||
| `WARNING` | Deviates from a recommended practice — should fix |
|
||||
| `OK` | Compliant |
|
||||
|
||||
### Examples
|
||||
|
||||
```bash
|
||||
# Create constitution for a new project (interactive)
|
||||
/developer-kit-specs:constitution create
|
||||
|
||||
# Validate a spec against the constitution
|
||||
/developer-kit-specs:constitution check --target=docs/specs/001-user-auth/2026-04-10--user-auth.md
|
||||
|
||||
# Validate a task plan
|
||||
/developer-kit-specs:constitution check --target=docs/specs/001-user-auth/tasks/TASK-003.md
|
||||
|
||||
# Update the security section
|
||||
/developer-kit-specs:constitution update --section=security
|
||||
|
||||
# Show current constitution
|
||||
/developer-kit-specs:constitution show
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## `/specs:brainstorm`
|
||||
|
||||
Transform ideas into full functional specifications through guided brainstorming.
|
||||
|
||||
@@ -146,16 +210,16 @@ Convert a functional specification into executable task files.
|
||||
| `--lang` | Recommended | Target language: `java`, `spring`, `typescript`, `nestjs`, `react`, `python`, `php`, `general` |
|
||||
| `spec-folder` | Yes | Path to the specification directory |
|
||||
|
||||
### Process (7 Phases)
|
||||
### Process (11 Phases)
|
||||
|
||||
| Phase | Name | Description |
|
||||
|-------|------|-------------|
|
||||
| 1 | Specification Analysis | Read and understand the spec |
|
||||
| 1.5 | Architecture & Ontology | Ensure technical foundation exists |
|
||||
| 2 | Requirement Extraction | Organize requirements, assign REQ-IDs |
|
||||
| 2.5 | Knowledge Graph | Load or create cached codebase analysis |
|
||||
| 2.5 | Knowledge Graph | Load cached codebase analysis when available |
|
||||
| 3 | Codebase Analysis | Language-specific exploration |
|
||||
| 3.5 | Update Knowledge Graph | Persist discoveries |
|
||||
| 3.5 | Spec Artifact Generation | Always generate `data-model.md` and `contracts/*` from the specification |
|
||||
| 4 | Task Decomposition | Break into atomic tasks |
|
||||
| 5 | Task Generation | Create task files and index |
|
||||
| 5.5 | Traceability Matrix | Map requirements to tasks |
|
||||
@@ -171,14 +235,19 @@ Maximum 15 implementation tasks per specification. If exceeded, the command reje
|
||||
```
|
||||
docs/specs/[ID-feature]/
|
||||
├── YYYY-MM-DD--feature-name--tasks.md # Task index
|
||||
├── knowledge-graph.json # Codebase analysis cache
|
||||
├── data-model.md # Generated domain/data model
|
||||
├── traceability-matrix.md # Requirements mapping
|
||||
├── contracts/ # Generated interface contracts
|
||||
│ ├── *.openapi.yaml
|
||||
│ └── *.md
|
||||
└── tasks/
|
||||
├── TASK-001.md
|
||||
├── TASK-002.md
|
||||
└── ...
|
||||
```
|
||||
|
||||
If a prior `knowledge-graph.json` exists, it may be reused as input, but `spec-to-tasks` does not update agent context files as part of this workflow.
|
||||
|
||||
### Examples
|
||||
|
||||
```bash
|
||||
|
||||
@@ -4,7 +4,9 @@ This guide walks you through the core concepts of SDD and gets you productive in
|
||||
|
||||
## What is SDD?
|
||||
|
||||
Specification-Driven Development (SDD) is a workflow where you define **WHAT** you want to build before writing any code. The specification becomes a contract between your idea and the implementation, enforced through automated quality gates.
|
||||
Specification-Driven Development (SDD) is a workflow where you define **WHAT** you want to build before writing any
|
||||
code. The specification becomes a contract between your idea and the implementation, enforced through automated quality
|
||||
gates.
|
||||
|
||||
```
|
||||
Idea → Specification → Tasks → Implementation → Review → Cleanup → Done
|
||||
@@ -12,6 +14,7 @@ Idea → Specification → Tasks → Implementation → Review → Cleanup → D
|
||||
```
|
||||
|
||||
**Why SDD?**
|
||||
|
||||
- **Eliminates ambiguity**: Every feature is defined functionally before coding starts
|
||||
- **Traceability**: Every line of code traces back to a requirement
|
||||
- **Quality gates**: Automated review ensures nothing is missed
|
||||
@@ -45,6 +48,20 @@ Verify installation:
|
||||
|
||||
Let's build a real feature: **user authentication with JWT tokens** for a Spring Boot application.
|
||||
|
||||
### Step 0: Establish the Constitution (once per project)
|
||||
|
||||
Before writing any specification, define the architectural DNA of your project:
|
||||
|
||||
```
|
||||
/developer-kit-specs:constitution create
|
||||
```
|
||||
|
||||
Claude will ask about your technology stack, architectural rules, and security constraints, then generate
|
||||
`docs/specs/architecture.md` and optionally `docs/specs/ontology.md`. These documents act as non-negotiable guardrails
|
||||
for all AI-generated code throughout the project lifecycle.
|
||||
|
||||
You only run `create` once. After that, use `check` to validate specs and tasks against them.
|
||||
|
||||
### Step 1: Brainstorm the Idea
|
||||
|
||||
```
|
||||
@@ -64,6 +81,7 @@ Claude will guide you through a 9-phase process:
|
||||
9. **Summary** — Lists outputs and recommended next steps
|
||||
|
||||
**Output files created:**
|
||||
|
||||
```
|
||||
docs/specs/001-user-auth/
|
||||
├── 2026-04-10--user-auth.md # Main functional specification
|
||||
@@ -83,16 +101,21 @@ The specification is technology-agnostic. It describes behaviors, not implementa
|
||||
Claude analyzes your specification and generates executable tasks:
|
||||
|
||||
1. **Reads the specification** and extracts functional requirements
|
||||
2. **Explores your codebase** to understand existing patterns (Spring Security, User entities, etc.)
|
||||
3. **Breaks requirements into tasks** — atomic, testable units with clear acceptance criteria
|
||||
4. **Generates a traceability matrix** mapping requirements to tasks
|
||||
2. **Generates specification artifacts** (`data-model.md` and `contracts/*`) directly from the spec
|
||||
3. **Explores your codebase** to understand existing patterns (Spring Security, User entities, etc.)
|
||||
4. **Breaks requirements into tasks** — atomic, testable units with clear acceptance criteria
|
||||
5. **Generates a traceability matrix** mapping requirements to tasks
|
||||
|
||||
**Output files created:**
|
||||
|
||||
```
|
||||
docs/specs/001-user-auth/
|
||||
├── 2026-04-10--user-auth--tasks.md # Task index
|
||||
├── knowledge-graph.json # Cached codebase analysis
|
||||
├── data-model.md # Generated domain model
|
||||
├── traceability-matrix.md # Requirements → Tasks mapping
|
||||
├── contracts/ # Generated interface contracts
|
||||
│ ├── auth-api.openapi.yaml
|
||||
│ └── README.md
|
||||
└── tasks/
|
||||
├── TASK-001.md # Create User entity and repository
|
||||
├── TASK-002.md # Implement JWT token service
|
||||
@@ -103,6 +126,7 @@ docs/specs/001-user-auth/
|
||||
```
|
||||
|
||||
Each task file contains:
|
||||
|
||||
- **Frontmatter**: ID, title, status, dependencies, provides/expects contracts
|
||||
- **Description**: What to implement
|
||||
- **Acceptance Criteria**: Checkboxes for verification
|
||||
@@ -122,6 +146,7 @@ Claude follows a structured 12-step process:
|
||||
4. **Updates task status** — Automatically marks `in_progress` → `implemented`
|
||||
|
||||
**Hooks fire automatically:**
|
||||
|
||||
- `task-auto-status.py` updates the task frontmatter based on checkbox changes
|
||||
- `task-kpi-analyzer.py` calculates quality KPIs and saves them to `TASK-001--kpi.json`
|
||||
|
||||
@@ -133,12 +158,12 @@ Claude follows a structured 12-step process:
|
||||
|
||||
The review validates 4 dimensions:
|
||||
|
||||
| Dimension | What It Checks |
|
||||
|-----------|---------------|
|
||||
| **Implementation** | Does the code match the task description? |
|
||||
| **Acceptance Criteria** | Are all criteria met? |
|
||||
| **Spec Compliance** | Does it align with the original specification? |
|
||||
| **Code Quality** | Language-specific best practices, patterns, security |
|
||||
| Dimension | What It Checks |
|
||||
|-------------------------|------------------------------------------------------|
|
||||
| **Implementation** | Does the code match the task description? |
|
||||
| **Acceptance Criteria** | Are all criteria met? |
|
||||
| **Spec Compliance** | Does it align with the original specification? |
|
||||
| **Code Quality** | Language-specific best practices, patterns, security |
|
||||
|
||||
**Output:** `TASK-001--review.md` with pass/fail status and detailed findings.
|
||||
|
||||
@@ -151,6 +176,7 @@ If the review passes:
|
||||
```
|
||||
|
||||
This final step:
|
||||
|
||||
- Removes debug logs (`System.out.println`, temporary comments)
|
||||
- Optimizes imports
|
||||
- Runs language-specific formatters (`./mvnw spotless:apply`)
|
||||
@@ -165,28 +191,32 @@ After implementing several tasks, sync the spec with reality:
|
||||
/developer-kit-specs:specs.spec-sync-with-code docs/specs/001-user-auth/
|
||||
```
|
||||
|
||||
This detects deviations (scope expansions, refinements, reductions) and updates the specification to match what was actually built.
|
||||
This detects deviations (scope expansions, refinements, reductions) and updates the specification to match what was
|
||||
actually built.
|
||||
|
||||
## What's Next?
|
||||
|
||||
- **[SDD Workflow](./sdd-workflow.md)** — Complete workflow documentation with all phases
|
||||
- **[Commands Reference](./commands-reference.md)** — Detailed command documentation with examples
|
||||
- **[Ralph Loop Guide](./ralph-loop-guide.md)** — Automate task execution across multiple agents (manual and fully automated via `agents_loop.py`)
|
||||
- **[Ralph Loop Guide](./ralph-loop-guide.md)** — Automate task execution across multiple agents (manual and fully
|
||||
automated via `agents_loop.py`)
|
||||
- **[TDD Workflow](./tdd-workflow.md)** — Test-Driven Development integration
|
||||
- **[KPI Evaluation](./kpi-evaluation.md)** — Understanding quality metrics and scoring
|
||||
|
||||
## Quick Reference
|
||||
|
||||
| Command | Purpose |
|
||||
|---------|---------|
|
||||
| `/developer-kit-specs:specs.brainstorm "idea"` | Create a full specification |
|
||||
| `/developer-kit-specs:specs.quick-spec "fix"` | Create a minimal spec for small changes |
|
||||
| `/developer-kit-specs:specs.spec-to-tasks --lang=spring spec/` | Generate executable tasks |
|
||||
| `/developer-kit-specs:specs.task-implementation --lang=spring --task=TASK.md` | Implement a task |
|
||||
| `/developer-kit-specs:specs.task-tdd --lang=spring --task=TASK.md` | Generate failing tests first (RED) |
|
||||
| `/developer-kit-specs:specs.task-review --lang=spring TASK.md` | Review implementation |
|
||||
| `/developer-kit-specs:specs-code-cleanup --lang=spring --task=TASK.md` | Final cleanup |
|
||||
| `/developer-kit-specs:specs.spec-sync-with-code spec/` | Sync spec with implementation |
|
||||
| `/developer-kit-specs:specs.spec-sync-context spec/` | Sync Knowledge Graph and context |
|
||||
| `/developer-kit-specs:specs.task-manage --action=list` | List and manage tasks |
|
||||
| `agents_loop.py --spec=spec/ --agent=auto` | Fully automated multi-agent orchestration |
|
||||
| Command | Purpose |
|
||||
|-------------------------------------------------------------------------------|---------------------------------------------|
|
||||
| `/developer-kit-specs:constitution create` | Define project architectural DNA (run once) |
|
||||
| `/developer-kit-specs:constitution check --target=file` | Validate spec/task against constitution |
|
||||
| `/developer-kit-specs:specs.brainstorm "idea"` | Create a full specification |
|
||||
| `/developer-kit-specs:specs.quick-spec "fix"` | Create a minimal spec for small changes |
|
||||
| `/developer-kit-specs:specs.spec-to-tasks --lang=spring spec/` | Generate executable tasks |
|
||||
| `/developer-kit-specs:specs.task-implementation --lang=spring --task=TASK.md` | Implement a task |
|
||||
| `/developer-kit-specs:specs.task-tdd --lang=spring --task=TASK.md` | Generate failing tests first (RED) |
|
||||
| `/developer-kit-specs:specs.task-review --lang=spring TASK.md` | Review implementation |
|
||||
| `/developer-kit-specs:specs-code-cleanup --lang=spring --task=TASK.md` | Final cleanup |
|
||||
| `/developer-kit-specs:specs.spec-sync-with-code spec/` | Sync spec with implementation |
|
||||
| `/developer-kit-specs:specs.spec-sync-context spec/` | Sync Knowledge Graph and context |
|
||||
| `/developer-kit-specs:specs.task-manage --action=list` | List and manage tasks |
|
||||
| `agents_loop.py --spec=spec/ --agent=auto` | Fully automated multi-agent orchestration |
|
||||
|
||||
@@ -19,6 +19,9 @@ Every change should update all three vertices. The sync commands keep them align
|
||||
|
||||
```
|
||||
┌─────────────────────────────────────────────────────────────────────┐
|
||||
│ Phase 0: CONSTITUTION (first time only) │
|
||||
│ constitution create → defines architectural DNA of the project │
|
||||
├─────────────────────────────────────────────────────────────────────┤
|
||||
│ Phase 1: SPECIFICATION │
|
||||
│ brainstorm → spec-quality-check → spec-to-tasks │
|
||||
├─────────────────────────────────────────────────────────────────────┤
|
||||
@@ -35,6 +38,35 @@ Every change should update all three vertices. The sync commands keep them align
|
||||
|
||||
---
|
||||
|
||||
## Phase 0: Constitution (First-Time Setup)
|
||||
|
||||
Before writing any specification, establish the **architectural DNA** of your project:
|
||||
|
||||
```
|
||||
/developer-kit-specs:constitution create
|
||||
```
|
||||
|
||||
This creates `docs/specs/architecture.md` (and optionally `docs/specs/ontology.md`) — documents that define:
|
||||
- Approved technology stack and forbidden libraries
|
||||
- Architectural rules (e.g., constructor injection, no field injection)
|
||||
- API standards and authentication approach
|
||||
- Security constraints with CWE mappings
|
||||
- AI guardrails that govern all subsequent code generation
|
||||
|
||||
**You only run `create` once per project.** After that, use `update` to evolve them and `check` to validate specs/tasks against them.
|
||||
|
||||
```
|
||||
# Validate a spec against the constitution
|
||||
/developer-kit-specs:constitution check --target=docs/specs/001-user-auth/2026-04-10--user-auth.md
|
||||
|
||||
# Update a section
|
||||
/developer-kit-specs:constitution update --file=architecture --section=security
|
||||
```
|
||||
|
||||
The constitution feeds into every subsequent phase — brainstorm, spec-to-tasks, task-implementation, and task-review all respect its guardrails.
|
||||
|
||||
---
|
||||
|
||||
## Phase 1: Specification
|
||||
|
||||
### 1.1 Choose Your Entry Point
|
||||
@@ -181,9 +213,9 @@ This is the bridge from functional specification to executable code:
|
||||
|
||||
**What happens:**
|
||||
1. Reads the specification and extracts requirements (assigned REQ-IDs)
|
||||
2. Loads or creates a Knowledge Graph (`knowledge-graph.json`)
|
||||
3. Explores your codebase with language-specific patterns
|
||||
4. Updates the Knowledge Graph with discoveries
|
||||
2. Generates `data-model.md` and `contracts/*` directly from the specification
|
||||
3. Optionally reuses an existing Knowledge Graph (`knowledge-graph.json`) if present
|
||||
4. Explores your codebase with language-specific patterns
|
||||
5. Decomposes requirements into atomic tasks
|
||||
6. Generates a traceability matrix
|
||||
7. Enforces task limit (≤15 implementation tasks)
|
||||
@@ -486,8 +518,12 @@ docs/specs/001-hotel-search/
|
||||
├── user-request.md # Original user input
|
||||
├── brainstorming-notes.md # Brainstorming session context
|
||||
├── decision-log.md # Decision audit trail
|
||||
├── data-model.md # Generated from specification
|
||||
├── contracts/ # Generated interface artifacts
|
||||
│ ├── hotel-search-api.openapi.yaml
|
||||
│ └── README.md
|
||||
├── traceability-matrix.md # Requirements → Tasks mapping
|
||||
├── knowledge-graph.json # Cached codebase analysis
|
||||
├── knowledge-graph.json # Optional cached codebase analysis
|
||||
├── tasks/
|
||||
│ ├── TASK-001.md # Create data models
|
||||
│ ├── TASK-001--kpi.json # Auto-generated quality KPIs
|
||||
|
||||
@@ -1,19 +1,7 @@
|
||||
{
|
||||
"description": "Developer Kit Specs hooks: Drift Guard for spec fidelity, Task Auto-Status for automatic frontmatter management, Task KPI Analyzer for quality metrics, and Session Tracking Hook for audit trail logging",
|
||||
"description": "Developer Kit Specs hooks: Drift Guard for spec fidelity, Task Auto-Status for automatic frontmatter management, and Task KPI Analyzer for quality metrics; stop hooks temporarily disabled",
|
||||
"hooks": {
|
||||
"Stop": [
|
||||
{
|
||||
"hooks": [
|
||||
{
|
||||
"type": "agent",
|
||||
"prompt": "You are the session-tracking-agent. Your job is to generate or update a session tracking entry in tracking_log.md at the project root.\n\nStop event payload:\n$ARGUMENTS\n\nProcess:\n1. Parse the event payload to extract session_id, transcript_path, cwd, and last_assistant_message.\n2. If stop_hook_active is true, exit immediately to prevent re-entrant activation.\n3. Read only the LAST 100 lines of the transcript JSONL file (transcript_path).\n4. Derive the change rationale from conversational context — explain WHY changes were made, not just WHAT changed.\n5. Get the current git branch using Bash(git:*).\n6. Use the first 8 characters of session_id as SHORT_ID (idempotency key).\n7. If an entry with this SHORT_ID already exists in tracking_log.md, UPDATE it. Otherwise, ADD a new entry at the TOP of the file.\n8. If no meaningful file changes occurred in this response, do NOT write anything.\n9. NEVER include credentials, API keys, tokens, or passwords in the log.\n\nEntry format:\n## YYYY-MM-DD — Session SHORT_ID\n**Branch:** branch-name\n**Orario:** HH:MM\n\n### Task eseguiti\n- description\n\n### File modificati\n- path/to/file (creato | modificato | eliminato)\n\n### Rationale\nWhy the changes were made.\n\n### Commit (only if commits were made)\n- short-hash message",
|
||||
"model": "sonnet",
|
||||
"async": true,
|
||||
"timeout": 60
|
||||
}
|
||||
]
|
||||
}
|
||||
],
|
||||
"Stop": [],
|
||||
"UserPromptSubmit": [
|
||||
{
|
||||
"hooks": [
|
||||
|
||||
@@ -0,0 +1,16 @@
|
||||
#!/usr/bin/env python3
|
||||
import subprocess, sys
|
||||
|
||||
def get_current_branch():
|
||||
try:
|
||||
output = subprocess.check_output(['git', 'branch', '--show-current'], stderr=subprocess.STDOUT)
|
||||
branch = output.decode().strip()
|
||||
if not branch:
|
||||
return "detached HEAD"
|
||||
return branch
|
||||
except subprocess.CalledProcessError as e:
|
||||
sys.stderr.write("Error retrieving branch: " + e.output.decode() + "\n")
|
||||
sys.exit(1)
|
||||
|
||||
if __name__ == "__main__":
|
||||
print(get_current_branch())
|
||||
@@ -0,0 +1,60 @@
|
||||
#!/usr/bin/env python3
|
||||
"""
|
||||
Find the spec folder matching the current git branch.
|
||||
|
||||
Convention: spec folders are named <id>-<branch> or match the branch name directly.
|
||||
Example: branch "develop" → finds "docs/specs/xxx-develop/" or "docs/specs/develop/"
|
||||
"""
|
||||
import subprocess
|
||||
import sys
|
||||
import os
|
||||
from pathlib import Path
|
||||
|
||||
def get_current_branch():
|
||||
try:
|
||||
output = subprocess.check_output(['git', 'branch', '--show-current'], stderr=subprocess.STDOUT)
|
||||
branch = output.decode().strip()
|
||||
if not branch:
|
||||
return None, "detached HEAD"
|
||||
return branch, None
|
||||
except subprocess.CalledProcessError as e:
|
||||
return None, e.output.decode()
|
||||
|
||||
def find_spec_folder(branch):
|
||||
specs_dir = Path("docs/specs")
|
||||
if not specs_dir.exists():
|
||||
return None, f"docs/specs/ does not exist"
|
||||
|
||||
# Try exact match first: docs/specs/<branch>/
|
||||
exact = specs_dir / branch
|
||||
if exact.is_dir():
|
||||
return str(exact), None
|
||||
|
||||
# Try pattern <id>-<branch>/
|
||||
for d in specs_dir.iterdir():
|
||||
if d.is_dir() and d.name.endswith(f"-{branch}"):
|
||||
return str(d), None
|
||||
if d.is_dir() and d.name == branch:
|
||||
return str(d), None
|
||||
|
||||
return None, f"No spec folder found for branch '{branch}'"
|
||||
|
||||
def main():
|
||||
branch, error = get_current_branch()
|
||||
if error:
|
||||
sys.stderr.write(f"Error: {error}\n")
|
||||
sys.exit(1)
|
||||
|
||||
if len(sys.argv) > 1 and sys.argv[1] == "--branch-only":
|
||||
print(branch)
|
||||
return
|
||||
|
||||
spec_folder, find_error = find_spec_folder(branch)
|
||||
if find_error:
|
||||
sys.stderr.write(f"Warning: {find_error}\n")
|
||||
sys.exit(1)
|
||||
|
||||
print(spec_folder)
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,199 @@
|
||||
"""
|
||||
ralph-loop-v2 — Job Tracker
|
||||
|
||||
Wraps business logic with automatic job-file lifecycle management.
|
||||
Job files live at: <workspace_root>/.jobs/<job_id>.json
|
||||
|
||||
Lifecycle: queued → running → completed | failed
|
||||
|
||||
The update(phase, progress) callback lets business logic report
|
||||
progress without knowing anything about the file format.
|
||||
"""
|
||||
|
||||
import json
|
||||
import os
|
||||
import signal
|
||||
from datetime import datetime, timezone
|
||||
from pathlib import Path
|
||||
from typing import Any, Callable, Optional
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Helpers
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
def _job_path(workspace_root: str, job_id: str) -> Path:
|
||||
return Path(workspace_root) / ".jobs" / f"{job_id}.json"
|
||||
|
||||
|
||||
def _write(path: Path, data: dict) -> None:
|
||||
path.parent.mkdir(parents=True, exist_ok=True)
|
||||
path.write_text(json.dumps(data, indent=2) + "\n", encoding="utf-8")
|
||||
|
||||
|
||||
def _read(path: Path) -> dict:
|
||||
return json.loads(path.read_text(encoding="utf-8"))
|
||||
|
||||
|
||||
def _now() -> str:
|
||||
return datetime.now(timezone.utc).isoformat()
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Public API
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
def run_tracked_job(
|
||||
job_id: str,
|
||||
workspace_root: str,
|
||||
meta: dict,
|
||||
business_logic: Callable[[Callable[[str, int], None]], Any],
|
||||
) -> Any:
|
||||
"""
|
||||
Run a tracked job.
|
||||
|
||||
Args:
|
||||
job_id: Unique job identifier.
|
||||
workspace_root: Project root; job file stored under .jobs/.
|
||||
meta: Extra fields merged into the job file (spec_folder, task_range, …).
|
||||
business_logic: Callable(update) → result.
|
||||
update(phase: str, progress: int) persists progress.
|
||||
|
||||
Returns:
|
||||
The value returned by business_logic.
|
||||
"""
|
||||
file_path = _job_path(workspace_root, job_id)
|
||||
|
||||
# 1. Mark as running
|
||||
job = {
|
||||
"id": job_id,
|
||||
"status": "running",
|
||||
"pid": os.getpid(),
|
||||
"createdAt": meta.get("createdAt", _now()),
|
||||
"startedAt": _now(),
|
||||
"completedAt": None,
|
||||
"phase": "starting",
|
||||
"progress": 0,
|
||||
"errorMessage": None,
|
||||
**{k: v for k, v in meta.items() if k != "createdAt"},
|
||||
}
|
||||
_write(file_path, job)
|
||||
|
||||
# 2. Progress callback
|
||||
def update(phase: str, progress: int) -> None:
|
||||
job["phase"] = phase
|
||||
job["progress"] = progress
|
||||
_write(file_path, job)
|
||||
|
||||
try:
|
||||
result = business_logic(update)
|
||||
|
||||
# 3. Success
|
||||
job.update(status="completed", pid=None,
|
||||
completedAt=_now(), progress=100, result=result)
|
||||
_write(file_path, job)
|
||||
return result
|
||||
|
||||
except Exception as exc:
|
||||
# 4. Failure — clear PID so status can detect zombie jobs
|
||||
job.update(status="failed", pid=None, errorMessage=str(exc))
|
||||
_write(file_path, job)
|
||||
raise
|
||||
|
||||
|
||||
def queue_job(job_id: str, workspace_root: str, meta: dict | None = None) -> str:
|
||||
"""
|
||||
Write an initial 'queued' job file before the process starts.
|
||||
Returns the path to the job file.
|
||||
"""
|
||||
file_path = _job_path(workspace_root, job_id)
|
||||
job = {
|
||||
"id": job_id,
|
||||
"status": "queued",
|
||||
"pid": None,
|
||||
"createdAt": _now(),
|
||||
"startedAt": None,
|
||||
"completedAt": None,
|
||||
"phase": "queued",
|
||||
"progress": 0,
|
||||
"errorMessage": None,
|
||||
**(meta or {}),
|
||||
}
|
||||
_write(file_path, job)
|
||||
return str(file_path)
|
||||
|
||||
|
||||
def read_job(job_id: str, workspace_root: str) -> Optional[dict]:
|
||||
"""Read a job file. Returns None if not found."""
|
||||
file_path = _job_path(workspace_root, job_id)
|
||||
if not file_path.exists():
|
||||
return None
|
||||
return _read(file_path)
|
||||
|
||||
|
||||
def list_jobs(workspace_root: str) -> list[dict]:
|
||||
"""
|
||||
List all job files under <workspace_root>/.jobs/.
|
||||
Returns parsed job objects sorted by createdAt descending.
|
||||
"""
|
||||
jobs_dir = Path(workspace_root) / ".jobs"
|
||||
if not jobs_dir.exists():
|
||||
return []
|
||||
|
||||
jobs = []
|
||||
for f in jobs_dir.glob("*.json"):
|
||||
try:
|
||||
jobs.append(_read(f))
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
return sorted(jobs, key=lambda j: j.get("createdAt", ""), reverse=True)
|
||||
|
||||
|
||||
def reap_zombies(workspace_root: str) -> list[str]:
|
||||
"""
|
||||
Detect zombie jobs (status=running but PID no longer alive).
|
||||
Marks them as failed and returns the list of affected job IDs.
|
||||
"""
|
||||
reaped = []
|
||||
for job in list_jobs(workspace_root):
|
||||
if job.get("status") != "running" or not job.get("pid"):
|
||||
continue
|
||||
|
||||
alive = False
|
||||
try:
|
||||
os.kill(job["pid"], 0) # signal 0 = existence check
|
||||
alive = True
|
||||
except (ProcessLookupError, PermissionError):
|
||||
pass
|
||||
|
||||
if not alive:
|
||||
job.update(
|
||||
status="failed",
|
||||
pid=None,
|
||||
errorMessage=f"Process {job['pid']} no longer running (zombie detected)",
|
||||
)
|
||||
_write(_job_path(workspace_root, job["id"]), job)
|
||||
reaped.append(job["id"])
|
||||
|
||||
return reaped
|
||||
|
||||
|
||||
def cancel_job(job_id: str, workspace_root: str) -> bool:
|
||||
"""
|
||||
Cancel a running job by sending SIGTERM to its PID.
|
||||
Updates the job file to status=failed.
|
||||
Returns True if the signal was sent, False if job not found / not running.
|
||||
"""
|
||||
job = read_job(job_id, workspace_root)
|
||||
if not job or job.get("status") != "running" or not job.get("pid"):
|
||||
return False
|
||||
|
||||
try:
|
||||
os.kill(job["pid"], signal.SIGTERM)
|
||||
except (ProcessLookupError, PermissionError):
|
||||
pass # process may have already exited
|
||||
|
||||
job.update(status="failed", pid=None, errorMessage="Cancelled by user")
|
||||
_write(_job_path(workspace_root, job_id), job)
|
||||
return True
|
||||
@@ -0,0 +1,234 @@
|
||||
#!/usr/bin/env python3
|
||||
"""
|
||||
ralph-loop-v2 — Main Orchestrator
|
||||
|
||||
Wraps the ralph-loop state machine inside a tracked job so every run
|
||||
is observable via status/cancel commands.
|
||||
|
||||
Usage:
|
||||
python3 scripts/main.py start --spec=docs/specs/001/ [--from-task=TASK-001] [--to-task=TASK-010] [--agent=claude]
|
||||
python3 scripts/main.py loop --spec=docs/specs/001/
|
||||
python3 scripts/main.py next --spec=docs/specs/001/
|
||||
python3 scripts/main.py status [--job-id=<id>]
|
||||
python3 scripts/main.py cancel --job-id=<id>
|
||||
"""
|
||||
|
||||
import argparse
|
||||
import os
|
||||
import sys
|
||||
import time
|
||||
from pathlib import Path
|
||||
|
||||
# Allow running from any directory
|
||||
_HERE = Path(__file__).resolve().parent
|
||||
sys.path.insert(0, str(_HERE.parent / "lib"))
|
||||
|
||||
from tracker import (
|
||||
cancel_job, list_jobs, queue_job, read_job, reap_zombies, run_tracked_job,
|
||||
)
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Re-use the v1 state-machine logic from ralph_loop.py
|
||||
# ---------------------------------------------------------------------------
|
||||
_RALPH_V1 = _HERE.parent.parent / "ralph-loop" / "scripts" / "ralph_loop.py"
|
||||
|
||||
def _load_v1():
|
||||
"""Dynamically import the v1 ralph_loop module."""
|
||||
import importlib.util
|
||||
spec = importlib.util.spec_from_file_location("ralph_loop", _RALPH_V1)
|
||||
mod = importlib.util.module_from_spec(spec)
|
||||
spec.loader.exec_module(mod)
|
||||
return mod
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Commands
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
def cmd_start(args):
|
||||
"""Queue a new job and immediately start it (foreground or background)."""
|
||||
workspace = os.getcwd()
|
||||
job_id = f"job_{int(time.time() * 1000)}"
|
||||
|
||||
meta = {
|
||||
"specFolder": args.spec,
|
||||
"taskRange": {"from": args.from_task, "to": args.to_task},
|
||||
"defaultAgent": args.agent,
|
||||
}
|
||||
|
||||
if args.background:
|
||||
# Write queued state, then spawn detached child
|
||||
job_file = queue_job(job_id, workspace, meta)
|
||||
_spawn_background(job_id, args)
|
||||
print(f"Job queued in background.")
|
||||
print(f" ID : {job_id}")
|
||||
print(f" File : {job_file}")
|
||||
print(f" Use : python3 main.py status --job-id={job_id}")
|
||||
else:
|
||||
# Run inline (foreground)
|
||||
rl = _load_v1()
|
||||
rl.action_start(args.spec, args.from_task, args.to_task, args.agent)
|
||||
print(f"\nJob ID: {job_id} (no background tracking for foreground start)")
|
||||
|
||||
|
||||
def cmd_loop(args):
|
||||
"""Execute one state-machine step, tracked in a job file."""
|
||||
workspace = os.getcwd()
|
||||
job_id = f"job_{int(time.time() * 1000)}"
|
||||
rl = _load_v1()
|
||||
|
||||
meta = {"specFolder": args.spec}
|
||||
|
||||
def logic(update):
|
||||
step = rl.load_fix_plan(args.spec)["state"]["step"]
|
||||
update(f"step:{step}", 0)
|
||||
rl.action_loop(args.spec, args.agent, args.no_commit)
|
||||
new_step = rl.load_fix_plan(args.spec)["state"]["step"]
|
||||
update(f"step:{new_step}", 50)
|
||||
return {"step": new_step}
|
||||
|
||||
run_tracked_job(job_id, workspace, meta, logic)
|
||||
|
||||
|
||||
def cmd_next(args):
|
||||
"""Advance the state machine to the next step."""
|
||||
rl = _load_v1()
|
||||
rl.action_next(args.spec, args.agent, args.no_commit)
|
||||
|
||||
|
||||
def cmd_status(args):
|
||||
"""Show job status. If --job-id given, show that job; otherwise list recent jobs."""
|
||||
workspace = os.getcwd()
|
||||
reap_zombies(workspace)
|
||||
|
||||
if args.job_id:
|
||||
job = read_job(args.job_id, workspace)
|
||||
if not job:
|
||||
print(f"Job not found: {args.job_id}")
|
||||
sys.exit(1)
|
||||
_print_job(job)
|
||||
else:
|
||||
jobs = list_jobs(workspace)
|
||||
if not jobs:
|
||||
print("No jobs found.")
|
||||
return
|
||||
for job in jobs[:10]:
|
||||
_print_job(job, compact=True)
|
||||
|
||||
|
||||
def cmd_cancel(args):
|
||||
"""Cancel a running job."""
|
||||
workspace = os.getcwd()
|
||||
if cancel_job(args.job_id, workspace):
|
||||
print(f"✅ Job {args.job_id} cancelled.")
|
||||
else:
|
||||
job = read_job(args.job_id, workspace)
|
||||
if not job:
|
||||
print(f"❌ Job not found: {args.job_id}")
|
||||
else:
|
||||
print(f"⚠️ Job {args.job_id} is not running (status: {job['status']})")
|
||||
sys.exit(1)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Helpers
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
def _print_job(job: dict, compact: bool = False) -> None:
|
||||
status_icon = {"queued": "⏳", "running": "🔄", "completed": "✅", "failed": "❌"}.get(
|
||||
job.get("status", ""), "❓"
|
||||
)
|
||||
if compact:
|
||||
print(f"{status_icon} {job['id']} [{job.get('status')}] phase={job.get('phase')} progress={job.get('progress', 0)}%")
|
||||
return
|
||||
|
||||
print("─" * 56)
|
||||
print(f"ID : {job['id']}")
|
||||
print(f"Status : {status_icon} {job.get('status')}")
|
||||
print(f"Phase : {job.get('phase')}")
|
||||
print(f"Progress : {job.get('progress', 0)}%")
|
||||
print(f"PID : {job.get('pid')}")
|
||||
print(f"Created : {job.get('createdAt')}")
|
||||
print(f"Started : {job.get('startedAt')}")
|
||||
print(f"Completed: {job.get('completedAt')}")
|
||||
if job.get("errorMessage"):
|
||||
print(f"Error : {job['errorMessage']}")
|
||||
if job.get("result"):
|
||||
print(f"Result : {job['result']}")
|
||||
print("─" * 56)
|
||||
|
||||
|
||||
def _spawn_background(job_id: str, args) -> None:
|
||||
"""Spawn a detached child process that runs the loop."""
|
||||
import subprocess
|
||||
cmd = [
|
||||
sys.executable, __file__, "loop",
|
||||
f"--spec={args.spec}",
|
||||
f"--agent={args.agent}",
|
||||
]
|
||||
if args.no_commit:
|
||||
cmd.append("--no-commit")
|
||||
|
||||
# Detach from parent (double-fork not needed on macOS/Linux with start_new_session)
|
||||
subprocess.Popen(
|
||||
cmd,
|
||||
start_new_session=True,
|
||||
stdout=subprocess.DEVNULL,
|
||||
stderr=subprocess.DEVNULL,
|
||||
)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# CLI
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
def build_parser() -> argparse.ArgumentParser:
|
||||
p = argparse.ArgumentParser(description="ralph-loop-v2 orchestrator")
|
||||
sub = p.add_subparsers(dest="command", required=True)
|
||||
|
||||
# start
|
||||
s = sub.add_parser("start", help="Initialize and optionally start a job")
|
||||
s.add_argument("--spec", required=True)
|
||||
s.add_argument("--from-task", default=None, dest="from_task")
|
||||
s.add_argument("--to-task", default=None, dest="to_task")
|
||||
s.add_argument("--agent", default="claude")
|
||||
s.add_argument("--background", action="store_true", help="Run in background")
|
||||
s.add_argument("--no-commit", action="store_true", dest="no_commit")
|
||||
|
||||
# loop
|
||||
lo = sub.add_parser("loop", help="Execute one state-machine step")
|
||||
lo.add_argument("--spec", required=True)
|
||||
lo.add_argument("--agent", default=None)
|
||||
lo.add_argument("--no-commit", action="store_true", dest="no_commit")
|
||||
|
||||
# next
|
||||
nx = sub.add_parser("next", help="Advance to next step")
|
||||
nx.add_argument("--spec", required=True)
|
||||
nx.add_argument("--agent", default=None)
|
||||
nx.add_argument("--no-commit", action="store_true", dest="no_commit")
|
||||
|
||||
# status
|
||||
st = sub.add_parser("status", help="Show job status")
|
||||
st.add_argument("--job-id", default=None, dest="job_id")
|
||||
|
||||
# cancel
|
||||
ca = sub.add_parser("cancel", help="Cancel a running job")
|
||||
ca.add_argument("--job-id", required=True, dest="job_id")
|
||||
|
||||
return p
|
||||
|
||||
|
||||
def main():
|
||||
args = build_parser().parse_args()
|
||||
dispatch = {
|
||||
"start": cmd_start,
|
||||
"loop": cmd_loop,
|
||||
"next": cmd_next,
|
||||
"status": cmd_status,
|
||||
"cancel": cmd_cancel,
|
||||
}
|
||||
dispatch[args.command](args)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,92 @@
|
||||
{
|
||||
"$schema": "http://json-schema.org/draft-07/schema#",
|
||||
"title": "RalphLoopJob",
|
||||
"description": "State file for a ralph-loop-v2 job",
|
||||
"type": "object",
|
||||
"required": ["id", "status", "createdAt", "specFolder", "state"],
|
||||
"properties": {
|
||||
"id": {
|
||||
"type": "string",
|
||||
"description": "Unique job identifier (e.g. job_1713261568000)"
|
||||
},
|
||||
"status": {
|
||||
"type": "string",
|
||||
"enum": ["queued", "running", "completed", "failed"],
|
||||
"description": "Top-level lifecycle status"
|
||||
},
|
||||
"pid": {
|
||||
"type": ["integer", "null"],
|
||||
"description": "OS process ID while running; null when idle or finished"
|
||||
},
|
||||
"createdAt": {
|
||||
"type": "string",
|
||||
"format": "date-time"
|
||||
},
|
||||
"startedAt": {
|
||||
"type": ["string", "null"],
|
||||
"format": "date-time"
|
||||
},
|
||||
"completedAt": {
|
||||
"type": ["string", "null"],
|
||||
"format": "date-time"
|
||||
},
|
||||
"phase": {
|
||||
"type": "string",
|
||||
"description": "Current state-machine step (e.g. choose_task, implementation, review…)"
|
||||
},
|
||||
"progress": {
|
||||
"type": "number",
|
||||
"minimum": 0,
|
||||
"maximum": 100,
|
||||
"description": "Overall completion percentage"
|
||||
},
|
||||
"specFolder": {
|
||||
"type": "string",
|
||||
"description": "Path to the spec folder being processed"
|
||||
},
|
||||
"taskRange": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"from": { "type": ["string", "null"] },
|
||||
"to": { "type": ["string", "null"] }
|
||||
}
|
||||
},
|
||||
"defaultAgent": {
|
||||
"type": "string",
|
||||
"description": "Default CLI agent (claude, codex, copilot, …)"
|
||||
},
|
||||
"state": {
|
||||
"type": "object",
|
||||
"description": "Full state-machine payload (mirrors fix_plan.json state block)",
|
||||
"required": ["step", "iteration"],
|
||||
"properties": {
|
||||
"step": {
|
||||
"type": "string",
|
||||
"enum": [
|
||||
"init", "choose_task", "implementation", "review",
|
||||
"fix", "cleanup", "sync", "update_done", "complete", "failed"
|
||||
]
|
||||
},
|
||||
"currentTask": { "type": ["string", "null"] },
|
||||
"currentTaskFile": { "type": ["string", "null"] },
|
||||
"currentTaskLang": { "type": ["string", "null"] },
|
||||
"iteration": { "type": "integer", "minimum": 0 },
|
||||
"retryCount": { "type": "integer", "minimum": 0 },
|
||||
"lastUpdated": { "type": "string", "format": "date-time" },
|
||||
"error": { "type": ["string", "null"] },
|
||||
"rangeProgress": {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"doneInRange": { "type": "integer" },
|
||||
"totalInRange": { "type": "integer" }
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
"tasks": { "type": "array" },
|
||||
"pending": { "type": "array", "items": { "type": "string" } },
|
||||
"done": { "type": "array", "items": { "type": "string" } },
|
||||
"result": { "description": "Final result payload on completion" },
|
||||
"errorMessage": { "type": ["string", "null"] }
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,312 @@
|
||||
---
|
||||
name: constitution
|
||||
description: "Creates, updates, validates, and displays the architectural DNA of a project through two shared documents: docs/specs/architecture.md (technology stack, architectural rules, security constraints, AI guardrails) and docs/specs/ontology.md (domain glossary / Ubiquitous Language). Use BEFORE brainstorm as a project setup step, or at any point in the SDD lifecycle to validate specs/tasks against architecture principles. Triggers on 'create constitution', 'update constitution', 'constitution check', 'validate against constitution', 'project principles', 'architectural guardrails', 'setup project architecture', 'define ontology'."
|
||||
allowed-tools: Read, Write, Edit, Grep, Glob, Bash, AskUserQuestion, TodoWrite
|
||||
---
|
||||
|
||||
## Instructions
|
||||
|
||||
1. Identify the operation from `$ARGUMENTS` or user intent: `create`, `update`, `check`, or `show`.
|
||||
2. For **create**: ask which files to create (architecture.md, ontology.md, or both), gather required information via `AskUserQuestion`, then write the files using the templates below.
|
||||
3. For **update**: identify the target file and section, apply the change surgically, update the `Last Updated` date.
|
||||
4. For **check**: read both constitution files, read the target file, validate against architectural rules and ontology terms, output a Constitution Check Report.
|
||||
5. For **show**: read and display both files formatted for readability.
|
||||
6. Always confirm with the user before writing or overwriting files.
|
||||
|
||||
## Examples
|
||||
|
||||
**Create constitution before first brainstorm:**
|
||||
```
|
||||
/developer-kit-specs:constitution create
|
||||
```
|
||||
|
||||
**Validate a spec against architecture and ontology:**
|
||||
```
|
||||
/developer-kit-specs:constitution check --target=docs/specs/001/2024-01-15--user-auth.md
|
||||
```
|
||||
|
||||
**Update the security constraints section:**
|
||||
```
|
||||
/developer-kit-specs:constitution update --file=architecture --section=security
|
||||
```
|
||||
|
||||
**Show current constitution:**
|
||||
```
|
||||
/developer-kit-specs:constitution show
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
# Constitution Skill
|
||||
|
||||
## Overview
|
||||
|
||||
The **Constitution** is the architectural DNA of a project, expressed through two shared documents:
|
||||
|
||||
| File | Purpose |
|
||||
|------|---------|
|
||||
| `docs/specs/architecture.md` | Technology stack, infrastructure choices, architectural rules, security constraints, AI guardrails |
|
||||
| `docs/specs/ontology.md` | Domain glossary (Ubiquitous Language) — terms, definitions, bounded contexts |
|
||||
|
||||
These files live at the `docs/specs/` level and are **shared across all specifications**.
|
||||
|
||||
**Key difference from the old constitution.md approach**: instead of a single monolithic file, the constitution is split into two focused documents that are also created and enriched by `brainstorm` (Phase 6.8.6) and `spec-to-tasks` (Phase 1.5). This skill lets you create or manage them **before brainstorm**, as a project setup step.
|
||||
|
||||
## When to Use
|
||||
|
||||
| Scenario | Operation |
|
||||
|----------|-----------|
|
||||
| New project — define stack and domain language before first brainstorm | `create` |
|
||||
| Stack or security rules changed | `update` |
|
||||
| Validate a spec, task, or file against architecture and ontology | `check` |
|
||||
| Review current architecture and ontology | `show` |
|
||||
|
||||
**Trigger phrases:**
|
||||
- "Create constitution", "Setup project architecture", "Define ontology"
|
||||
- "Update constitution", "Update architecture", "Update ontology"
|
||||
- "Constitution check", "Validate against constitution"
|
||||
- "Show constitution", "Project principles", "Architectural guardrails"
|
||||
|
||||
## Available Operations
|
||||
|
||||
**1. create** — Create one or both files interactively
|
||||
**2. update** — Update a specific section of one file
|
||||
**3. check** — Validate a spec/task/file against both documents
|
||||
**4. show** — Display the current state of both documents
|
||||
|
||||
---
|
||||
|
||||
## Operation: create
|
||||
|
||||
1. Ask the user which files to create (if not specified in `$ARGUMENTS`):
|
||||
- Options: "Both architecture.md and ontology.md" (recommended), "architecture.md only", "ontology.md only"
|
||||
|
||||
2. For each file to create, check if it already exists. If yes, ask: overwrite or skip.
|
||||
|
||||
3. **For `docs/specs/architecture.md`**, gather via `AskUserQuestion`:
|
||||
|
||||
**Q1 — Software Stack**:
|
||||
- Options: "Java / Spring Boot", "TypeScript / NestJS", "TypeScript / React", "Python / Django or FastAPI", "PHP / Laravel or Symfony", or freeform
|
||||
|
||||
**Q2 — Data Architecture**:
|
||||
- Options: "PostgreSQL", "MySQL", "MongoDB", "Multiple databases", or freeform
|
||||
|
||||
**Q3 — Infrastructure**:
|
||||
- Options: "AWS", "Docker / Docker Compose", "Kubernetes", "Serverless", "Not yet decided", or freeform
|
||||
|
||||
**Q4 — Architectural Rules** (optional, freeform):
|
||||
- Forbidden patterns, required patterns, security constraints, AI guardrails
|
||||
|
||||
Then create `docs/specs/architecture.md` using the **Architecture Template** below.
|
||||
|
||||
4. **For `docs/specs/ontology.md`**, gather via `AskUserQuestion`:
|
||||
|
||||
Ask the user to list the main domain terms and their definitions. Explain:
|
||||
> "The ontology captures the Ubiquitous Language of your project. It is normally enriched during brainstorming when terms emerge from the idea. You can seed it now with known terms, or create an empty scaffold to fill later."
|
||||
|
||||
- Options: "Seed with known terms (I'll provide them)", "Create empty scaffold", "Skip for now"
|
||||
|
||||
Then create `docs/specs/ontology.md` using the **Ontology Template** below.
|
||||
|
||||
5. Confirm with the user before writing each file.
|
||||
|
||||
---
|
||||
|
||||
## Operation: update
|
||||
|
||||
1. Identify the target file and section from `$ARGUMENTS`:
|
||||
- `--file=architecture` or `--file=ontology`
|
||||
- `--section=<section-name>` (e.g., `--section=security`, `--section=glossary`)
|
||||
2. Read the target file.
|
||||
3. Apply the update surgically — do not touch other sections.
|
||||
4. Update the `Last Updated` date.
|
||||
5. Write the updated file.
|
||||
|
||||
---
|
||||
|
||||
## Operation: check
|
||||
|
||||
1. Read both `docs/specs/architecture.md` and `docs/specs/ontology.md`. If either is missing, warn the user but continue with the available file(s).
|
||||
2. Read the target file from `$ARGUMENTS` (`--target=<path>`).
|
||||
3. Check against **architecture.md**:
|
||||
- Forbidden libraries/imports present?
|
||||
- Unapproved patterns used?
|
||||
- Security constraints violated (raw SQL, hardcoded secrets, etc.)?
|
||||
- AI guardrails violated?
|
||||
4. Check against **ontology.md**:
|
||||
- Are domain terms used consistently (no synonyms for defined terms)?
|
||||
- Are new domain concepts introduced without being added to the glossary?
|
||||
5. Output a **Constitution Check Report** (see format below).
|
||||
|
||||
---
|
||||
|
||||
## Operation: show
|
||||
|
||||
1. Read `docs/specs/architecture.md` and `docs/specs/ontology.md`.
|
||||
2. Print both files formatted for readability, with a header indicating which file is which.
|
||||
|
||||
---
|
||||
|
||||
## Architecture Template
|
||||
|
||||
```markdown
|
||||
# Project Architecture
|
||||
|
||||
**Created**: YYYY-MM-DD
|
||||
**Last Updated**: YYYY-MM-DD
|
||||
|
||||
## Software Stack
|
||||
|
||||
| Component | Technology | Notes |
|
||||
|-----------|-----------|-------|
|
||||
| Language | [e.g., TypeScript] | [version if known] |
|
||||
| Framework | [e.g., NestJS] | [version if known] |
|
||||
| Key Libraries | [e.g., Drizzle ORM, Passport] | |
|
||||
|
||||
## Data Architecture
|
||||
|
||||
| Component | Technology | Notes |
|
||||
|-----------|-----------|-------|
|
||||
| Primary Database | [e.g., PostgreSQL] | |
|
||||
| Caching | [e.g., Redis, none] | |
|
||||
| ORM / Data Access | [e.g., Drizzle, Hibernate] | |
|
||||
| Migrations | [e.g., Flyway, Drizzle Kit] | |
|
||||
|
||||
## Infrastructure
|
||||
|
||||
| Component | Technology | Notes |
|
||||
|-----------|-----------|-------|
|
||||
| Hosting | [e.g., AWS ECS] | |
|
||||
| CI/CD | [e.g., GitHub Actions] | |
|
||||
| Containerization | [e.g., Docker] | |
|
||||
| Orchestration | [e.g., Kubernetes, none] | |
|
||||
|
||||
## Architectural Rules
|
||||
|
||||
- [Rule 1, e.g., "Use constructor injection. Never use @Autowired on fields."]
|
||||
- [Rule 2, e.g., "Domain entities must not depend on framework annotations."]
|
||||
|
||||
## Security Constraints
|
||||
|
||||
- Forbidden patterns:
|
||||
- No raw SQL string concatenation (SQL injection — CWE-89)
|
||||
- No hardcoded secrets or credentials (CWE-798)
|
||||
- No deserialization of untrusted data (CWE-502)
|
||||
- Required patterns:
|
||||
- [e.g., All inputs validated with Bean Validation]
|
||||
- [e.g., All secrets via environment variables or Secrets Manager]
|
||||
|
||||
## AI Guardrails
|
||||
|
||||
Rules that AI agents MUST follow when generating code for this project:
|
||||
|
||||
- [Guardrail 1, e.g., "Never generate @Transactional on repository methods."]
|
||||
- [Guardrail 2, e.g., "Always generate tests alongside implementation code."]
|
||||
- [Guardrail 3, e.g., "Do not introduce new dependencies without explicit approval."]
|
||||
|
||||
## Architecture Decisions
|
||||
|
||||
> Significant modifications to this architecture document must be tracked
|
||||
> via **ADR (Architecture Decision Records)** using the `adr-drafting` skill.
|
||||
>
|
||||
> ADR location: `docs/architecture/adr/`
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Ontology Template
|
||||
|
||||
```markdown
|
||||
# Project Ontology — Ubiquitous Language
|
||||
|
||||
**Created**: YYYY-MM-DD
|
||||
**Last Updated**: YYYY-MM-DD
|
||||
|
||||
## Domain Glossary
|
||||
|
||||
| Term | Definition | Bounded Context |
|
||||
|------|-----------|-----------------|
|
||||
| [Term 1] | [Definition] | [Context where this term applies] |
|
||||
| [Term 2] | [Definition] | [Context where this term applies] |
|
||||
|
||||
## Bounded Contexts
|
||||
|
||||
| Context | Description | Key Terms |
|
||||
|---------|-------------|-----------|
|
||||
| [Context 1] | [Description] | [Key terms] |
|
||||
|
||||
## Conceptual Mapping
|
||||
|
||||
[Relationships between key domain entities — to be refined during brainstorming and task generation]
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Constitution Check Report Format
|
||||
|
||||
```
|
||||
## Constitution Check Report
|
||||
Target: <file or spec path>
|
||||
Date: YYYY-MM-DD
|
||||
|
||||
### Architecture Check
|
||||
|
||||
| Rule | Status | Detail |
|
||||
|------|--------|--------|
|
||||
| Constructor injection required | ✅ OK | No field injection found |
|
||||
| No hardcoded secrets | ❌ CRITICAL | Line 42: hardcoded password string |
|
||||
| JWT authentication | ⚠️ WARNING | Missing @PreAuthorize on endpoint |
|
||||
|
||||
### Ontology Check
|
||||
|
||||
| Term | Status | Detail |
|
||||
|------|--------|--------|
|
||||
| "Reservation" used consistently | ✅ OK | No synonym "Booking" found |
|
||||
| New term "Voucher" introduced | ⚠️ WARNING | Not defined in ontology.md |
|
||||
|
||||
### Summary
|
||||
- CRITICAL violations: 1 (must fix before proceeding)
|
||||
- WARNING violations: 2 (should fix)
|
||||
- Compliant rules: 2
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Relationship with brainstorm and spec-to-tasks
|
||||
|
||||
This skill is the **pre-brainstorm setup** entry point. The same files are also created/enriched by:
|
||||
|
||||
| Command | When | What it does |
|
||||
|---------|------|-------------|
|
||||
| `constitution create` | Before brainstorm (this skill) | Creates architecture.md and/or ontology.md from scratch |
|
||||
| `brainstorm` Phase 6.8.6 | During brainstorming | Creates/enriches ontology.md with terms extracted from the idea |
|
||||
| `spec-to-tasks` Phase 1.5 | After brainstorm | Creates architecture.md if missing; enriches ontology.md with new terms from the spec |
|
||||
|
||||
**If you run `constitution create` before brainstorm**, the brainstorm and spec-to-tasks commands will detect the existing files and load them instead of creating new ones — no duplication.
|
||||
|
||||
**Note on ontology.md**: The ontology is normally most naturally created during brainstorming, because domain terms emerge from the idea description. Using `constitution create` to seed it beforehand is useful when the team already has a well-defined domain language.
|
||||
|
||||
---
|
||||
|
||||
## Integration with SDD Workflow
|
||||
|
||||
```
|
||||
[Optional] constitution create ← this skill (pre-brainstorm setup)
|
||||
↓
|
||||
brainstorm ← enriches ontology.md (Phase 6.8.6)
|
||||
↓
|
||||
spec-to-tasks ← loads/creates architecture.md, enriches ontology.md (Phase 1.5)
|
||||
↓
|
||||
task-implementation ← AI guardrails from architecture.md prevent unapproved patterns
|
||||
↓
|
||||
task-review / ralph-loop ← constitution check validates implementation
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Constraints
|
||||
|
||||
- **Does NOT modify source code** — only creates/updates `docs/specs/architecture.md` and `docs/specs/ontology.md`
|
||||
- **Constitution Check is advisory for WARNINGs** — CRITICAL violations must be resolved
|
||||
- **One architecture.md and one ontology.md per project** — shared across all specs
|
||||
- **Version the architecture** — update `Last Updated` date on every change; use ADRs for significant decisions
|
||||
@@ -0,0 +1,196 @@
|
||||
---
|
||||
name: create-pr-from-spec
|
||||
description: "Create GitHub Pull Request from specification using pull_request_template.md. Use when: spec needs to be converted to PR, spec is ready for review/merge, need to automate PR creation from specification file with template-based body and title."
|
||||
allowed-tools: Read, Grep, Glob, Bash
|
||||
---
|
||||
|
||||
# Create Pull Request from Specification
|
||||
|
||||
Create a GitHub Pull Request for a specification using the pull_request_template.md template located at `${workspaceFolder}/.github/pull_request_template.md`.
|
||||
|
||||
## Overview
|
||||
|
||||
This skill automates the creation of GitHub Pull Requests directly from specifications. It follows a structured process:
|
||||
|
||||
1. Analyzes the specification template requirements
|
||||
2. Creates a draft PR with the target branch
|
||||
3. Verifies no duplicate PRs exist
|
||||
4. Updates PR body and title with template-compliant content
|
||||
5. Marks PR as ready for review
|
||||
6. Automatically assigns to the creator
|
||||
7. Returns PR URL to user
|
||||
|
||||
**Key Benefits:**
|
||||
- ✅ Automated PR creation from specifications
|
||||
- ✅ Template-compliant PR body and title
|
||||
- ✅ Duplicate PR prevention
|
||||
- ✅ Auto-assignment to creator
|
||||
- ✅ Streamlined spec-to-PR workflow
|
||||
|
||||
## When to Use
|
||||
|
||||
Use this skill when:
|
||||
|
||||
1. **Specification is ready to merge** - Convert finalized spec to PR
|
||||
2. **Need automated PR creation** - Avoid manual PR drafting
|
||||
3. **Template compliance required** - Ensure PR follows pull_request_template.md
|
||||
4. **Multiple PRs from specs** - Batch process specifications into PRs
|
||||
5. **Team collaboration** - Share specs as PRs for review
|
||||
|
||||
**Trigger phrases:**
|
||||
- "Create pull request from spec"
|
||||
- "Convert spec to PR"
|
||||
- "Open PR for specification"
|
||||
- "Submit spec as pull request"
|
||||
- "Automate PR creation"
|
||||
|
||||
## Instructions
|
||||
|
||||
### Prerequisites
|
||||
|
||||
Before using this skill, ensure:
|
||||
- Specification file is finalized and ready for review
|
||||
- Target branch is specified (e.g., `main`, `develop`)
|
||||
- `.github/pull_request_template.md` exists in the repository
|
||||
- You have write access to create PRs
|
||||
|
||||
### Step-by-Step Process
|
||||
|
||||
**1. Analyze specification template**
|
||||
- Extract requirements from `${workspaceFolder}/.github/pull_request_template.md`
|
||||
- Use search tool to parse template sections and placeholders
|
||||
|
||||
**2. Create pull request draft**
|
||||
- Use `create_pull_request` tool to create draft PR to target branch
|
||||
- First verify no existing PR exists using `get_pull_request` to prevent duplicates
|
||||
- If PR already exists, stop and report to user
|
||||
|
||||
**3. Get pull request changes**
|
||||
- Use `get_pull_request_diff` tool to analyze differences
|
||||
- Verify code changes are correct before updating
|
||||
|
||||
**4. Update pull request**
|
||||
- Use `update_pull_request` tool to populate PR body and title
|
||||
- Incorporate template sections from step 1
|
||||
- Ensure all required fields are filled
|
||||
|
||||
**5. Mark ready for review**
|
||||
- Use `update_pull_request` tool to change state from draft to ready for review
|
||||
- Verify PR is no longer in draft mode
|
||||
|
||||
**6. Assign pull request**
|
||||
- Use `get_me` to retrieve current user information
|
||||
- Use `update_issue` tool to assign PR to creator
|
||||
|
||||
**7. Return pull request URL**
|
||||
- Provide user with clickable PR URL
|
||||
- Include summary of PR contents
|
||||
|
||||
## Examples
|
||||
|
||||
### Example 1: Basic PR Creation
|
||||
|
||||
```bash
|
||||
Input: Create PR from spec to main branch
|
||||
Process:
|
||||
1. Analyze pull_request_template.md
|
||||
2. Create draft PR to main
|
||||
3. Check for existing PRs
|
||||
4. Update PR title: "feat: [Feature Name from Spec]"
|
||||
5. Update PR body with template sections
|
||||
6. Mark as ready for review
|
||||
7. Assign to creator
|
||||
Output: https://github.com/user/repo/pull/123
|
||||
```
|
||||
|
||||
### Example 2: Template-Compliant PR
|
||||
|
||||
```markdown
|
||||
PR Title: feat: Implement user authentication system
|
||||
|
||||
PR Body:
|
||||
## Description
|
||||
Implements JWT-based authentication with token refresh mechanism
|
||||
|
||||
## Related Issue
|
||||
Closes #456
|
||||
|
||||
## Changes
|
||||
- Added JWT middleware
|
||||
- Implemented token validation
|
||||
- Added refresh token endpoint
|
||||
|
||||
## Testing
|
||||
- Unit tests for auth middleware
|
||||
- Integration tests for token endpoints
|
||||
|
||||
## Checklist
|
||||
- [x] Tests pass
|
||||
- [x] Documentation updated
|
||||
- [x] No breaking changes
|
||||
```
|
||||
|
||||
### Example 3: Duplicate Prevention
|
||||
|
||||
```bash
|
||||
Input: Create PR from spec
|
||||
Check: PR for current branch already exists?
|
||||
→ Yes: Report error, don't create duplicate
|
||||
→ No: Proceed with PR creation
|
||||
Output: "PR already exists at https://github.com/user/repo/pull/789"
|
||||
```
|
||||
|
||||
## Requirements
|
||||
|
||||
- Single pull request for the complete specification
|
||||
- Clear title and body identifying the specification/feature
|
||||
- Pull request body follows pull_request_template.md structure
|
||||
- Verification that no duplicate pull requests exist
|
||||
- PR automatically assigned to creator
|
||||
- No draft PRs left behind
|
||||
|
||||
## Success Criteria
|
||||
|
||||
- ✅ PR created without errors
|
||||
- ✅ PR body follows pull_request_template.md structure
|
||||
- ✅ PR title clearly identifies the specification/feature
|
||||
- ✅ No duplicate PRs exist for the branch
|
||||
- ✅ PR assigned to creator
|
||||
- ✅ PR URL returned to user
|
||||
- ✅ PR is ready for review (not in draft)
|
||||
|
||||
## Constraints and Warnings
|
||||
|
||||
⚠️ **Important:**
|
||||
- PR creation requires write access to repository
|
||||
- Target branch must exist before PR creation
|
||||
- Template file must exist at `.github/pull_request_template.md`
|
||||
- Cannot create PR without valid branch target
|
||||
- Duplicate PRs will be detected and rejected
|
||||
- PR assignment requires valid GitHub user
|
||||
|
||||
🚫 **Limitations:**
|
||||
- Does not perform code review automatically
|
||||
- Does not trigger CI/CD pipelines
|
||||
- Does not merge PRs automatically
|
||||
- Cannot modify existing code, only PR metadata
|
||||
|
||||
## Best Practices
|
||||
|
||||
1. **Verify before creating** - Always review specification before converting to PR
|
||||
2. **Use descriptive titles** - PR titles should clearly indicate feature/fix purpose
|
||||
3. **Complete template** - Ensure all required template sections are filled
|
||||
4. **Link related issues** - Include issue references in PR body
|
||||
5. **Test first** - Ensure all tests pass before creating PR
|
||||
6. **Team review** - Get team approval before marking ready for review
|
||||
7. **Clean git history** - Ensure commits are clean and well-documented
|
||||
|
||||
## Tools Used
|
||||
|
||||
- `search` - Analyze specification template requirements
|
||||
- `create_pull_request` - Create new PR in draft mode
|
||||
- `get_pull_request` - Check for existing PRs before creation
|
||||
- `get_pull_request_diff` - Analyze PR changes
|
||||
- `update_pull_request` - Update PR title, body, and state
|
||||
- `update_issue` - Assign PR to creator
|
||||
- `get_me` - Retrieve current user information
|
||||
@@ -3,7 +3,8 @@ name: ralph-loop
|
||||
description: "Ralph Wiggum-inspired automation loop for specification-driven development. Orchestrates task implementation, review, cleanup, and synchronization using a Python script. Use when: user runs /loop command, user asks to automate task implementation, user wants to iterate through spec tasks step-by-step, or user wants to run development workflow automation with context window management. One step per invocation. State machine: init → choose_task → implementation → review → fix → cleanup → sync → update_done. Supports --from-task and --to-task for task range filtering. State persisted in fix_plan.json."
|
||||
allowed-tools: Read, Write, Edit, Bash, Grep, Glob, TodoWrite
|
||||
---
|
||||
|
||||
> **⚠️ WARNING**: This skill was deprecated in favor of a new command `ralph-loop-v2` that uses a Python orchestrator script.
|
||||
> The old `/specs:ralph-loop` command will be removed soon. Please migrate to the new command.
|
||||
# Ralph Loop — Python Orchestrator
|
||||
|
||||
⚠️ **IMPORTANT**: This skill uses a Python orchestrator script. Do NOT execute arbitrary bash commands. Use `Bash` ONLY to run `ralph_loop.py`. All task commands (like `/developer-kit-specs:specs.task-implementation`) are shown to the user to execute manually.
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "developer-kit-tools",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"description": "External tools integration skills for CLI utilities, APIs, and third-party services",
|
||||
"author": {
|
||||
"name": "Giuseppe Trisciuoglio",
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "developer-kit-typescript",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"description": "TypeScript/JavaScript full-stack development with NestJS, React, and React Native",
|
||||
"author": {
|
||||
"name": "Giuseppe Trisciuoglio",
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
{
|
||||
"description": "TypeScript Developer Kit hooks — enforce naming conventions, architectural patterns, quality gates, and session context for TypeScript/NestJS/Nx projects",
|
||||
"description": "TypeScript Developer Kit hooks — run only in TypeScript projects and enforce naming conventions, architectural patterns, and session context; stop hooks temporarily disabled",
|
||||
"hooks": {
|
||||
"SessionStart": [
|
||||
{
|
||||
@@ -69,16 +69,6 @@
|
||||
]
|
||||
}
|
||||
],
|
||||
"Stop": [
|
||||
{
|
||||
"hooks": [
|
||||
{
|
||||
"type": "command",
|
||||
"command": "python3 ${CLAUDE_PLUGIN_ROOT}/hooks/ts-quality-gate.py",
|
||||
"statusMessage": "Running TypeScript quality checks (tsc + eslint)..."
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
"Stop": []
|
||||
}
|
||||
}
|
||||
|
||||
@@ -0,0 +1,84 @@
|
||||
#!/usr/bin/env python3
|
||||
"""Tests for ts-quality-gate.py."""
|
||||
|
||||
import importlib.util
|
||||
import os
|
||||
import sys
|
||||
from pathlib import Path
|
||||
from subprocess import CompletedProcess
|
||||
from unittest.mock import patch
|
||||
|
||||
|
||||
hooks_dir = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
|
||||
sys.path.insert(0, hooks_dir)
|
||||
|
||||
spec = importlib.util.spec_from_file_location(
|
||||
"ts_quality_gate", os.path.join(hooks_dir, "ts-quality-gate.py")
|
||||
)
|
||||
ts_quality_gate = importlib.util.module_from_spec(spec)
|
||||
sys.modules["ts_quality_gate"] = ts_quality_gate
|
||||
spec.loader.exec_module(ts_quality_gate)
|
||||
|
||||
|
||||
def test_run_eslint_falls_back_when_compact_formatter_is_missing():
|
||||
cwd = Path("/tmp/project")
|
||||
files = ["src/example.ts"]
|
||||
compact_failure = CompletedProcess(
|
||||
args=[],
|
||||
returncode=2,
|
||||
stdout="",
|
||||
stderr=(
|
||||
"The compact formatter is no longer part of core ESLint. "
|
||||
"Install it manually with `npm install -D eslint-formatter-compact`"
|
||||
),
|
||||
)
|
||||
lint_failure = CompletedProcess(
|
||||
args=[],
|
||||
returncode=1,
|
||||
stdout="src/example.ts\n 1:1 error Unexpected any @typescript-eslint/no-explicit-any\n",
|
||||
stderr="",
|
||||
)
|
||||
|
||||
with (
|
||||
patch.object(ts_quality_gate, "_find_eslint_config", return_value=cwd / "eslint.config.js"),
|
||||
patch.object(ts_quality_gate.shutil, "which", return_value="/usr/bin/npx"),
|
||||
patch.object(ts_quality_gate.subprocess, "run", side_effect=[compact_failure, lint_failure]) as run_mock,
|
||||
):
|
||||
has_errors, output = ts_quality_gate._run_eslint(cwd, files)
|
||||
|
||||
assert has_errors is True
|
||||
assert "Unexpected any" in output
|
||||
assert run_mock.call_count == 2
|
||||
assert run_mock.call_args_list[0].args[0] == [
|
||||
"npx",
|
||||
"eslint",
|
||||
"--format",
|
||||
"compact",
|
||||
*files,
|
||||
]
|
||||
assert run_mock.call_args_list[1].args[0] == ["npx", "eslint", *files]
|
||||
|
||||
|
||||
def test_run_eslint_passes_when_fallback_run_succeeds():
|
||||
cwd = Path("/tmp/project")
|
||||
files = ["src/example.ts"]
|
||||
compact_failure = CompletedProcess(
|
||||
args=[],
|
||||
returncode=2,
|
||||
stdout="",
|
||||
stderr=(
|
||||
"The compact formatter is no longer part of core ESLint. "
|
||||
"Install it manually with `npm install -D eslint-formatter-compact`"
|
||||
),
|
||||
)
|
||||
lint_success = CompletedProcess(args=[], returncode=0, stdout="", stderr="")
|
||||
|
||||
with (
|
||||
patch.object(ts_quality_gate, "_find_eslint_config", return_value=cwd / "eslint.config.js"),
|
||||
patch.object(ts_quality_gate.shutil, "which", return_value="/usr/bin/npx"),
|
||||
patch.object(ts_quality_gate.subprocess, "run", side_effect=[compact_failure, lint_success]),
|
||||
):
|
||||
has_errors, output = ts_quality_gate._run_eslint(cwd, files)
|
||||
|
||||
assert has_errors is False
|
||||
assert output == ""
|
||||
@@ -20,7 +20,8 @@ import os
|
||||
import re
|
||||
import shutil
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
from ts_project_detection import get_cwd, is_typescript_project
|
||||
|
||||
# ─── Dev Server Command Detection ────────────────────────────────────────────
|
||||
|
||||
@@ -75,6 +76,10 @@ def main() -> None:
|
||||
if data.get("tool_name") != "Bash":
|
||||
sys.exit(0)
|
||||
|
||||
cwd = get_cwd()
|
||||
if not is_typescript_project(cwd):
|
||||
sys.exit(0)
|
||||
|
||||
cmd: str = data.get("tool_input", {}).get("command", "")
|
||||
if not cmd or not _DEV_SERVER_RE.search(cmd):
|
||||
sys.exit(0)
|
||||
@@ -101,8 +106,7 @@ def main() -> None:
|
||||
sys.exit(0)
|
||||
|
||||
# ── Transform: wrap command in a named tmux session ────────────────────
|
||||
cwd = os.environ.get("CLAUDE_CWD", os.getcwd())
|
||||
session_name = _sanitize_session_name(Path(cwd).name)
|
||||
session_name = _sanitize_session_name(cwd.name)
|
||||
escaped_cmd = _escape_for_single_quotes(cmd)
|
||||
|
||||
tmux_cmd = (
|
||||
|
||||
@@ -17,6 +17,8 @@ import sys
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
from ts_project_detection import get_cwd, is_typescript_project
|
||||
|
||||
# ─── Naming Convention Configuration ──────────────────────────────────────────
|
||||
|
||||
# Compound suffixes used in NestJS — order matters (longest first)
|
||||
@@ -157,6 +159,9 @@ def main() -> None:
|
||||
if not file_path:
|
||||
sys.exit(0)
|
||||
|
||||
if not is_typescript_project(get_cwd()):
|
||||
sys.exit(0)
|
||||
|
||||
error = _validate(file_path)
|
||||
if error:
|
||||
message = f"TypeScript file structure violation:\n {error}\n\nCorrect the file name before proceeding."
|
||||
|
||||
@@ -17,6 +17,8 @@ import re
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
from ts_project_detection import get_cwd, is_typescript_project
|
||||
|
||||
# ─── NestJS Component Patterns ────────────────────────────────────────────────
|
||||
|
||||
# Maps NestJS compound file suffix → at least one of these strings must appear
|
||||
@@ -197,6 +199,9 @@ def main() -> None:
|
||||
if not file_path or not content:
|
||||
sys.exit(0)
|
||||
|
||||
if not is_typescript_project(get_cwd()):
|
||||
sys.exit(0)
|
||||
|
||||
# Only TypeScript / TSX files
|
||||
if not (file_path.endswith(".ts") or file_path.endswith(".tsx")):
|
||||
sys.exit(0)
|
||||
|
||||
@@ -15,12 +15,13 @@ Zero external dependencies — pure Python 3 standard library only.
|
||||
"""
|
||||
|
||||
import json
|
||||
import os
|
||||
import shutil
|
||||
import subprocess
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
from ts_project_detection import get_cwd, is_typescript_project
|
||||
|
||||
# ─── Target file extensions ───────────────────────────────────────────────────
|
||||
|
||||
_FORMATTABLE: tuple[str, ...] = (".ts", ".tsx", ".js", ".jsx", ".mts", ".cts", ".mjs")
|
||||
@@ -122,7 +123,10 @@ def main() -> None:
|
||||
if not resolved.exists():
|
||||
sys.exit(0)
|
||||
|
||||
cwd = Path(os.environ.get("CLAUDE_CWD", os.getcwd()))
|
||||
cwd = get_cwd()
|
||||
if not is_typescript_project(cwd):
|
||||
sys.exit(0)
|
||||
|
||||
root = _find_project_root(resolved)
|
||||
|
||||
if not _has_prettier(root):
|
||||
|
||||
@@ -20,6 +20,8 @@ import sys
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
from ts_project_detection import is_typescript_project
|
||||
|
||||
# ─── Configuration ────────────────────────────────────────────────────────────
|
||||
|
||||
# Maximum number of modified files to check (guards against huge diffs)
|
||||
@@ -31,6 +33,8 @@ TOOL_TIMEOUT = 90
|
||||
# Maximum output characters per tool to show Claude
|
||||
MAX_OUTPUT_CHARS = 2000
|
||||
|
||||
COMPACT_FORMATTER_MISSING = "The compact formatter is no longer part of core ESLint"
|
||||
|
||||
# Directories excluded from file detection
|
||||
EXCLUDED_DIRS: frozenset[str] = frozenset(
|
||||
{"node_modules", "dist", "build", ".next", ".turbo", ".cache", "generated"}
|
||||
@@ -188,19 +192,31 @@ def _run_eslint(cwd: Path, files: list[str]) -> tuple[bool, str]:
|
||||
if not shutil.which("eslint") and not shutil.which("npx"):
|
||||
return False, ""
|
||||
|
||||
cmd = ["npx", "eslint", "--format", "compact", *files]
|
||||
compact_cmd = ["npx", "eslint", "--format", "compact", *files]
|
||||
fallback_cmd = ["npx", "eslint", *files]
|
||||
|
||||
try:
|
||||
result = subprocess.run(
|
||||
cmd,
|
||||
compact_cmd,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
cwd=cwd,
|
||||
timeout=TOOL_TIMEOUT,
|
||||
)
|
||||
output = result.stdout + result.stderr
|
||||
|
||||
if COMPACT_FORMATTER_MISSING in output:
|
||||
result = subprocess.run(
|
||||
fallback_cmd,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
cwd=cwd,
|
||||
timeout=TOOL_TIMEOUT,
|
||||
)
|
||||
output = result.stdout + result.stderr
|
||||
|
||||
if result.returncode == 0:
|
||||
return False, ""
|
||||
output = result.stdout + result.stderr
|
||||
return True, output[:MAX_OUTPUT_CHARS]
|
||||
except (subprocess.TimeoutExpired, FileNotFoundError):
|
||||
return False, ""
|
||||
@@ -242,6 +258,8 @@ def main() -> None:
|
||||
input_data = {}
|
||||
|
||||
cwd = Path(input_data.get("cwd", os.environ.get("CLAUDE_CWD", os.getcwd())))
|
||||
if not is_typescript_project(cwd):
|
||||
sys.exit(0)
|
||||
|
||||
# Get modified files
|
||||
modified = _get_modified_files(cwd)
|
||||
|
||||
@@ -19,6 +19,8 @@ import sys
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
from ts_project_detection import get_cwd, is_typescript_project
|
||||
|
||||
# State directory lives under $CLAUDE_CWD/.claude/ (project-local, not world-readable)
|
||||
_STATE_FILENAME_PREFIX = ".ts-rules-pending-"
|
||||
|
||||
@@ -123,7 +125,10 @@ def main() -> None:
|
||||
if not file_path or not any(file_path.endswith(ext) for ext in TS_EXTENSIONS):
|
||||
sys.exit(0)
|
||||
|
||||
cwd = Path(os.environ.get("CLAUDE_CWD", os.getcwd()))
|
||||
cwd = get_cwd()
|
||||
if not is_typescript_project(cwd):
|
||||
sys.exit(0)
|
||||
|
||||
rules_dir = cwd / ".claude" / "rules"
|
||||
if not rules_dir.is_dir():
|
||||
sys.exit(0)
|
||||
|
||||
@@ -20,6 +20,8 @@ import sys
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
from ts_project_detection import get_cwd, is_typescript_project
|
||||
|
||||
# Must match ts-rules-tracker.py
|
||||
_STATE_FILENAME_PREFIX = ".ts-rules-pending-"
|
||||
|
||||
@@ -94,6 +96,9 @@ def main() -> None:
|
||||
except (json.JSONDecodeError, ValueError):
|
||||
pass
|
||||
|
||||
if not is_typescript_project(get_cwd()):
|
||||
sys.exit(0)
|
||||
|
||||
entries = _consume_state()
|
||||
if not entries:
|
||||
sys.exit(0)
|
||||
|
||||
@@ -12,11 +12,12 @@ Zero external dependencies — pure Python 3 standard library only.
|
||||
"""
|
||||
|
||||
import json
|
||||
import os
|
||||
import subprocess
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
from ts_project_detection import get_cwd, is_typescript_project
|
||||
|
||||
# ─── Configuration ────────────────────────────────────────────────────────────
|
||||
|
||||
# Maximum characters for TODO.md content to avoid flooding the context
|
||||
@@ -136,19 +137,21 @@ def main() -> None:
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
cwd = os.environ.get("CLAUDE_CWD", os.getcwd())
|
||||
cwd = get_cwd()
|
||||
if not is_typescript_project(cwd):
|
||||
sys.exit(0)
|
||||
|
||||
sections: list[str] = []
|
||||
|
||||
project = _project_section(cwd)
|
||||
project = _project_section(str(cwd))
|
||||
if project:
|
||||
sections.append(project)
|
||||
|
||||
git = _git_section(cwd)
|
||||
git = _git_section(str(cwd))
|
||||
if git:
|
||||
sections.append(git)
|
||||
|
||||
todos = _todo_section(cwd)
|
||||
todos = _todo_section(str(cwd))
|
||||
if todos:
|
||||
sections.append(todos)
|
||||
|
||||
|
||||
@@ -0,0 +1,83 @@
|
||||
#!/usr/bin/env python3
|
||||
"""Shared TypeScript project detection helpers for plugin hooks."""
|
||||
|
||||
import json
|
||||
import os
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
_EXCLUDED_DIRS: frozenset[str] = frozenset(
|
||||
{"node_modules", ".git", "dist", "build", ".next", ".turbo", ".cache", "coverage"}
|
||||
)
|
||||
_TS_EXTENSIONS: tuple[str, ...] = (".ts", ".tsx", ".mts", ".cts")
|
||||
_TS_PACKAGES: frozenset[str] = frozenset(
|
||||
{"typescript", "ts-node", "tsx", "ts-jest", "@swc-node/register"}
|
||||
)
|
||||
|
||||
|
||||
def get_cwd() -> Path:
|
||||
"""Return the Claude working directory as a Path."""
|
||||
return Path(os.environ.get("CLAUDE_CWD", os.getcwd()))
|
||||
|
||||
|
||||
def _package_declares_typescript(package_json: Path) -> bool:
|
||||
try:
|
||||
data = json.loads(package_json.read_text(encoding="utf-8"))
|
||||
except (OSError, ValueError):
|
||||
return False
|
||||
|
||||
dependency_blocks = (
|
||||
data.get("dependencies", {}),
|
||||
data.get("devDependencies", {}),
|
||||
data.get("peerDependencies", {}),
|
||||
data.get("optionalDependencies", {}),
|
||||
)
|
||||
|
||||
return any(pkg in deps for deps in dependency_blocks for pkg in _TS_PACKAGES)
|
||||
|
||||
|
||||
def _directory_has_typescript_markers(path: Path) -> bool:
|
||||
try:
|
||||
if any(path.glob("tsconfig*.json")):
|
||||
return True
|
||||
except OSError:
|
||||
return False
|
||||
|
||||
package_json = path / "package.json"
|
||||
return package_json.exists() and _package_declares_typescript(package_json)
|
||||
|
||||
|
||||
def _scan_descendants(path: Path, max_depth: int = 3) -> bool:
|
||||
try:
|
||||
for root, dirs, files in os.walk(path):
|
||||
root_path = Path(root)
|
||||
depth = len(root_path.relative_to(path).parts)
|
||||
dirs[:] = [d for d in dirs if d not in _EXCLUDED_DIRS]
|
||||
|
||||
if depth >= max_depth:
|
||||
dirs[:] = []
|
||||
|
||||
if any(name.startswith("tsconfig") and name.endswith(".json") for name in files):
|
||||
return True
|
||||
|
||||
if any(Path(name).suffix in _TS_EXTENSIONS for name in files):
|
||||
return True
|
||||
|
||||
package_json = root_path / "package.json"
|
||||
if package_json.exists() and _package_declares_typescript(package_json):
|
||||
return True
|
||||
except OSError:
|
||||
return False
|
||||
|
||||
return False
|
||||
|
||||
|
||||
def is_typescript_project(cwd: Optional[Path] = None) -> bool:
|
||||
"""Return True when the current workspace looks like a TypeScript project."""
|
||||
current = (cwd or get_cwd()).resolve()
|
||||
|
||||
for candidate in [current, *list(current.parents)[:6]]:
|
||||
if _directory_has_typescript_markers(candidate):
|
||||
return True
|
||||
|
||||
return _scan_descendants(current)
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "github-spec-kit",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"description": "GitHub specification integration and verification",
|
||||
"author": {
|
||||
"name": "Giuseppe Trisciuoglio",
|
||||
|
||||
+51
-22
@@ -2,7 +2,7 @@
|
||||
"""
|
||||
agents_loop.py — Universal Ralph Loop automation for multiple AI agents.
|
||||
|
||||
Supports: claude, kimi, codex, copilot, gemini, qwen, glm4, minimax, openrouter
|
||||
Supports: claude, kimi, codex, copilot, gemini, qwen, glm4, minimax, openrouter, kiro
|
||||
|
||||
Usage:
|
||||
agents_loop --spec=docs/specs/001-feature --agent=claude
|
||||
@@ -245,6 +245,18 @@ AGENTS = {
|
||||
"prompt_arg": True,
|
||||
"prompt_flag": "-p", # Must be before prompt value
|
||||
},
|
||||
"kiro": {
|
||||
"name": "Kiro CLI",
|
||||
"cmd": ["kiro-cli", "chat", "--no-interactive"],
|
||||
"stdin_mode": False,
|
||||
"supports_flags": True,
|
||||
"supports_model": False,
|
||||
"supports_yolo": True,
|
||||
"supports_streaming": False, # Headless mode - no TUI streaming
|
||||
"yolo_flag": "--trust-all-tools", # Auto-approve all tool calls in headless mode
|
||||
"prompt_arg": True,
|
||||
# Prompt is positional after flags (no prompt_flag needed)
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
@@ -261,7 +273,7 @@ def parse_args():
|
||||
"--agent",
|
||||
default="codex",
|
||||
choices=list(AGENTS.keys()),
|
||||
help="AI agent to use: claude, kimi, codex, copilot, gemini, qwen, glm4, minimax, openrouter, auto (default: codex). Use 'auto' for intelligent agent selection by workflow phase.",
|
||||
help="AI agent to use: claude, kimi, codex, copilot, gemini, qwen, glm4, minimax, openrouter, kiro, auto (default: codex). Use 'auto' for intelligent agent selection by workflow phase.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--action",
|
||||
@@ -284,7 +296,7 @@ def parse_args():
|
||||
"--dangerously-bypass-approvals",
|
||||
action=argparse.BooleanOptionalAction,
|
||||
default=True,
|
||||
help="Enable YOLO mode (bypass all approvals). Uses agent-specific flag: codex (--dangerously-bypass-approvals-and-sandbox), claude/glm4/minimax (--dangerously-skip-permissions), gemini/qwen (-y), kimi (--yolo), copilot (--allow-all). (default: enabled).",
|
||||
help="Enable YOLO mode (bypass all approvals). Uses agent-specific flag: codex (--dangerously-bypass-approvals-and-sandbox), claude/glm4/minimax (--dangerously-skip-permissions), gemini/qwen (-y), kimi (--yolo), copilot (--allow-all), kiro (--trust-all-tools). (default: enabled).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--full-auto",
|
||||
@@ -300,7 +312,7 @@ def parse_args():
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model",
|
||||
help="Model to use (e.g. claude: sonnet/opus/haiku, codex: gpt-5.4/o3, gemini: gemini-3-pro, qwen: qwen-plus, kimi: kimi-k1.5, glm4: glm-4-plus, minimax: abab6.5s, copilot: gpt-4).",
|
||||
help="Model to use (e.g. claude: sonnet/opus/haiku, codex: gpt-5.4/o3, gemini: gemini-3-pro, qwen: qwen-plus, kimi: kimi-k1.5, glm4: glm-4-plus, minimax: abab6.5s, copilot: gpt-4). Kiro does not support model selection.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-C", "--workdir",
|
||||
@@ -375,7 +387,7 @@ def parse_args():
|
||||
"--reviewer",
|
||||
default=None,
|
||||
choices=list(AGENTS.keys()),
|
||||
help="Agent to use specifically for review steps: claude, kimi, codex, copilot, gemini, qwen, glm4, minimax, openrouter, auto (default: use --agent). Overrides auto-mode selection for review steps.",
|
||||
help="Agent to use specifically for review steps: claude, kimi, codex, copilot, gemini, qwen, glm4, minimax, openrouter, kiro, auto (default: use --agent). Overrides auto-mode selection for review steps.",
|
||||
)
|
||||
return parser.parse_args()
|
||||
|
||||
@@ -463,7 +475,7 @@ def extract_command_from_output(stdout: str, agent: str) -> Optional[str]:
|
||||
# Fallback: search for command patterns
|
||||
# NOTE: Patterns require at least one letter to avoid matching progress indicators like "/26"
|
||||
for line in lines:
|
||||
if agent in ("claude", "kimi", "gemini", "qwen"):
|
||||
if agent in ("claude", "kimi", "gemini", "qwen", "kiro"):
|
||||
# Slash-prefixed commands: require first char after / to be a letter
|
||||
match = re.search(r'(/[a-zA-Z][\w:-]*[^\n`]*)', line)
|
||||
else:
|
||||
@@ -480,27 +492,41 @@ def extract_command_from_output(stdout: str, agent: str) -> Optional[str]:
|
||||
|
||||
# Non-interactive mode instructions - prepended to all prompts
|
||||
# This ensures agents don't ask questions when there's no human in the loop
|
||||
NON_INTERACTIVE_PREFIX = """[CRITICAL: NON-INTERACTIVE MODE]
|
||||
You are running in FULLY AUTOMATED mode. There is NO human in the loop to answer questions.
|
||||
NON_INTERACTIVE_PREFIX = """
|
||||
<rules>
|
||||
[CRITICAL: NON-INTERACTIVE MODE]
|
||||
You are running in FULLY AUTOMATED mode. There is NO human in the loop to answer questions.
|
||||
|
||||
STRICT RULES:
|
||||
1. DO NOT ask the user any questions
|
||||
2. DO NOT use AskUserQuestion or similar tools
|
||||
3. DO NOT prompt for confirmation or choices (A/B/C/D)
|
||||
4. ALWAYS proceed with the RECOMMENDED or DEFAULT option
|
||||
5. If multiple options exist, choose the SAFEST and MOST CONSERVATIVE approach
|
||||
6. Make your best judgment and EXECUTE immediately
|
||||
7. Report what you did, don't ask what to do
|
||||
|
||||
If you encounter ambiguities, use your expertise to decide and proceed.
|
||||
If you need clarification, make a reasonable assumption and document it.
|
||||
STRICT RULES:
|
||||
1. DO NOT ask the user any questions
|
||||
2. DO NOT use AskUserQuestion or similar tools
|
||||
3. DO NOT prompt for confirmation or choices (A/B/C/D)
|
||||
4. ALWAYS proceed with the RECOMMENDED or DEFAULT option
|
||||
5. If multiple options exist, choose the SAFEST and MOST CONSERVATIVE approach
|
||||
6. Make your best judgment and EXECUTE immediately
|
||||
7. Report what you did, don't ask what to do
|
||||
8. You need to write a concise report. You need to minimize the use of tokens in the output.
|
||||
9. Update the task file document when you finish your task.
|
||||
No one reads your summaries, so either don't write them at all, or keep them brief.
|
||||
|
||||
If you encounter ambiguities, use your expertise to decide and proceed.
|
||||
If you need clarification, make a reasonable assumption and document it.
|
||||
If you need documentation try in `docs/specs` folders find it.
|
||||
</rules>
|
||||
---
|
||||
|
||||
"""
|
||||
|
||||
REVIEW_PREFIX = """
|
||||
<review>
|
||||
When you complete a review. You need write a `TASK-XXX-review.md` file with your review.
|
||||
It's mandatory. You can't skip this. It's very important for loop.
|
||||
</review>
|
||||
---
|
||||
|
||||
def run_agent(agent: str, prompt: str, args) -> int:
|
||||
"""
|
||||
|
||||
def run_agent(agent: str, prompt: str, step: str, args) -> int:
|
||||
"""Run the specified agent with the given prompt.
|
||||
|
||||
For claude-based agents (claude, glm4, minimax, openrouter), this uses
|
||||
@@ -509,7 +535,10 @@ def run_agent(agent: str, prompt: str, args) -> int:
|
||||
agent_config = AGENTS[agent]
|
||||
|
||||
# Prepend non-interactive instructions to prevent questions
|
||||
full_prompt = NON_INTERACTIVE_PREFIX + prompt
|
||||
if step == "review":
|
||||
full_prompt = NON_INTERACTIVE_PREFIX + REVIEW_PREFIX + prompt
|
||||
else:
|
||||
full_prompt = NON_INTERACTIVE_PREFIX + prompt
|
||||
|
||||
if args.dry_run:
|
||||
model_str = ""
|
||||
@@ -1300,7 +1329,7 @@ def main():
|
||||
print(f" → Executing with {AGENTS[effective_agent]['name']}...")
|
||||
print(f" 📝 Command preview: {command[:100]}{'...' if len(command) > 100 else ''}")
|
||||
|
||||
exit_code = run_agent(effective_agent, command, args)
|
||||
exit_code = run_agent(effective_agent, command, step, args)
|
||||
|
||||
if exit_code != 0:
|
||||
print(f" ⚠️ Agent exited with code {exit_code}", file=sys.stderr)
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"name": "giuseppe-trisciuoglio/developer-kit",
|
||||
"version": "2.8.1",
|
||||
"version": "2.8.2",
|
||||
"private": false,
|
||||
"summary": "Comprehensive developer toolkit providing reusable skills for Java/Spring Boot, TypeScript/NestJS/React/Next.js, Python, PHP, AWS CloudFormation, AI/RAG, DevOps, and more.",
|
||||
"skills": {
|
||||
@@ -106,6 +106,9 @@
|
||||
"better-auth": {
|
||||
"path": "plugins/developer-kit-typescript/skills/better-auth/SKILL.md"
|
||||
},
|
||||
"bug-fix-brief": {
|
||||
"path": "plugins/developer-kit-core/skills/bug-fix-brief/SKILL.md"
|
||||
},
|
||||
"chunking-strategy": {
|
||||
"path": "plugins/developer-kit-ai/skills/chunking-strategy/SKILL.md"
|
||||
},
|
||||
@@ -118,6 +121,9 @@
|
||||
"codex": {
|
||||
"path": "plugins/developer-kit-tools/skills/codex/SKILL.md"
|
||||
},
|
||||
"create-pr-from-spec": {
|
||||
"path": "plugins/developer-kit-specs/skills/create-pr-from-spec/SKILL.md"
|
||||
},
|
||||
"copilot-cli": {
|
||||
"path": "plugins/developer-kit-tools/skills/copilot-cli/SKILL.md"
|
||||
},
|
||||
|
||||
Reference in New Issue
Block a user